Private AI infrastructure without the token meter. Fixed-cost access to leading open models, image generation, OCR, web search & more - with Zero Data Retention
5/ Credit where credit is due - @erans' project @lunaroute_ai flipped the bit for me on using AI without worrying about token cost thanks to their concurrency based billing.
We are not on openrouter because openrouter charges by the token. We used openrouter's benchmark harness https://t.co/4un0HW60JV to run the tests and we will release the results soon.
We also schedule requests differently into the clusters and that is a big part of our secret sauce.
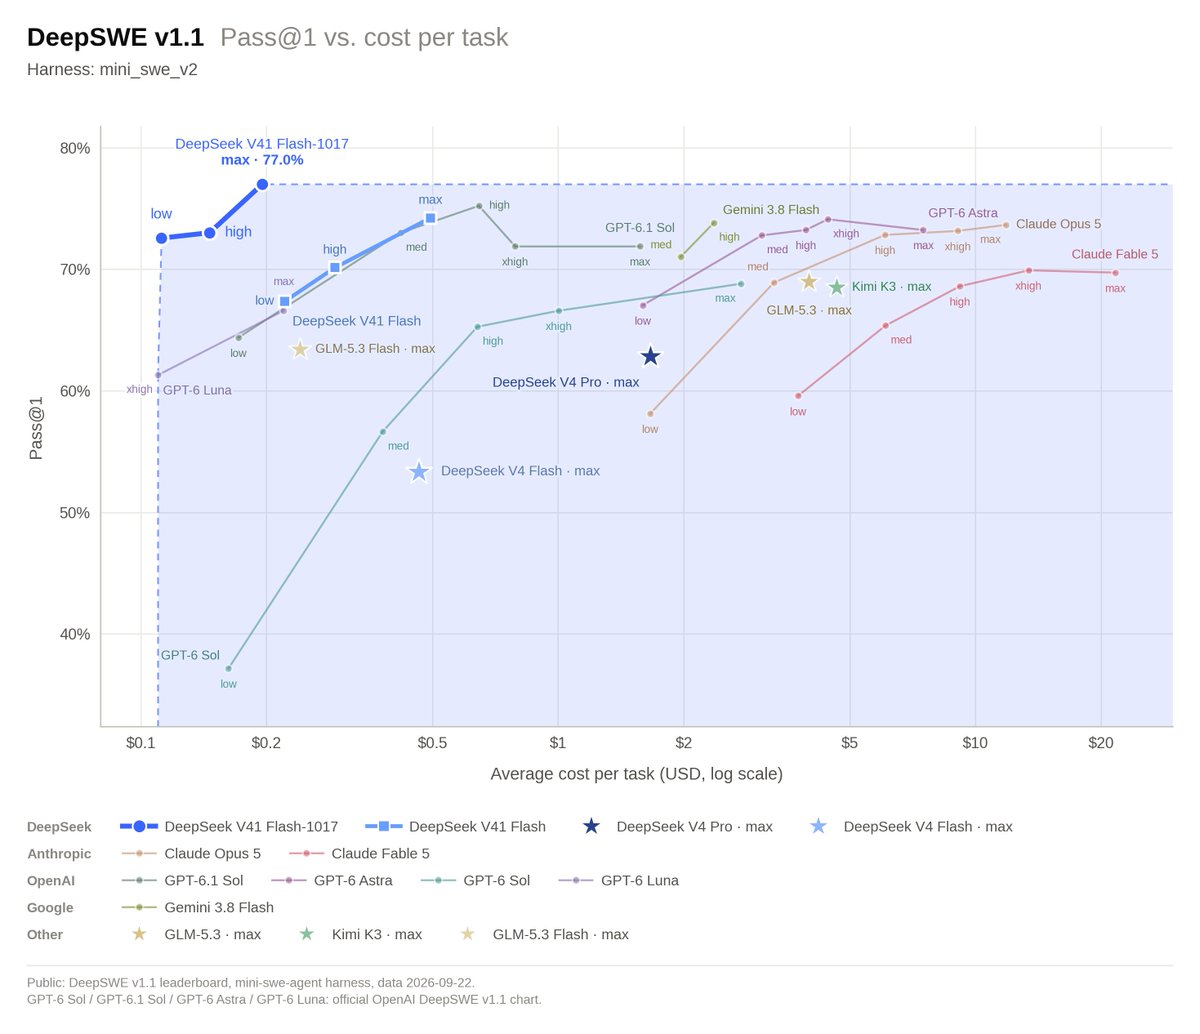
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
LunaRoute opens a mental barrier that we put on ourselves!
@joeysim is a very happy early users. Join him - Free 7 days trial for Meta Muse Spark Open, GLM 5.3, GLM 5.3 Flash and DeepSeek 4.1 Flash.
You owe it to your creativity!
Meta Muse Spark Open is now on LunaRoute!
A strong US-developed open-weight model, particularly impressive for long-running agents and background tasks.
🇺🇸 US servers
🔒 Zero Data Retention
💰 Fixed-cost inference
🎁 7-day free trial
https://t.co/gVF3qkoJJZ
@mattdeitke@huggingface We have it running on day 1 (or is it 0) on https://t.co/APMPxCaD5P - private, fixed cost inference on US server. 7 days free trial. Really!
Same model. Same hardware.
We changed how we scheduled the work and latency went from 2.7s → 0.4s.
There’s a lot more to inference than the model name.
The model is not the product.
https://t.co/CFgTfJcbar
I'm really excited for Beam. Don't follow the benchmarks as this is the first model. Muse Spark 1.0 was also meh, but fast iterations into 1.3 and its quite good (1.2 was also good).
If @reflection_ai keep their pace it would be awesome soon.
Also, make sure to check it on your actual workloads! Benchmarks are nice but rarely tell the full story.
It's inside but Matt has tested LunaRoute and have a number of friends using it as their daily driver!
Talk to us (or to @erans) or just go to https://t.co/a7oPoojHAH and check it out.
And yes, we do have clef-flash and djev as too great Jev like decision models. Both supports images!
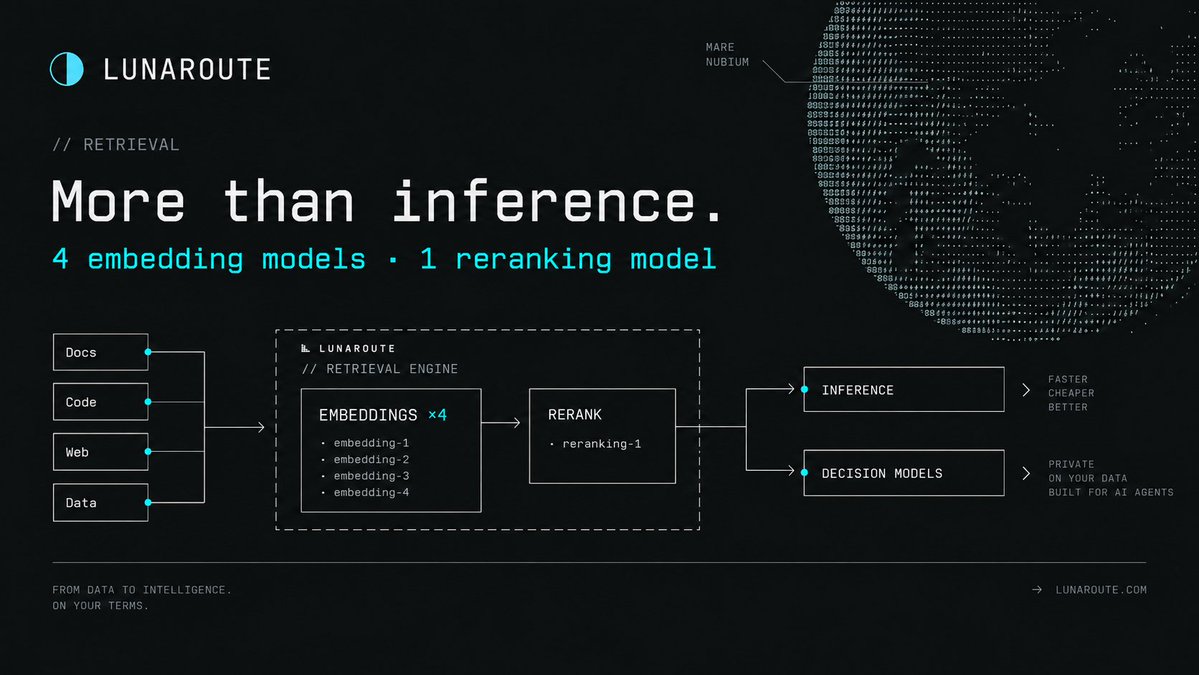
LunaRoute is more than inference.
Alongside our inference and decision models, we now also have:
- 4 embedding models
- 1 reranking model
That means more of the AI stack can run in one place - from finding the right context, to ranking it, to reasoning over it.
And, like the rest of LunaRoute, you don’t have to think token by token while you build.
LunaRoute has 2 Jev style models available as part of all subscriptions:
- kev-4b
- djev - GemmaDiffusion 25B and supports images!
Come and check us out!
LunaRoute is live: fixed-cost private AI capacity for teams tired of rationing tokens.
Proud to have backed @lunaroute_ai in their first round. Congrats @erans, Gur and team.
For the last few months I have been testing @lunaroute_ai - which gives basically unlimited tokens to OSS models for a monthly price.
It has changed the way I think about how AI will be used. Worth trying.
You can get an extra $200 via my referral https://t.co/nkUch2UnSW
Some things I have done with @lunaroute_ai
1. Have agents go through entire codebases frequently for review/ refactors
2. Analyzing all of my claude and codex sessions to identify how decide things and create a plugin to predict my decision