to give them the benefits of the doubt
they do good stuff but they sometimes ruin the models themselves like the model in english text is acting normally but when trying with arabic text, it just pretend it doesnt comprehend language compared to actual oss model
so better eval models to know if they still work for ur use cases cuz fast + bad isnt a good combo especially for systems that should rely on reliability
🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 https://t.co/JGAik1kgk0
1/4
We REMOVED upto 10 WHOLE layers from Qwen3-8B-Base using LaCo (Layer Collapse).
Upon deleting only 6 layers, the model got 16.7% smaller, keeping 78-94% of its reasoning scores at a 1.68x perplexity ratio.
Code and pruned weights are up on our Hugging Face.
Here are insights from our research :
BIG NEWS!
My ~8 hour course on AI data centers is now live on @freeCodeCamp!
From Watts to Tokens: 16 chapters covering grid power, 800V DC racks, liquid cooling, networking and GPU cloud economics.
https://t.co/Bolpv7M1se
لما كنت شغال ابني arabic OCR
بديت اسوي eval لأغلبية النماذج، منهم VLMs وtraditional CV
لاحظت ان كل VLMs يسوون نفس الأغلاط مهما كانت احجامهم ومن سواهم
> يحطون حركات من عندهم
> يترجمون الكلام المكتوب
> والأغرب، كانوا ما يشوفون الكلمات العشوائية حتى لو كانت واضحه!
هنا عرفت شيء جديد ان VLMs يمكن رفعوا جودة مخرجات OCR ولكن كونوا مشاكل جديدة نا كانت موجوده من قبل...
We were able to fine tune an open weight model (Qwen3.5-9B) on proprietary internal data at @coinbase, and it out performed frontier models, at much lower cost and speed, for a specialized task (fraud prevention in this case).
I think we'll see more of this pattern inside companies. The frontier models are amazing generalists. But increasingly you'll see specialist models out perform on more narrow tasks, either working on teams, or by themselves.
We're making it easy to fine tune models internally for our employees. We even have a skill for it in our internal harness that makes it easy to spin these up and start training them:
"/fine-tune-and-serve-llm I want to fine-tune Qwen for payments risk review. help me get started"
I imagine we'll have some backend services that could be replaced entirely by this new architecture.
it's crazy how easy it is to spot 10x engineers these days
for a certain set of people LLMs totally unlocked their potential
to the point where imagining their life before this seems totally depressing
LLM Inference Engineering - Problem and Solution
Problem: LLMs are slow
Solution: KV Cache - Avoid recomputing previous tokens.
Problem: KV Cache consumes huge memory
Solution: PagedAttention - Manage KV memory efficiently.
Problem: GPU is underutilized
Solution: Continuous Batching - Dynamically add/remove requests.
Problem: Token generation is sequential
Solution: Speculative Decoding - Generate and verify multiple tokens together.
Problem: Attention requires large memory usage and expensive memory movement
Solution: FlashAttention - Reduce memory usage and memory movement during attention.
Problem: KV Cache is still large
Solution: MQA / GQA - Share K/V across multiple query heads.
Problem: Many optimizations need to work together
Solution: vLLM - Build an efficient inference engine.
Problem: Applications repeatedly process the same prefixes
Solution: RadixAttention / Prefix Caching - Reuse previously computed work.
Problem: Models are too large
Solution: Quantization - Reduce model memory and computation.
Problem: Large models are expensive
Solution: Distillation / SLMs / MoE - Make inference itself cheaper.
Keep Learning, Keep Sharing, and Keep Growing.
In agentic AI, log every step.
Every LLM call, tool call, trace, span, decision, input, and output.
Log the reasoning signals wherever possible.
If you can’t observe what your agent is doing, you can’t reliably debug it.
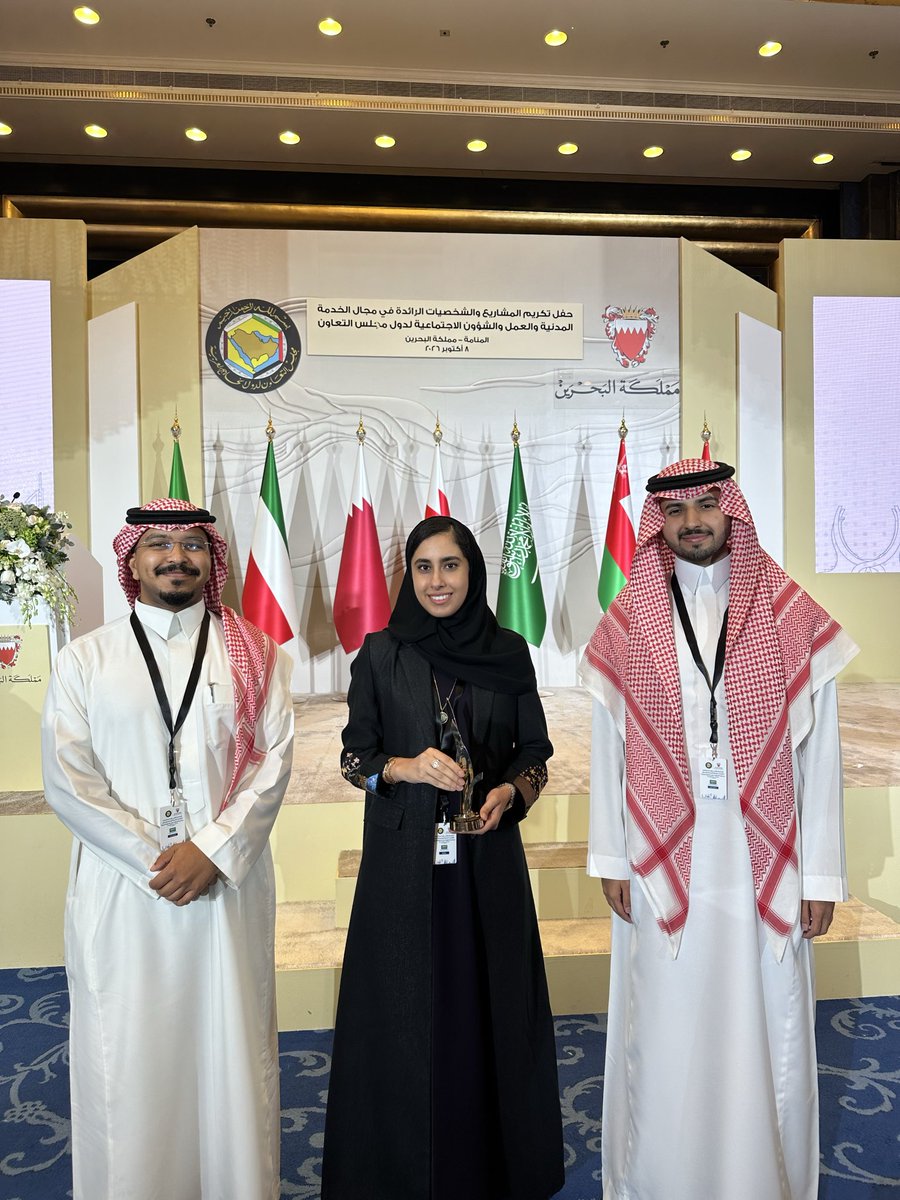
سعداء بتكريم @DalData_sa في مملكة البحرين، ضمن تكريم الكفاءات والمشاريع الرائدة في العمل الاجتماعي على مستوى دول مجلس التعاون الخليجي.
كل الشكر ل @HRSD_SA على ترشيح الجمعية، ولمعالي المهندس @Ahmed_S_Alrajhi على دعمه وتقديره لجهود دال.
تكريم نفخر به، ودافع لنا لمواصلة الأثر في مجال البيانات والذكاء الاصطناعي.
@ma7dev المال قد يأتيك من أبواب كثيرة بعد توفيق الله..
لكن الأثر عزيز، لا يُمنح لمجرد السعي إليه، بل لعظمة النية التي تقف خلفه.
فالخير والشر كلاهما قد يترك أثرًا، لكن ما يصنع الفرق هو صدق النية وعمقها.
والتاريخ خير دليل