🚨 THE TERMINATOR JUST FOUGHT A HUMAN IN A CAGE.
For the first time, a full-size humanoid robot fought a human in San Francisco.
EngineAI’s 6-foot T800 went up against creator Frankie LaPenna and knocked him to the canvas with a brutal kick.
The scary part? This wasn’t CGI or a staged movie scene. It was a real physical machine throwing real strikes.
One important detail: the T800 was remotely controlled by a human operator, so this is NOT an autonomous AI fighter yet.
But EngineAI’s T800 can already deliver up to 450 N·m of peak joint torque and 14,000 W of instantaneous joint power.
We’re still one big step away from Terminator.
But the hardware is getting very real.
And honestly, I’m not sure humans should be the ones testing it in a cage.
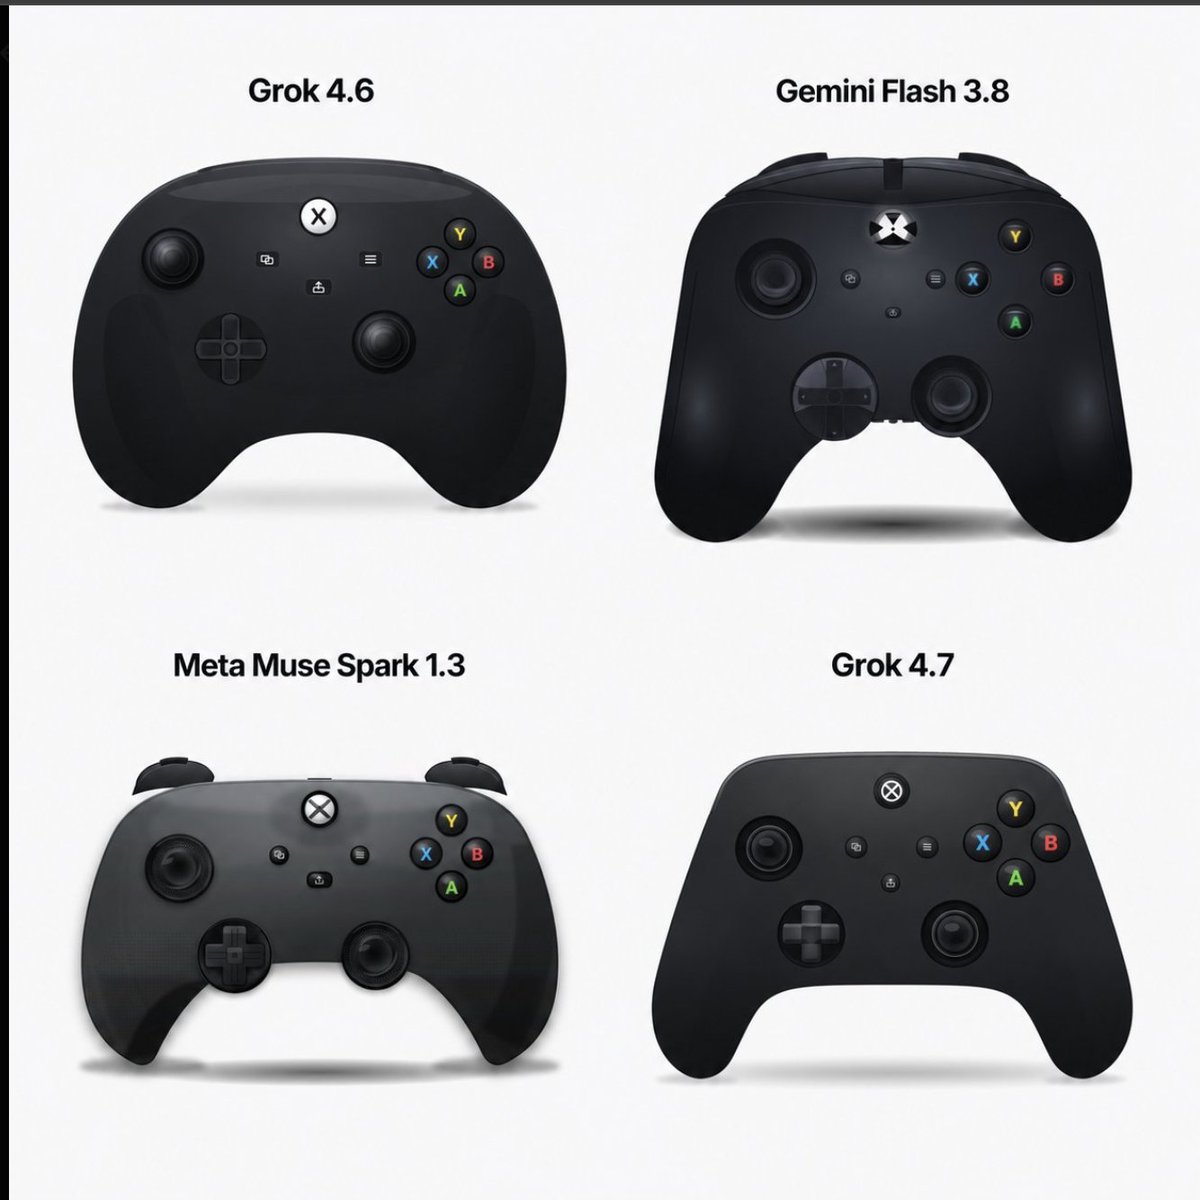
🚨 GROK 4.7 GENERATED AN XBOX CONTROLLER FROM AN SVG PROMPT AND THE JUMP FROM 4.6 IS OBVIOUS
Four models, same task, side by side.
Grok 4.6's attempt is rougher, bulkier proportions, buttons floating slightly off from where you'd expect them.
Gemini Flash 3.8 goes for a more angled, stylized shell, decent shape but the layout reads a bit cluttered.
Meta Muse Spark 1.3 is closer to right, cleaner button spacing, but the grips look thin compared to a real controller.
Grok 4.7 is the one that actually looks like it understood the brief, proportions are tighter, the face buttons sit where your thumb expects them, and the whole shape reads as a controller from a glance instead of "controller-ish blob."
Not perfect, the trigger bumps and back paddles are still a bit off. But this is a real jump from 4.6, and reportedly the model performs noticeably better specifically inside Grok Build compared to standalone chat.
SVG generation keeps turning into the actual benchmark nobody officially agreed on, but everyone keeps using anyway.
🚨 GROK 4.7 IS HERE - AND IT'S A PRETTY SOLID UPGRADE
xAI kept the price exactly the same:
$2/M input
$6/M output
But the benchmark gains are noticeable.
51.8% on CursorBench 4.0
57.9% on Terminal-Bench 4.0
62.1% on HealthBench Professional
It also beats Sol on several real-world tasks while staying at the same price.
Not a revolution. Just a damn good upgrade.
And honestly, I'll take that.
🚨 CLAUDE CODE JUST GOT A SMARTER MODEL ROUTER
A new Claude Code mod can automatically route every request to the right model and effort level.
It classifies:
→ subagent model
→ main model
→ reasoning/effort level
And it can plug into the Typesafe AI API or Vercel AI Gateway.
The interesting part?
One install command.
Instead of manually deciding which model should handle each task, the router makes that decision automatically.
Cheap model for simple work.
Stronger model when the task actually needs it.
More reasoning only when it's worth the extra cost.
That's exactly where AI coding workflows are heading:
Not one model doing everything.
A system deciding which model should do what.
📋 THE "EVERYTHING DROPS NEXT MONTH" LIST GOING AROUND ISN'T WRONG, BUT IT'S NOT ONE TIER OF CONFIDENCE EITHER
Here's the same six names, sorted by how solid the ground actually is right now.
Actually has a leak trail:
Kimi K3.1 — a named leaker says it's already in post-training, October window. Moonshot also just reopened subscriptions on Sept 18, which lines up with a launch push. Real signal, single source.
GPT-6 Sol — separate budget tier of the GPT-6 lineup, not a quality upgrade over Astra, a faster/cheaper one. DevDay Sept 29 is the rumored window.
Gemini 4 Pro — the Arena checkpoint story we've been tracking. Outputs look real. Still zero model card, zero API id as of today.
Thin or single-source:
Grok 4.8/4.7 — notice the list itself can't even settle on a number. That's usually a sign nobody has an actual spec sheet, just Musk timeline posts.
GLM 5.5 — per the latest tracking, no model card, no weights, no confirmed name. What's circulating is people comparing against GLM-5.3 because 5.5 doesn't exist to test yet.
Basically vibes:
Claude Opus 5.5 — no leak trail resembling the other five. This one looks like someone filled out the format rather than reporting something.
None of this means the list is fake. It means "dropping next month" is doing six different amounts of work depending which line you're reading.
Screenshot this, check back in four weeks, see which ones actually had a model card behind them.
🚨 FABLE 5.2 OUTPUT IS LEAKING AND PEOPLE ARE SAYING IT COOKS GPT-6 ASTRA
This render is what's circulating, a fully interactive product page for a fictional VR headset called Orbit, exploded component views, live camera modules, glowing internal parts, built entirely from a prompt.
The claim going around: Anthropic quietly started routing some Fable 5.1 requests to a new checkpoint inside Claude Code, Chat and Cowork. Testers noticed the swap and started comparing outputs directly against Astra on identical prompts.
The most cited result, from tester @notjazii, running high reasoning mode: Fable 5.2 output described as a clear leap over 5.1, and beating Astra on the same task. Tradeoff noted: slower and more expensive to run.
Here's the part worth being honest about before this gets repeated as fact.
As of right now there's no model card, no API identifier, no listing on Bedrock, Vertex, or OpenRouter, and no statement from Anthropic. Every version of this story traces back to a small number of accounts, not a confirmed source.
That doesn't mean it's fake. Anthropic has quietly routed traffic to unannounced checkpoints before. It just means "leaked" here currently means "routing behavior a few testers noticed," not "official release."
Watch for an actual model identifier showing up in the API before treating this as confirmed.
🚨 GEMINI 4 PRO VS FABLE 5.2 VS GPT-6 ASTRA
Same prompt. Same Xbox controller SVG.
And this might be one of the better tests for how these models actually handle visual coding.
Gemini 4 Pro and Astra both get surprisingly close to the real controller. The overall shape, proportions and details are almost there.
But the interesting part is where each model breaks.
Gemini 4 Pro has its own small mistakes around the logo and grips.
Astra makes different tiny errors.
And now Fable 5.2 enters the comparison.
At this point, the test is almost saturated. We're no longer looking at models that completely fail the task. We're comparing the last 5–10% of visual accuracy.
That's where things get interesting.
Because generating an SVG is easy.
Getting the geometry, proportions, branding and tiny details right without being explicitly told every single one of them is a much harder problem.
Gemini 4 Pro, Fable 5.2 and Astra are now fighting over that last few percent.
And honestly, the differences are getting ridiculously small.
🚨 GEMINI 4 PRO IS GOING HEAD-TO-HEAD WITH OPUS 5.
I gave both models the exact same prompt:
“Create a 3D dragon using Three.js. Use a white background so the main object stays visible.”
Opus 5 was running at Max effort.
Gemini 4 Pro still managed to keep up.
And that’s the interesting part.
This isn’t a benchmark score. It’s the actual output side by side, built from the same prompt.
Gemini 4 Pro is starting to look seriously competitive for complex visual coding.
Which one would you pick?
🚨 SOMEONE BUILT 25 ROOMS WITH CLAUDE LIVING INSIDE EACH ONE, AND IT'S UNHINGED IN THE BEST WAY
Not 25 versions of the same chat window. 25 completely different isometric worlds, hand-illustrated, each one its own vibe, a greenhouse, a print studio, a rooftop, a night street.
And in every single one, Claude is just there. Present. Keeping whoever's in that room company like it belongs in the scene, not bolted onto it.
Built entirely with Claude Opus 5.
This is what happens when someone stops asking "what can AI generate" and starts asking "what if AI just lived somewhere."
Scroll through this and tell me your brain doesn't immediately start picking a favorite room.
🚨 THIS DOES NOT LOOK LIKE A FLASH MODEL.
A mysterious Gemini checkpoint is reportedly being tested in Arena under the Gemini 3.8 Flash label.
The prompt was simple:
“Create a 3D model of WALL-E in Three.js.”
What came out is the crazy part.
A fully interactive 3D WALL-E with tiny animations and extra interactions that weren't even explicitly requested.
The model didn't just follow the prompt.
It added its own behavior.
If this really is the rumored Gemini 4 Pro checkpoint, Google may have something seriously powerful on its hands.
And we're still waiting for the GPT-6 Astra comparison.
That one should be interesting.
🚨 GEMINI 4 IS NOW SHOWING UP IN ARENA.
And the first side-by-side with GPT-6 is already interesting.
Same prompt.
Same goal.
Two frontier models.
Gemini 4's result looks seriously impressive, especially in the way it handles the build and overall execution.
GPT-6 still holds its own, but the gap may be getting a lot smaller than people expected.
If Gemini 4 can consistently match GPT-6 across different tasks, Google may have just entered the next phase of the AI model war.
This is only one comparison.
More tests needed.
🚨 GEMINI 4 PRO JUST MADE ITS OWN SVG DOM LOOK LIKE A TOY
The leaked checkpoint just rendered a full interactive PS5 controller. Not a flat image, an actual working studio.
Exploded CAD view. X-ray PCB mode. Clickable buttons with material specs. Live LED color toggles. Real vector coordinates updating as you drag.
All of it running as pure SVG, zero images, zero canvas hacks.
Took about 10 minutes on high thinking effort to generate.
This is supposedly the same architecture leap being tracked in Arena right now, currently hiding under the label "gemini-3.8-flash."
256k output tokens rumored, up from 64k. 2M context window still unconfirmed.
The GPT-6 Astra comparison is coming next.
That's the one everyone's actually waiting for.
🚨 GEMINI 4 PRO JUST TURNED THE VOXEL PAGODA BENCH INTO A PRODUCT DEMO.
Same prompt people have been using for months.
Pagoda. Cherry blossoms. Torii. Pond. Camera controls. Lighting modes.
Flash versions get you a cute diorama.
This one ships a full scene you can orbit, swap Day / Sunset / Night / Sakura Dusk, ring the bell, and export.
Twitter is calling the Arena alias “Gemini 3.8 Flash.”
The actual rumor is Gemini 4 Pro / internal checkpoint “argon.”
One take: ~5–10 minutes. Interactive UI. Particles. Preset cameras. The usual “Google still can’t design a bottom bar” complaint… and then everyone keeps watching the clip.
Google already said Gemini 4 is their most ambitious pre-training run. No public drop yet. No official scores. Just leaks, Arena tests, and people arguing whether the first vibe-check is mid or insane.
The honest take:
This is not “it can draw a pagoda.”
This is “it one-shots a Three.js world with state, lighting, and controls.”
That’s why the thread is eating itself today.
GPT-6 Astra comparison is the only one that matters next.
Until then, Google just made the old Flash demos look like drafts.
🚨 GEMINI 4 PRO JUST MADE GEMINI 3.8 FLASH LOOK OLD.
The difference on the same SVG task is wild.
Both models were asked to generate a “pelican riding a bicycle.”
Flash gets the idea.
Gemini 4 Pro actually nails the details, structure and overall result.
And this is supposedly Google's next frontier model.
The GPT-6 Astra comparison is coming next.
That’s the one I’m waiting for.
We used to ask if a robot could walk.
Then if it could stand up after falling.
Then if it could open a door without tearing it off.
Now it’s on a range in a shooting stance like it already burned through a thousand magazines.
No shake. No flinch. No blink after the shot — because there’s nothing there that blinks.
A human after three rounds is thinking about coffee.
This thing is only thinking about the sight picture.
Argue all you want whether the clip is real steel or a generator with good taste in dust. Doesn’t matter. What matters is your brain no longer slaps “fake” on it in the first second. We’re already willing to believe a white humanoid can hold a pistol calmer than you.
The future doesn’t arrive with red eyes and a one-liner.
It arrives in a white shell, on a dirty range, on a Tuesday.
And it groups tighter than your cousin who “used to shoot a lot.”
Stop asking if it can run.
Ask who it hands the next mag to when the first one goes dry.
99% OF GYMGOERS SPEND YEARS SHRUGGING STRAIGHT UP AND WONDER WHY THEIR TRAPS NEVER GROW.
Vertical shrugs are a biomechanical failure. Pulling directly to your ears isolates the levator scapulae and inflames the cervical spine. Trapezius fibers run diagonally and horizontally across the upper back. To actually stimulate the tissue, hinge forward 15 degrees and pull the shoulder blades back. Align the load with the anatomy.
How may years did you waste on vertical shrugs before fixing your form?