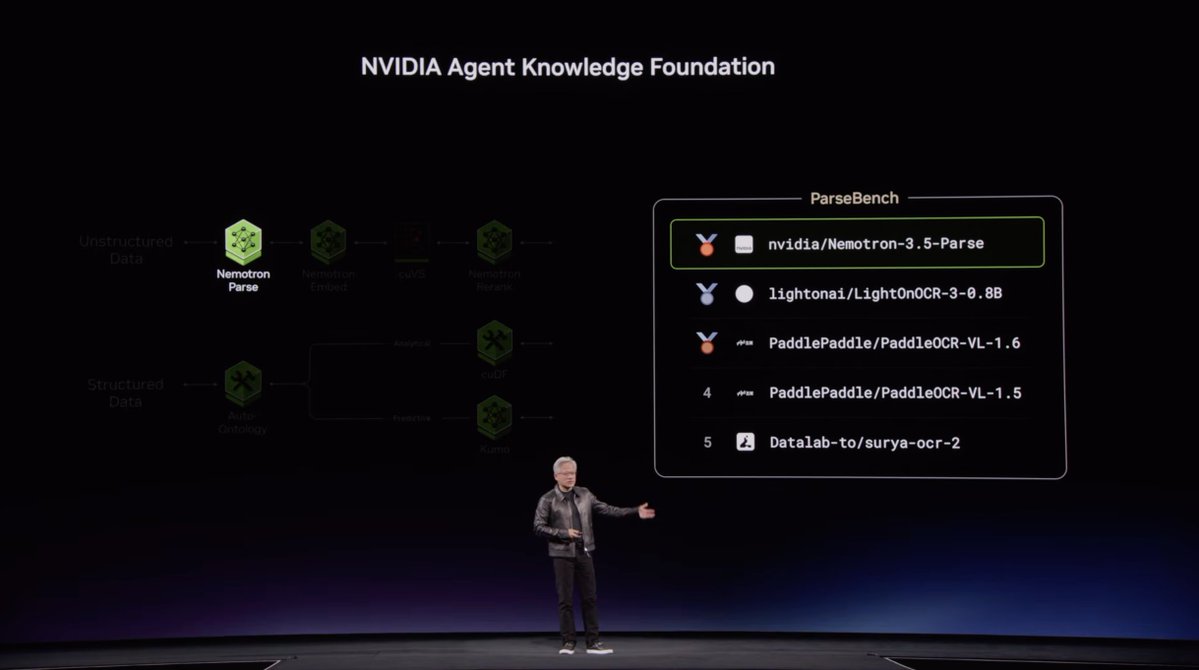
Congrats to @nvidia for creating the best open-weight model on document parsing so far.
Nemotron 3.5 Parse takes the #1 spot on ParseBench, our comprehensive real-world benchmark for document understanding. The full list consists of 150+ frontier models, open-weight models, and specialized solutions.
It does this while remaining sub-1B parameters so it's also blazing fast ⚡️
Big thanks to @JensenHuang for the shoutout at GTC Berlin!
Nemotron release: https://t.co/papiqxgGUb
ParseBench: https://t.co/PWczfhp0OX
I am open to leasing the front of my apartment for AI ad space given the price is right. Great location, 2 blocks from Balboa Cafe, a ton of foot traffic. LMK!
Introducing ExtractBenchPro: the most challenging benchmark for real-world document extraction.
We see a massive long tail of document complexity in terms of use cases brought on from our customers, that are completely unsolved from a price-performance standpoint. These include trial balances, well logs, canvass binders, site plan reviews, duty reconciliations, loss runs, and more.
Most existing extraction benchmarks are saturated by the frontier models (our cheapest modes now score 93%+ on ExtractBench). So there is enormous economic value in building a complex extraction benchmark that reflects this long-tail of knowledge work.
We spent a long time curating the most complex elements that we saw from real world extraction use cases:
✅ Document conventions: containing legends or rules where the rest of the document should be interpreted
✅ Density of internal jargon: specific definitions that must be cross-referenced within a doc
✅ Aggregation and reasoning: beyond returning exact values on a page, infer values derived from aggregating multiple sources of information
✅ Drawn relations: complex diagrams like procedures and circuits
✅ Charts inside documents: read precise points within a chart
✅ Long chart sheets: some data series like well logs cram all this data into an extremely long page
Within the industries where document extraction is relevant, even small mistakes can have enormous negative impacts. Therefore our headline evaluation metric is based on perfect documents: the proportion of docs with perfect (100%) value f1 score.
(Besides this we also measure value f1 and grounded f1)
It’s an extremely hard task for even the latest frontier models to solve, topping out at ~58% or so in Value F1 score for Codex with Astra - which is quite good but extremely expensive (almost $1 per page!) Our LlamaParse agentic/agentic plus modes are 20-40% and cover the left side of the Pareto frontier, at price ranges that are feasible for full production use.
ExtractBenchPro is available today as a website/technical blog, and also on Github and HuggingFace. Check it out!
Blog: https://t.co/bwxs86iS1d
Website: https://t.co/uRrFNU1Fqo
Hugging Face: https://t.co/1VImPRTorq
Github (is ExtractBench): https://t.co/auzmOGhsaB
It's SF tech week and here's how we celebrated at @llama_index 🦙:
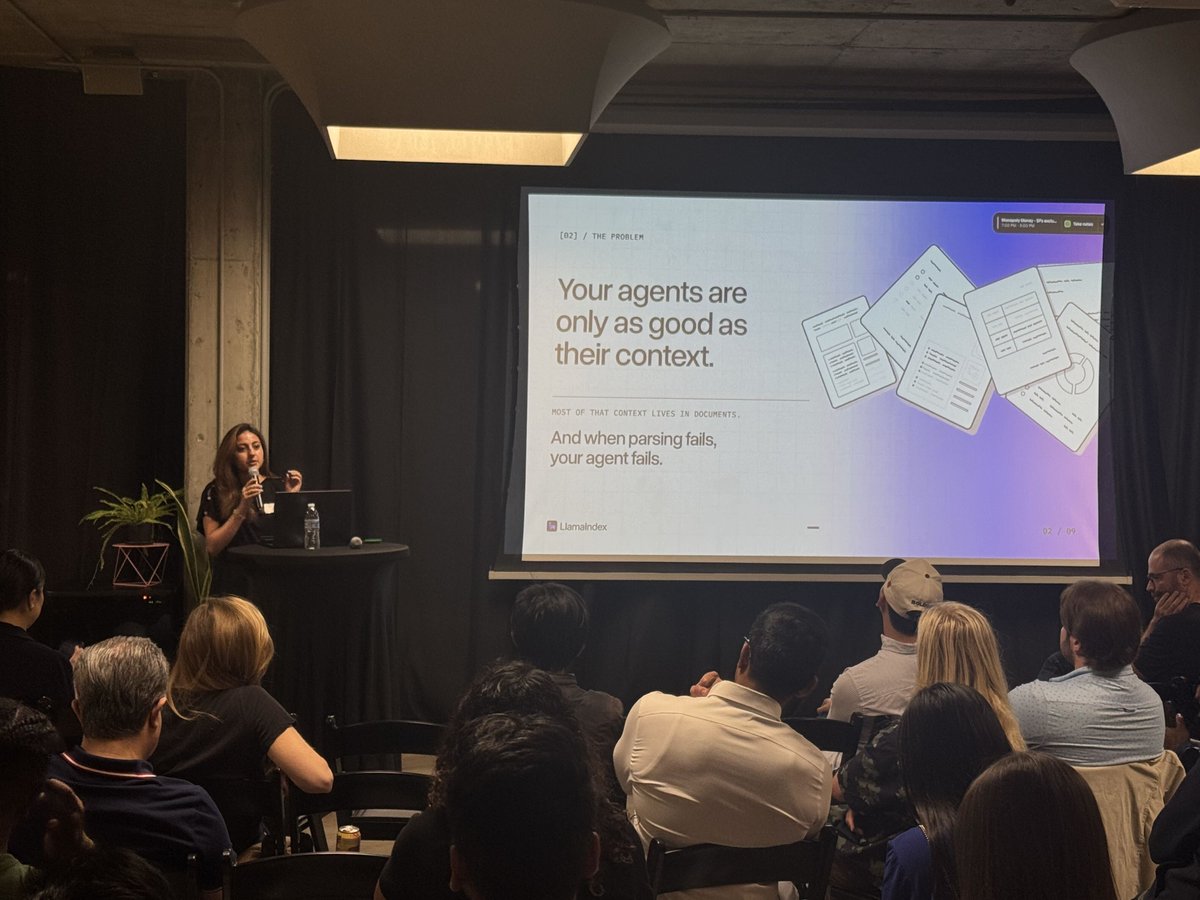
1. @imaanxsultan pitched our product in a room full of founders and won best pitch of the night
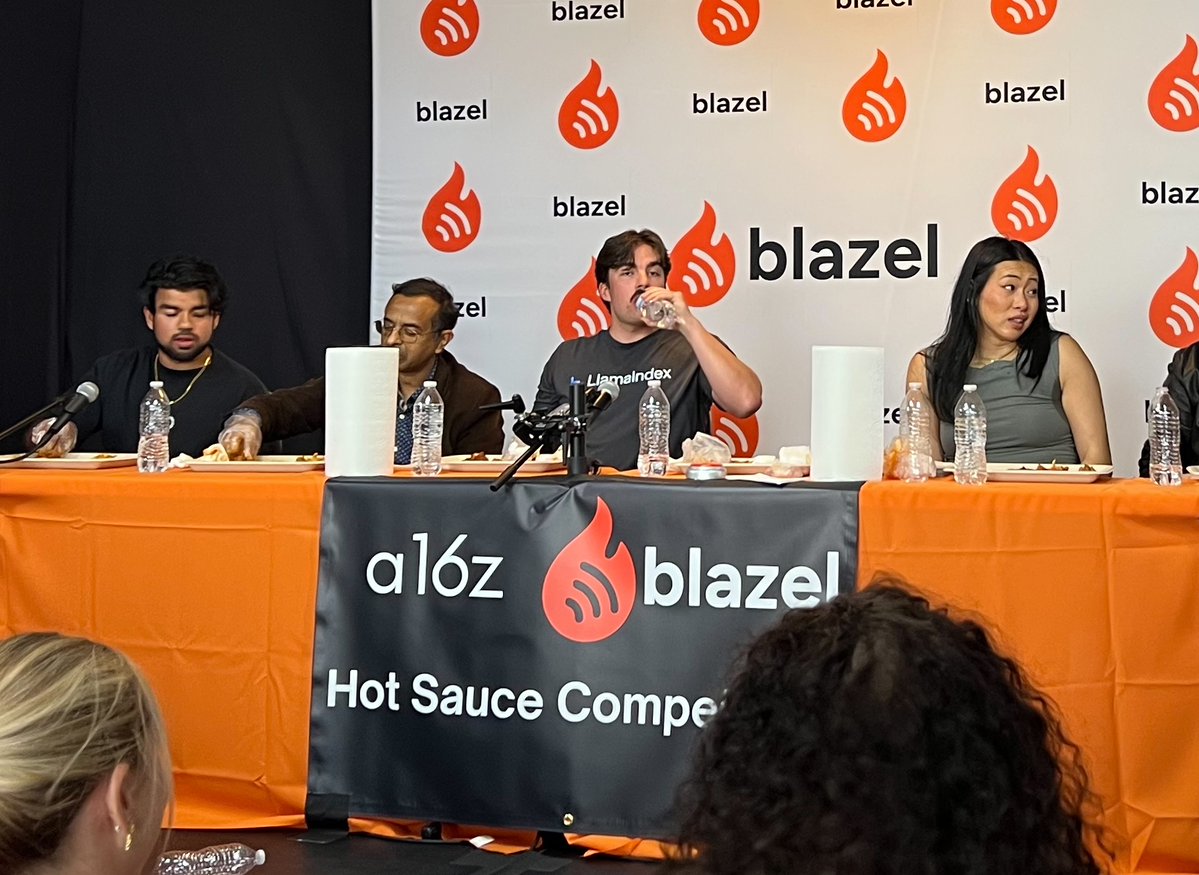
2. @matissemlk placed third in a hot wings eating contest until he was sick, also in a room of founders
Peak alpha energy.
Today we’re introducing Extract v2.5 - a series of frontier agents tuned for document extraction.
The agents (cost-effective, agentic, agentic plus) are tuned for value accuracy and grounding. Our extraction agents outperform Opus 5.5 and GPT-6 Sol while being 30%-4x cheaper.
We’ve made massive improvements on complex extraction over
* long lists (86.1% -> 95.5% on our agentic tier)
* records spanning pages (85.5% -> 96.5%)
* scanned forms (90.9% -> 95.7%)
We’ve also launched the following features:
✅ Advanced citations: we locate bounding boxes for all supporting values for an inferred field, even if there's not an exact match.
✅ Structural Reasoning: we tailor document extraction algorithms depending on the type, layout, and information
Our extraction agents are SOTA in price-performance on ExtractBench, across a wide range of cost points. We are the best tool for document extraction across documents of any complexity.
Blog: https://t.co/TTlTdECU03
All of these are available on LlamaParse: https://t.co/XYZmx5TFz8 . Come check it out!