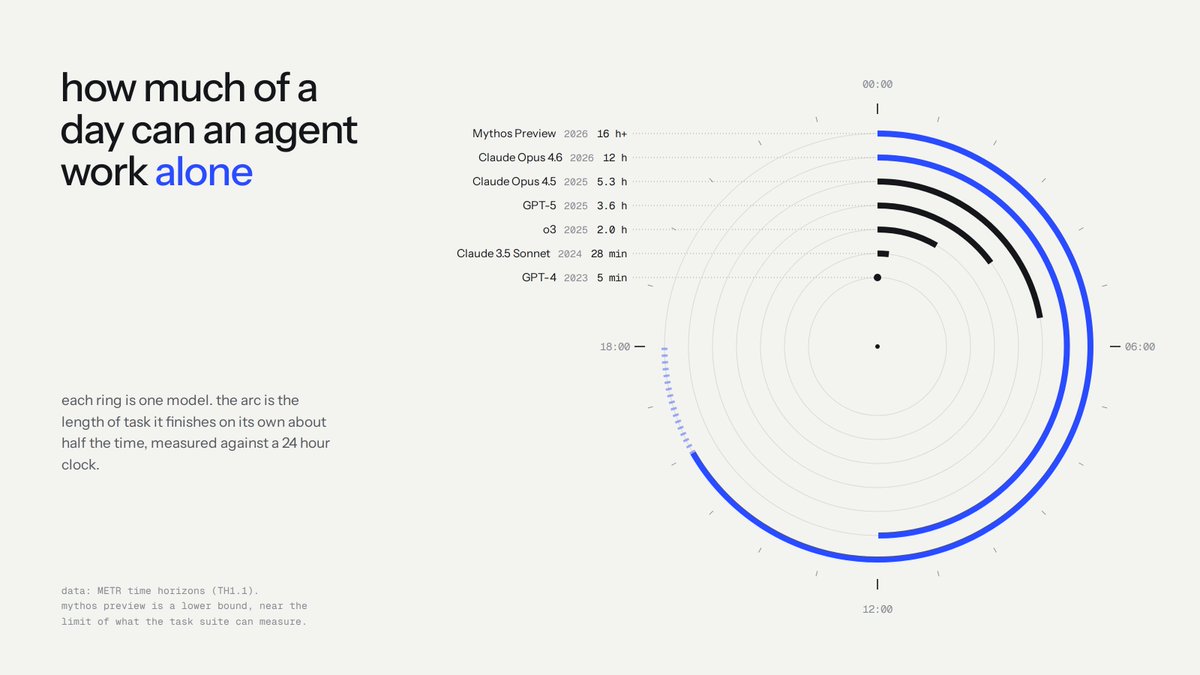
i was looking into how long agents can actually work on their own with no one checking in on them and ngl the numbers are kinda insane.
gpt 4 in 2023 could do like a 5 min coding task. opus 4.6 in feb was doing 12 hour ones. mythos did 16+ and metr basically said they ran out of long enough tasks to even measure it properly lol. the benchmark can't really keep up anymore.
it's been doubling every ~4 months. if that keeps going it's a full work week around now and a month of work by mid next year, and honestly i think it does keep going.
but i don't think "can do a 40 hour task" means what most people will think it means. the tasks in these tests are pretty tidy, they've got a clear goal and a clear finish line, and once the agent's done it doesn't carry anything over to the next one. it's also only succeeding about half the time, which you wouldn't really accept from anyone you worked with.
the problems that show up when agents run for days aren't really being tested. they lose track of why they made a decision, the plan drifts and they don't notice, and over time they kind of turn into a slightly different agent. and if you put a few together they mostly just end up agreeing with each other.
a harder test doesn't really fix that imo. you'd have to just let them exist somewhere for a while and see what's still there after.
their is no updated or relevant info to the most recent models released by @OpenAI, @AnthropicAI or alike, so couldn't really involve them.... aha
source: @METR_Evals
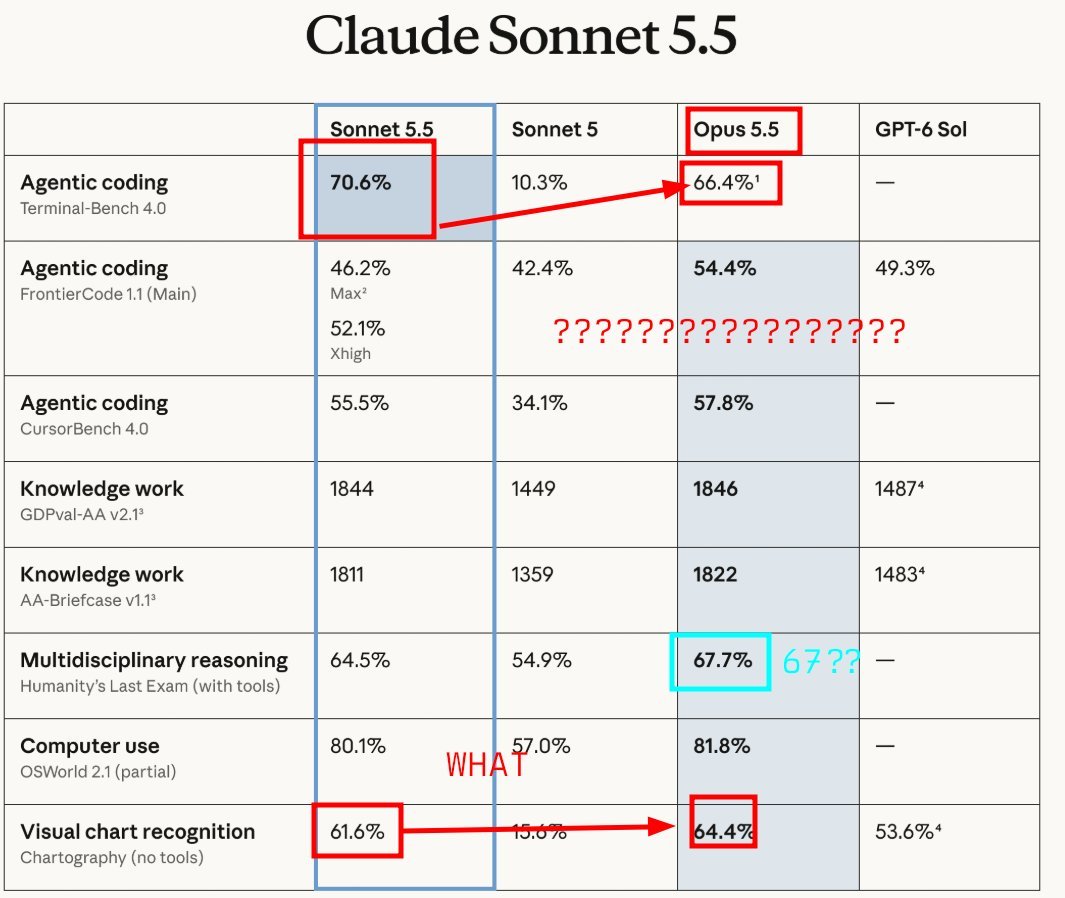
Introducing Claude Sonnet 5.5, the second model in the Claude 5.5 family.
It’s a clear upgrade over Sonnet 5, runs more than 30% faster, and costs up to 30% less for most work.