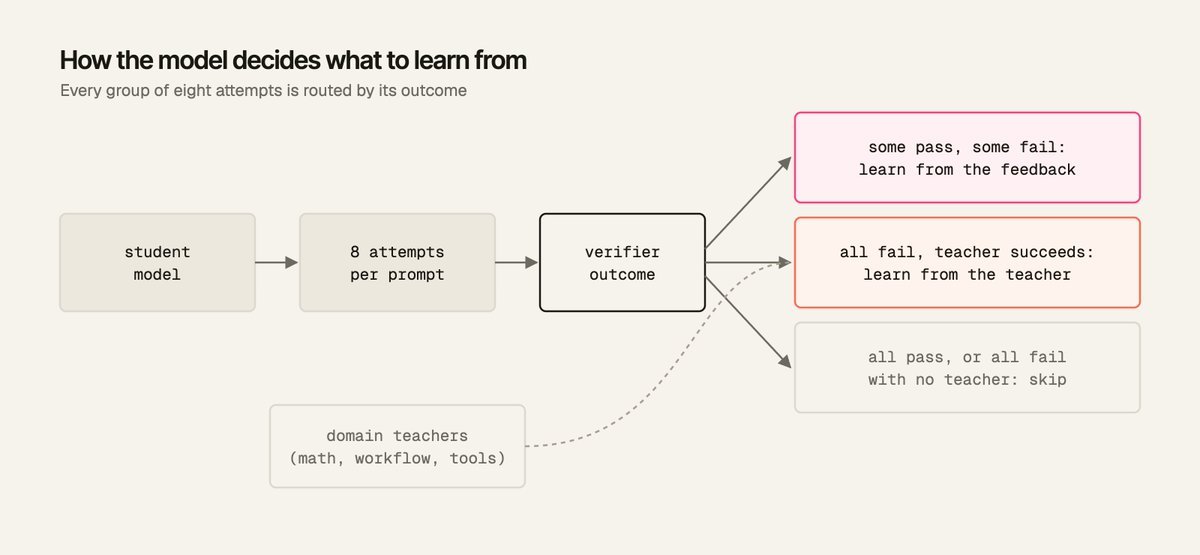
Diffusion models are complicated to RL because many training methods that work for AR don't work well for diffusion.
We present a methodology for post-training diffusion models that combines reward-based learning with teacher guidance.
The result is more effective way to post train diffusion language models for new capabilities.
The @Celeris_ai team will present the work at NeurIPS 2026 DiffuLM.
We’re sharing more of our research, starting with our paper on outcome-routed post-training for diffusion language models.
Many standard RL methods are difficult to apply reliably to diffusion language models. Our approach avoids policy likelihood ratios and combines reward-based learning with teacher guidance.
Tool-calling accuracy (BFCL) rose from 53.55% to 88.6%, without increasing the model’s size.
The result: a more effective way to post train diffusion language models for new capabilities.
Our team will present the work at the NeurIPS 2026 DiffuLM. https://t.co/zTjk2to0hm
Apparently AI has a 10% chance of wiping out humanity. But those enterprise SaaS targets aren't going to hit themselves.
Beyond the hype, the economics are changing rapidly. Open models are closing the gap, costs are falling, and intelligence is becoming increasingly commoditised.
The endgame for AI isn't just intelligence. It's the rate at which you can produce useful intelligence for a given amount of energy.
Had a great discussion with Pip Bingemann and @TomHums on the Wild Hearts podcast. We covered everything from AI doomerism and the concentration of intelligence, to why speed matters more than you think, how open source is changing the economics of AI, and why there's never been a better time to build!
Go listen (or watch)!
@ArtificialAnlys benchmarks Celeris-1 Decision as the fastest decision model at 62ms median response time, 2x faster than @typesafeai Jev.
According to the benchmark, Celeris-1 Decision scores 4 points higher than @OpenAI's GPT 6 Luna.
@tom_w_hamer Fun fact, for the price of a coffee you get 4,166,667 one sentence questions
And the decisions will actually be good unlike your overpriced sf coffee
Celeris-1 Decision is live today.
On jev-bench and typed decisions it beats Jev 1.13.0, OpenAI gpt-6-luna, Perplexity pplx-decider-v1.1-27b, and Inception Mercury Decide, on both accuracy and Brier score. Celeris-1-decision also led the benchmark in response time with a median of 67ms.
$0.04 per million input tokens, output free.
Full results and methodology: https://t.co/k6gH6SoMx9
Excited to launch Celeris-1-decision, a multimodal diffusion decision model, which scores accuracy of 80% on Jev-Bench, 7% higher than Jev 1.13.0. It has improved latency relative to Jev, with a median response time of 67ms.
We tested Celeris-1-decision against 4 models, including Jev, Luna, Perplexity and Mercury Decide, and Celeris-1-decision came out ahead of all of them on Jev Bench.
Finally - it supports explanations, which means you not only get a reason back but also an explanation of why it chose that option.
Available at https://t.co/WXZWiTHPcO, $0.04 per million input tokens, $0 for output tokens.
slack drafts are wildly non deterministic. they seem to not work sometimes and work some other times. i am concerned that marc bennioff is trying to keep me in a constant state of confusion
@SlackHQ pls help
Pitch me your startup in five words or less.
Actually, in less than 3 words. Or actually wait pitch it in one emoji and fourteen words. No wait one gif and a letter sent by carrier pigeon. Or a small watercolor painting or some shit
What if **not** raising your kid as an iPad kid puts them at a disadvantage because everyone else will be iPad kids and they would have an easier time conforming
Thought of the day
It’s been an incredible week for my follower count
It has increased from 6 to 8 (this is 33% WoW growth)
My team tells me I’ll reach 18.8m followers in one year
SF is the only city in the world where something like this is even possible
Introducing Celeris-1 Magnus. A model built for agentic work.
On τ³-bench banking, Magnus delivers 41.2% at a 55-second median, against GPT-5.6-sol's 38.1% at 79 seconds.
It’s a hybrid diffusion model derived from qwen3.8-27b, optimized for agentic workloads.
For more info, check out: https://t.co/XWmamkxrGq