Introducing DeepSeek V4.1 Flash 1017 Abliterated, live now on Morph, available through our Model APIs.
It feels more important to release this than ever before, with hacks in the past week affecting everything from PHP to recognizable brands like Railway and OpenCode.
Attackers now run abliterated models against your infrastructure 24/7. You need to do the same in defense.
That said, we're not allowing just anyone to sign up and use this. You'll have to go through KYC and explain your intentions first.
Fill out the form here to request access:
https://t.co/RFqgaSEdz4
DeepSeek V4.1 Flash 1017 is live on OpenRouter with DeepSeek as the first provider and many more providers on the way.
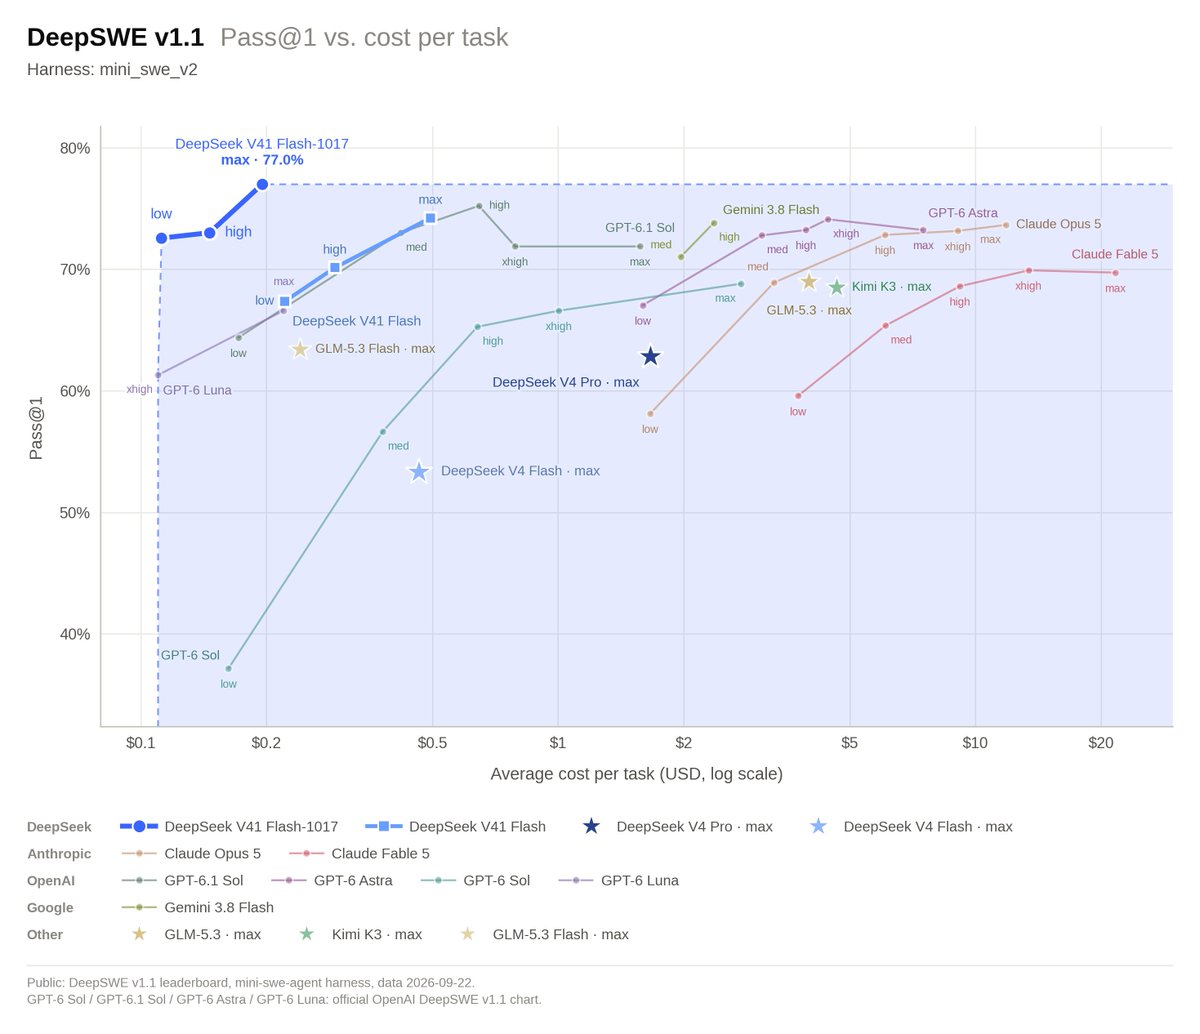
@deepseek_ai's update to V4.1 Flash is more token efficient and shows major gains in agentic benchmarks.
Use it now: https://t.co/YQrYeyU3ww
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
DeepSeek Flash V4.1 is now live on morph.
Completely new architecture optimized for price to performance. GPT-5 level intelligence at just 5% of the cost.
Expect an insanely high cache hit rate. This model fits 4x the amount of cache per unit of storage.
Morph now has the highest cache hit rate out of any provider serving Kimi K3
$200 spent on morph gets you 15% more Kimi tokens than that same $200 would on Modal and 64% more than it would on baseten
will be doing the same for GLM-5.3 next
the one-man inference provider
i hit a $6m run rate as a solo dev
morph was 1 person until last week
the first inference provider to be live with kimi k3 without early weights access
250 customer slack connect channels
i could've made morph a 1-person $1b company, but it would've been for the Ego instead of whats optimal
we are no longer a 1-person company.
but we will be the first 10-person $10b company.
everyone joining has had multiple offers from frontier labs
if you’re top 0.0001% at having adhd, dm me
Morph 🤝 SGLang
We're working with the @sgl_project and @lmsysorg team to push open-model disaggregated inference faster together.
First up is Kimi K3 Fast, served at up to 100 tokens per second through Morph's OpenAI and Anthropic-compatible APIs.
This is the beginning of a deeper collaboration around low-level optimization and high-performance open-model serving. More soon.