is the Anthropic IPO chart a better LR schedule than warmup cosine decay?
let's find out! @mridul__agarwal@ananthsiyer and i are running 4 identical pretraining runs, with the LR driven live by ANT, SPCX, SPY, and NVDA.
watch the models train at https://t.co/z9JTXXLpkg
Had a fun evening with @msarthak29@Vedang_A, getting Ripple to generate an image classifier without backprop, and edit its own weights.
Thank you @RicursiveAI@Azaliamirh@annadgoldie for hosting us, excited to see what comes next!
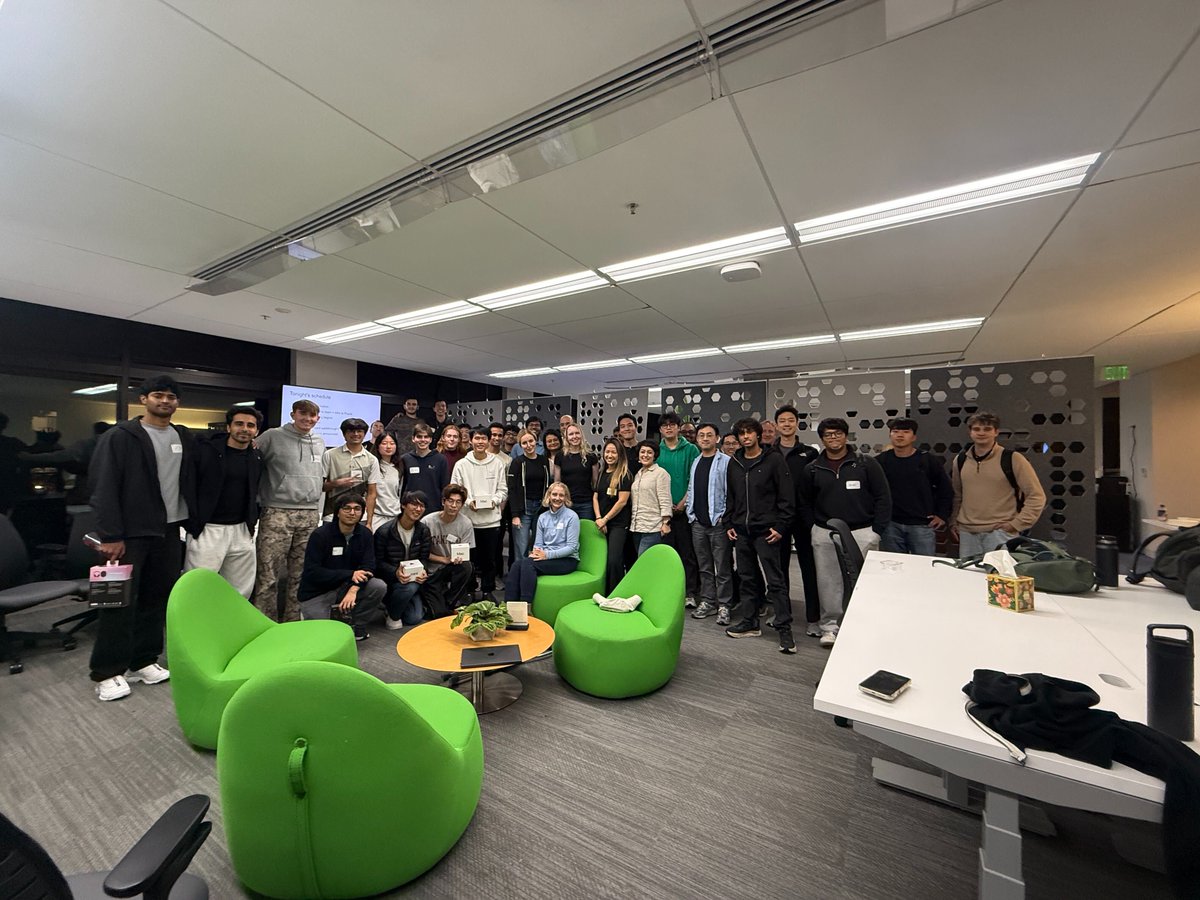
Last Friday we hosted the Ricursive Intelligence After Dark Hackathon, our first hackathon centered on our open-weight model release, Ripple-65B Preview. We brought together an incredible group of researchers, engineers, and builders to push the model in new directions. We saw some amazing projects spanning everything from CUA and Weight-Space Programming to model watermarking.
Huge thanks to everyone who came out, built something, and made the night memorable! This is just the beginning!
Introducing Speculative Self-Distillation (SSD, NeurIPS 2026), which pushes the accuracy–efficiency–forgetting frontier of self-distillation.
In SSD, student and teacher (the same model with additional information) write the rollouts together. Like a private tutor, the teacher lets the student write and takes over only when the student drifts too far. As a result, SSD trains on rollouts that stay as close to the student's own writing (on-policy) as possible while the teacher keeps them on track.
📉 38–69% fewer training tokens than on-policy, matching its accuracy
��️ Reaches on-policy accuracy in ~130 vs ~414 min (Science Q&A)
🧠 Forgets less in a stress test: −1.4 vs −4.5 points for on-policy
Really happy to finally share Ripple-65B Preview! We trained it from scratch with a core team of five researchers, and it sets a new U.S. open-weight SOTA on Terminal-Bench 2.1 for agentic coding.
Three choices that shaped how we built it, and a few things I learned along the way.
1. We deliberately chose a dense model.
Many leading open-weight models are MoEs. For our use case, we wanted strong reasoning and low latency for agents going through long sequences of model and tool calls. Going dense also gave us a simpler training and serving stack and avoided expert-routing communication. That combination mattered a lot to us.
2. We bought no posttraining data.
A lot of the work went into building our own data generation and filtering pipelines, and making sure we covered the tasks we cared about. We built on open-source training and inference stacks throughout. I’m particularly happy about how much we were able to do as a small team by building on the community’s work.
3. We worked on the RL system and curriculum together.
Mixed RL meant dealing with very different rollout lengths, tool-call patterns and shares of the batch across domains. We tuned oversampling per domain and per problem to keep batch latency down, while managing policy staleness and trainer-inference mismatch. Score centering worked best among the corrections we tried; we used it alongside truncated importance sampling.
We also kept adjusting task selection and introducing harder problems as the model improved. Getting batches ready faster and keeping updates stable had to go hand in hand with giving the model useful problems to learn from.
Loved building this with @DZhang50, @esonghori2, @ethanboneh and @amiwilliamhuang. Huge thanks to our cofounders @annadgoldie and @Azaliamirh, and the whole @RicursiveAI family for making it possible. Really proud of what we built together.
Today we release Ripple-65B Preview, our 65B dense LLM we pretrained from scratch.
Ripple sets a new state-of-the-art for U.S. open-weight models in agentic coding tasks, surpassing significantly larger models including Muse Spark Open-816B, Beam-501B, Inkling-975B, and Nemotron 3 Ultra-550B.
Learn more: https://t.co/Pe04ZKhkE9
जेईई एडवांस–2021 परीक्षा मे देशभर मे प्रथम स्थान हासिल करने पर जयपुर के मृदुल अग्रवाल जी को हार्दिक बधाई।
मृदुल ने कड़ी ��ेहनत से जेईई एडवांस के इतिहास मे अब तक के सर्वाधिक अंक प्राप्त कर एक मिशाल कायम की है।
साथ ही मैं इस परीक्षा मे सफल रहे सभी विद्यार्थियों को भी बधाई देता हूं।
IIT-JEE (Adv) परीक्षा में प्रथम रैंक प्राप्त करने पर राजस्थान के बेटे #मृदुल अग्रवाल को बधाई। यह सफलता उनके अथक परिश्रम,माता-पिता की प्रार्थनाओं और शिक्षकों के समर्पण का प्रतिफल है। इस परिणाम के साथ संसदीय क्षेत्र कोटा की कोचिंग संस्थाओं ने एक बार पुनः श्रेष्ठता सिद्ध की, बधाई।
Heartiest Congratulations to #Jaipur’s Mridul Agarwal, the topper of #JEEAdvanced2021! It’s a great achievement & a result of his hard work & determination.I congratulate Kavya Chopra,the topper among female candidates & all those who have attained success. My best wishes to all.