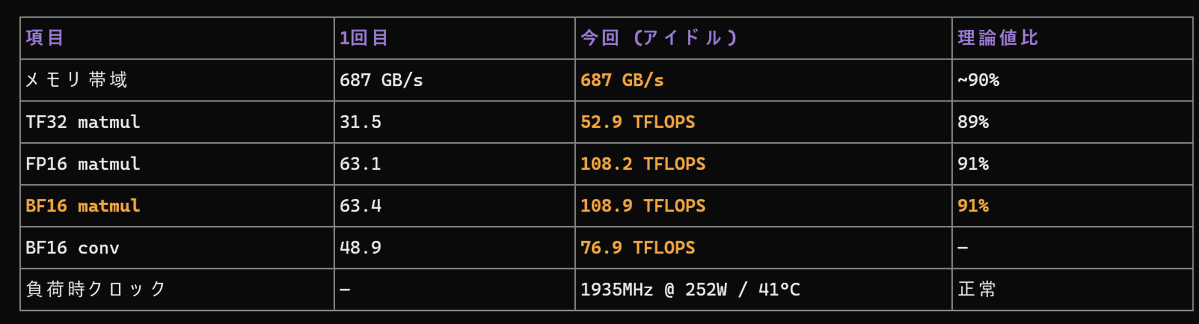
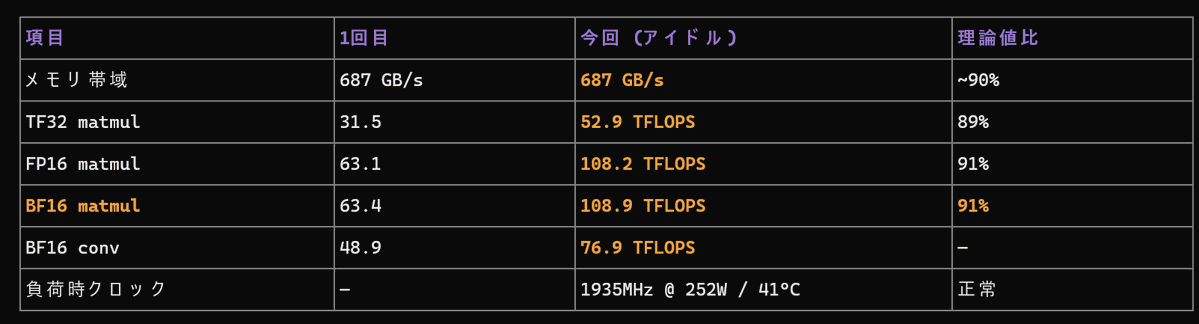
My 3090s just got 1.9x FASTER at BF16 tensor math!!! Same cards, same driver, same 300W, one Linux kernel module.
bf16 tensor pipe: 82 -> 155 TFLOPS
cuBLAS BF16 GEMM 8192: 64 -> 99 TFLOPS
TF32: 41 -> 79 TFLOPS
NVIDIA ships every 3090 with fp32-accumulate tensor math at half speed. The driver even reports it: FMLA32 = 1/2. gpu-unlock by Zagitta sets it to full before the NVIDIA driver loads. After a cold boot all 4 of my cards say FMLA32 = full.
Real inference got less than I predicted. Strata, Qwen3.8 Flash-Next on 2 cards, prefill:
4K: +12%
10K: +12%
90K: 3205 -> 3536 tok/s, +10%
Before installing I said +14 to 19% at 90K, so I was wrong. The GEMM phases got 23% shorter, but they are only about 40% of Strata prefill, and the int8 experts, copies and CUDA core kernels didnt get any faster.
Outputs did not change. With the same expert cache size, my log-prob dump over 1996 teacher-forced positions is the same file byte for byte as the stock run before the module.
Next is Strata itself, now its everything around the GEMMs that makes prefill slow. How I set it up is in the replies.