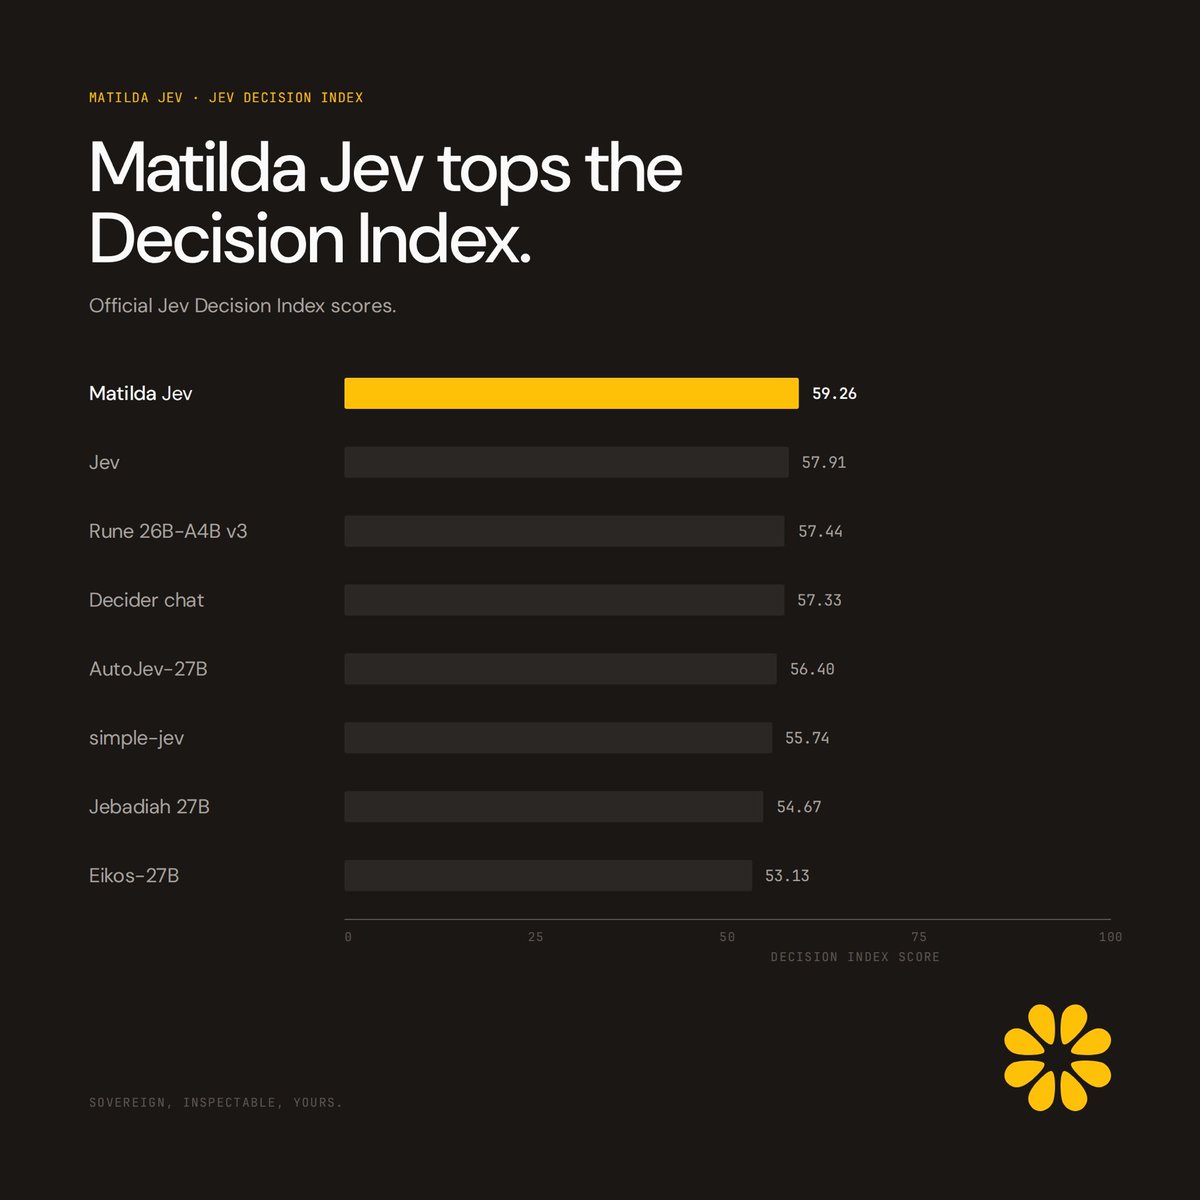
Today we are open-sourcing Matilda Jev, Australia's first decision model, conditioned for Australian deployment and post-trained with our own specialised recipe. Decision models do not generate text. They answer a typed question and respond with a calibrated probability for each option in a single forward pass, reducing hallucination and making intelligent decisions faster and more efficient.
This release proves that highly capable AI models can be built, post-trained, evaluated, and served entirely within Australia. Post-trained end-to-end on our local infrastructure, the model achieved a median decision latency of 56.8ms on a single @AMD MI355X across 150,317 evaluation requests.
Today we’re opening Matilda’s beta to a broader group of users.
Matilda is Maincode’s Australian AI system: built from metal to model, designed for thoughtful use, and held to a higher standard for how AI should behave. We’re building Matilda because Australia should have more than access to powerful AI.
We should have AI systems that understand our context, reflect our standards, run on infrastructure we can trust, and give people and organisations more control over how they use this technology. That means Australian infrastructure, inference on Australian shores, local adaptation, clear safety expectations, and a product experience designed around how people here actually work and communicate.
The beta is still early, and that is the point. We want to learn where Matilda is useful, where it needs to improve, and what reliability looks like in practice across real users, real tasks, and real expectations.
Welcome to Matilda’s open beta, available at https://t.co/PnwVB67hTE and on the Apple App Store at https://t.co/D6ZUiuPtX6
I’ll be at ICML 🇰🇷 presenting this work with an Oral presentation and poster alongside @LiangzeJ on Thursday, 9 July!
🎤 Oral: 4:45 p.m. Oral 6A - LLMs
📌 Poster: 5:00–6:45 p.m. Poster Session 8, Hall A
Come say hello!
We wrote our own inference engine in Rust 🦀 for our AMD MI355Xs, with no ROCm anywhere underneath it.
On the small all-reduce that tensor-parallel inference runs for every single token, it comes out about 1.3x faster than AMD's own RCCL at its best, sitting on what looks like the physical latency floor of the chip at around twenty microseconds.
As the first anywhere to have the MI355X fully deployed in production, running Matilda, inference is a huge focus for @MaincodeAU. In fact inference is the part of an AI business that actually meets customers, so we wanted to understand this hardware as deeply as we could. We took the runtime out and drove the GPU through the Linux kernel driver directly, the same interface ROCm itself is built on, to see how close to the silicon we could get.
RCCL is genuinely great and has years of careful work behind it, and it also has to be good at everything a runtime is ever asked to do. A layer that only has to do one thing really well can set all of that aside and cut its overhead to almost nothing. The win isn't a clever trick, just the absence of overhead.
And you don't have to take our word for it. The whole thing ships as a single container image with the kernels compiled in, and three commands reproduce the numbers on any MI355X box.
More in the blog post...
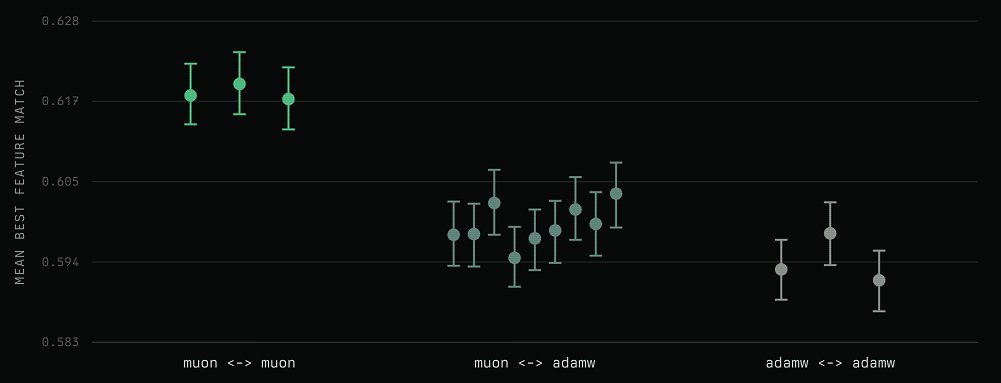
Muon has been a recent obsession of ours, so we dug deeper. It changes the loss curve, but does it change what a model learns?
We trained matched AdamW and Muon GPT-2-class models, held validation loss fixed, and compared their SAE features by firing patterns over the same 1M tokens.
The result: Muon model’s features match an AdamW model’s features about as well as two AdamW seeds match each other. So changing the optimizer perturbs SAE feature identity about as much as changing the random seed. Muon’s advantage is not “different features.” It is “same features, different geometry.”
Australia shouldn't have to rent its AI future.
So we built Matilda.
An Australian-built AI assistant, running on our own fully sovereign cluster in Melbourne.
Public access is rolling out now.
curious why no rust but this is spot on for max perf at this scale. even rust’s zero-cost abstractions add just enough indirection (borrow checker decisions, safety checks at compile time) that they matter when you’re mapping pipeline parallelism across 220k GB300s + 800G NICs with zero waste.