Two months since Myrikko launched. We’ve been focused on making it easier to discover, compare, and start testing models with Myrikko.
Recent updates include:
🔹More ways to sign up and get started
🔹$10 welcome API credits for new users, no credits card required
🔹More flexible model filtering to help you find the right model faster
🔹Clearer pricing for easier model comparison
One API. Multiple models in one place.
Different workflows may benefit from different models, especially when balancing performance, latency, and cost.
Use the Myrikko API to match each task with a suitable model.
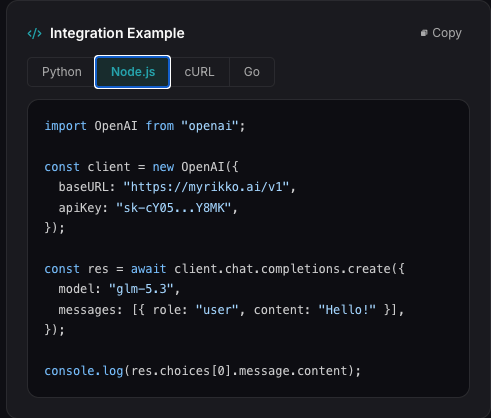
Rather than setting up separate integrations, just update the base URL, use your Myrikko API key, and switch the model based on the task.
Python and Node.js examples below.
12 days in, GLM-5.3-Flash is already our most-used open-weight model by user count.
Frontier intelligence, competitive pricing.
If you’ve been meaning to try it, now’s a good time to put it to work on your own workloads.
#GLM#openmodel
12 days in, GLM-5.3-Flash is already our most-used open-weight model by user count.
Frontier intelligence, competitive pricing.
If you’ve been meaning to try it, now’s a good time to put it to work on your own workloads.
#GLM#openmodel
GLM-5.3, Kimi K3, and GLM-5.3-Flash are available on Myrikko.
Test them on your own workloads through one API without rebuilding your integration.
GLM-5.3 — 30% off
GLM-5.3-Flash — 70% off
New users can start with free API credits.https://t.co/1e3xSWbFGO
GLM-5.3 and Kimi K3 continue to lead open-weight models, with GLM-5.3-Flash close behind.
Interesting to see how they perform on broader agentic and real-world tasks.
Announcing Artificial Analysis Intelligence Index v4.3, upgrading Terminal-Bench to 4.0 and adding AutomationBench-AA, an agentic workflow automation benchmark with a private test set. This is a continuation of our rollout of Intelligence Index v5
Changelog (Index v4.2 → Index v4.3):
➤ Terminal-Bench: 2.1 → 4.0, completing our upgrade to the latest version of Terminal-Bench
➤ Replacing 𝜏³-Banking with AutomationBench-AA, our implementation of Zapier's business workflow automation benchmark
We are continuing to prioritize keeping Intelligence Index as useful as possible by bringing forward a subset of the changes we had planned for Index v5. Each change in v4.2 and v4.3 stands on its own merits and brings the Index closer to real-world problem solving, adds more private test sets to prevent gaming, and reduces saturation
Intelligence Index v4.3 raises the difficulty of agentic coding tasks and broadens the types of agentic workflows tested. Because we use a held-out test set for AutomationBench-AA, in collaboration with @zapier, the weight assigned to evaluations with private tasks or answers increases from 40% to 45%. Category weights are unchanged from v4.2: Agents 30%, Coding 20%, General 30%, Scientific Reasoning 20%
Detailed changes:
➤ Upgraded Terminal-Bench 2.1 to 4.0: 66 multi-step tasks testing agents on tasks run in agent sandboxes driven via the terminal, including tasks involving software engineering, machine learning, science, and operations. The 4.0 update recalibrates compute and time allowances, and improves task instructions and verification. We have changed from the Terminus 2 harness to mini-SWE-agent, a minimal, model-agnostic harness. We will also be updating our Coding Agent Index, where we test model and harness pairs, to include Terminal-Bench 4.0 soon
➤ Replaced 𝜏³-Banking with AutomationBench-AA: Our implementation of Zapier’s AutomationBench tests agents on 657 business workflows across simulated applications such as Gmail, Slack, Salesforce, and Jira. Agents must complete task objectives while following business rules. AutomationBench-AA uses Zapier’s private set of 657 tasks, and is built on v1.0.6
Key results:
➤ Claude Fable 5.1 and GPT-6 Astra lead the Intelligence Index: Both Claude Fable 5.1 (max with fallback) and GPT-6 Astra (max) score 53 on Intelligence Index v4.3, followed by Claude Opus 5 (max, 51), Claude Fable 5 (with fallback, 50), Muse Spark 1.3 (max, 48) and GPT-5.6 Sol (max, 47)
➤ GLM-5.3 and Kimi K3 continue to lead open weights models (both at 44): GLM-5.3-Flash (42) is the third strongest open weights model, followed by Qwen3.8 2.4T A95B (40) and DeepSeek V4 Pro 0813 (max, 36)
➤ 4 labs occupy the Intelligence vs. Cost per Task Pareto frontier: OpenAI occupies the majority of the cost-efficiency frontier, with all five reasoning efforts of the recently released GPT-6 Astra offering the lowest Cost per Task at their respective levels of intelligence. Claude Fable 5.1 (xhigh, max, 53), GLM-5.3-Flash (42) and MiMo-V2.5-Pro (26) round out the rest of the frontier
✨A great weekend to build with GLM-5.3-Flash.
If you haven’t tried it yet, this is a good time to put it through a real coding or agent workflow.
Looking forward to seeing what you build with it.
GLM-5.3-Flash is now live on Myrikko.
Previously previewed as Ox Alpha, GLM-5.3-Flash brings native multimodal capabilities, stronger coding and agentic performance, and efficient long-context workflows.
Now available on Myrikko at 70% off list price through September 9, 2026.
Try it now: https://t.co/TKG5Q1L37H
Interesting test. Looking forward to seeing more of what you build with the Myrikko API.
These two models are currently discounted on Myrikko for a limited time:
GLM-5.3 — 30% off
GLM-5.3-Flash — 70% off
Testing GLM-5.3-Flash and GLM-5.3 on the same task.
Same prompt. Same setup.
Cost via the Myrikko API:
GLM-5.3 — $0.0085
GLM-5.3-Flash — $0.0032
Both did a solid job. GLM-5.3-Flash stood out for its cost efficiency.
Here’s how they performed. Which one do you like?
✨A great weekend to build with GLM-5.3-Flash.
If you haven’t tried it yet, this is a good time to put it through a real coding or agent workflow.
Looking forward to seeing what you build with it.
GLM-5.3-Flash is now live on Myrikko.
Previously previewed as Ox Alpha, GLM-5.3-Flash brings native multimodal capabilities, stronger coding and agentic performance, and efficient long-context workflows.
Now available on Myrikko at 70% off list price through September 9, 2026.
Try it now: https://t.co/TKG5Q1L37H
GLM-5.3 is now open-weight.
Our most capable model for agentic coding and cyber defense is now available to download, run, and customize.
Weights: https://t.co/v1IbWMXxg4
Tech blog: https://t.co/ekQkO83jCv
Big news: GLM-5.3-Flash by @Zai_org has landed around #5 in the Code Arena: WebDev (#2 among open models) scoring 1634 (AutoEval).
Priced at $0.15/$0.5 Mtoken, it reshapes the Pareto Frontier!
For comparison, GLM-5.3-Max currently ranks #8. GLM-5.3-Flash has 320B parameters with 18B active vs. Max variant’s 753B with 40B active.
Note: this is an early AutoEval score, in which a Reward Model trained on Arena's human preference data casts automatic votes in place of live votes. We’ll continue to see how scores converge as more live human votes come in. See thread for more info on the methodology behind AutoEval.
Congrats to the @Zai_org team on the strong launch!