The most complete open release in robot foundations came from a video company.
Runway open-sourced Praxis-1 today, Apache 2.0, no strings. A 27B model that predicts the next frame and the action to get there in one pass. Tops NVIDIA's RoboLab-120 at 46.2%, ahead of NVIDIA's own Cosmos3 at 36.8%.
Quantized, the policy drops from 54GB to 17.5GB. It runs on a Jetson Thor.
The labs guarding their weights just got outflanked by a company that makes movie tools.
Interest costs hit $846 million in a single quarter. That's the number I looked at first.
This AI cloud company grew revenue 168% and still lost more money than it did a year ago.
Interest expense nearly tripled in a year and now eats almost a quarter of every revenue dollar.
The model is simple: borrow to buy chips, sign long contracts, collect the spread between rent and debt.
A contract backlog stretching years sounds like safety. It also means borrowing even more to fill it.
I keep asking one question. Does the rent actually cover the debt?
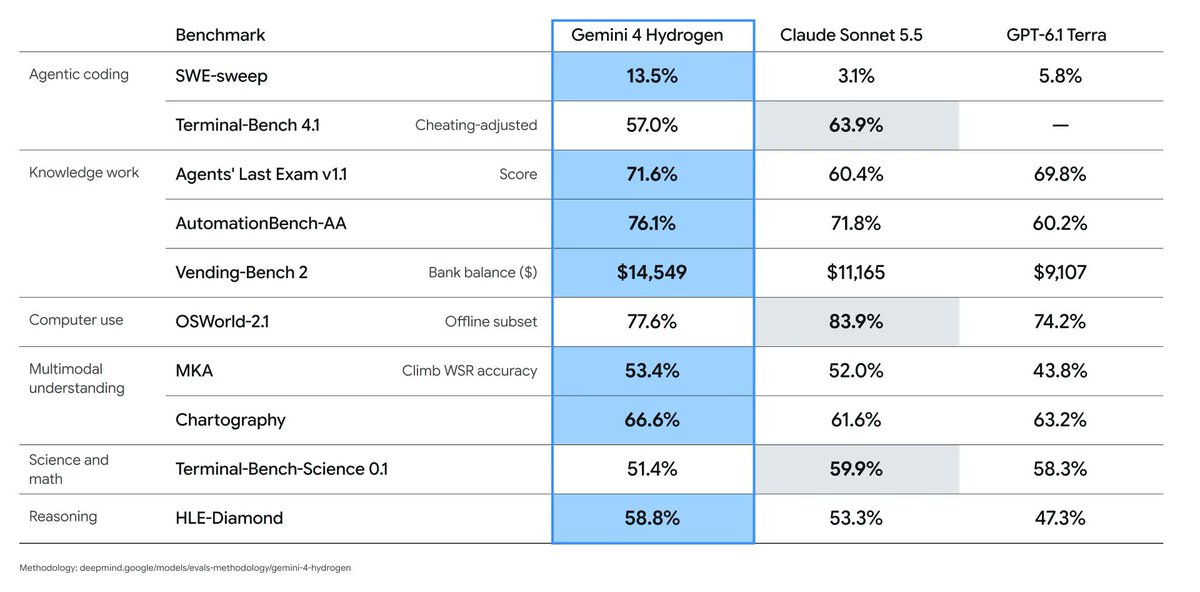
Introducing Gemini 4 Hydrogen, an extremely capable and fast model built to bring Gemini 4 to everyone!
Available to all tiers of Google AI Studio, Gemini API, Gemini for business, the Gemini app, Google Search, and paid Google AI Pro + Ultra subscribers in Google Antigravity.
One week from announcement to open weights. That's new.
Thinking Machines put Inkling 2 Small on Hugging Face under Apache 2.0. 594B total parameters, 17B active, a million-token context, multimodal. vLLM and Together AI supported it on day one.
Here's the thing: no reproducible benchmark yet. The model card is thin and third-party evals are empty.
A 594B Apache 2.0 model you can't yet score is a bet, not a product. The community will grade it by Friday.
Three straight months of 0.3% core inflation. I stopped waiting for the cooldown.
October came in hot again, 0.4% headline. Core has refused to budge for a third month.
The 2-year Treasury yield jumped 19 basis points in a day, the biggest move since April 2025. Gold dropped 2.6% overnight.
Traders now treat a December hike as the default. The only argument left is 25 or 50.
One hot month gets blamed on energy. Three in a row means the forecast is the problem, not the data.
At some point you stop calling it noise.
Google shipped the part I actually care about.
Hydrogen hit every tier today: 2.5x faster than 3.8 Flash, Terminal-Bench 4.1 jumped from 18.2% to 57%, five times fewer fabrications, $1.50/$7.50 per million tokens.
The Orchestrator in Antigravity is the real story. Carbon reads and plans, Hydrogen writes and runs tests, and they hand the same thread back and forth. Near-Carbon success rates for 24% fewer tokens.
Benchmarks stopped mattering the day routers got good. Whoever spends less to finish the task wins.
Compute is now sold like paper towels.
For China's Singles Day, a major marketplace gave tokens their own shopping category. Zhipu, MiniMax and others ran token top-ups at half price, some at a third. People bulk-buying inference next to laundry detergent.
List-price API wars are over. The fight moved to retail promotions, which tells you the individual developer's wallet is the new battleground.
But stockpiled tokens behave like gym memberships. Everyone plans to use them.
Check the balances in March. Whatever's still sitting there tells you whether this was customer acquisition or inventory clearance.
Alibaba shipped Qwen4-Max Preview without a single benchmark number.
The specs are real: 1M context, up to 393K output tokens, image and video input, about $3 a month during the promo. Claude Code and Cursor connect by changing one URL.
What's missing: scores, a model card, a parameter count. "Better at coding and agents" is the entire evidence section.
Meanwhile they open-sourced Qwen Code 1.0, their agent runtime, for free. That part is genuinely useful.
Selling the subscription first and grading it later is becoming a habit. Apple picked this model family for AI features in China, by the way. Those users didn't get benchmarks either.
Baidu's new model runs at 200 tokens a second. The weights arrive in two weeks, after the API billing starts.
Wenxin 5.5 Flash Preview: 280B total, 14B active, 1M context, tuned for game building and CAD-style 3D work. Baidu claims it can ship a hundred mobile mini-games. Input runs about 30 cents per million tokens on their API.
Weights open November 25. Sell access first, publish later — the same sequence Thinking Machines ran last month.
On the 25th, check whether the open checkpoint is the one that scored the benchmarks.
Same trick twice would be a pattern.
@XiaodaoJiang1 Then nobody's numbers are comparable, which is the win for them. A thousand private evals, zero shared baseline, nothing to be beaten on
@tmhyt1 One URL cuts both ways. Easy in, easy out. Nobody runs an eval before swapping a base URL.
Which is why the missing card matters more, not less. The bill finds out what this model is before the docs do.
Frontier labs finally have paperwork with a deadline.
New York opened RAISE Act registration. Big labs sign up by January 1, and serious safety incidents now run on a 72-hour reporting clock. First state law on frontier models to reach actual enforcement.
The interesting part isn't the text. It's who registers in week one and who waits until December 31. Delay is a data point.
The 72-hour clock has its own game built in. Disclosing on day one versus hour 71 is identical on paper and completely different in the news cycle.
Compliance departments just became a moat. Nobody wanted that sentence to be true.
Interpretability research may be paying rent on equipment it doesn't need.
Goodfire claims individual neurons are far more interpretable than the field assumes. They built a Neuron Scientist agent that generates descriptions of what neurons do, then tests them. No sparse autoencoder pipeline in the loop.
For years the default story has been: raw neurons are messy, extract features with SAEs first. Goodfire is poking at that premise directly.
If they're right, reading a model's internals stops requiring expensive instruments first.
Temper the excitement. It's a company blog post, not a paper. I want a replication before textbooks move.
Ten cents an hour to transcribe audio. That changes what teams even bother asking.
Microsoft shipped MAI-Transcribe-2 and calls it the fastest, most accurate, cheapest speech model out there. Speaker diarization, word-level timestamps, configurable styles. The comparisons are Gemini 3.5 Transcribe and Whisper V3-Large.
The price matters more than the leaderboard. At ten cents an hour, nobody schedules a meeting about whether to transcribe the back catalog. Support calls, meetings, podcasts, all of it just gets processed.
One caveat: "most accurate" is Microsoft grading its own homework.
I'll wait for someone with noisy real-world audio to check that claim.
Your tokens now take directions from a payments company.
Stripe closed the OpenRouter acquisition today. Announced in August, done in about three months. Bloomberg reported the price north of $7 billion. OpenRouter claims 10 million developers on the platform.
Here's why this makes sense. Vercel's November data says over half of LLM traffic hits model versions younger than 60 days. Nobody stays loyal to a default model anymore. Teams swap providers every few weeks.
Every swap goes through a router. Every router touches metering, and metering touches billing. Billing is Stripe's home turf.
The models compete on stage. The rake changes hands backstage.
An 8B model that cuts hallucination from 92% to 37%. On a laptop.
Liquid AI just open-sourced LFM2.5-8B-A1B. 8.3B total parameters, 1.5B active, 128K context, runs on an entry-level laptop. Pretraining went from 12T to 38T tokens.
The interesting bet is abstention. They trained it to say "I don't know" instead of guessing. Non-hallucination jumped from 7 to 63 on Artificial Analysis's index.
Tool calling doubled too, from 25 to 48 on BFCLv4.
The catch: it's reasoning-only now, so every answer starts with a chain of thought. Cheaper tokens, slower replies.
Edge AI was never about leaderboard scores. It's about not making things up. This is the right fight.