1/ T2I diffusion models can memorize training data, reproducing near-identical copies of training images and raising privacy & copyright concerns. Our #ICML2026 paper asks: can we stop this at inference time? Joint work w/ @Eleni30fillou@PeterTRIANTAFI1
https://t.co/LN79MLYDmW
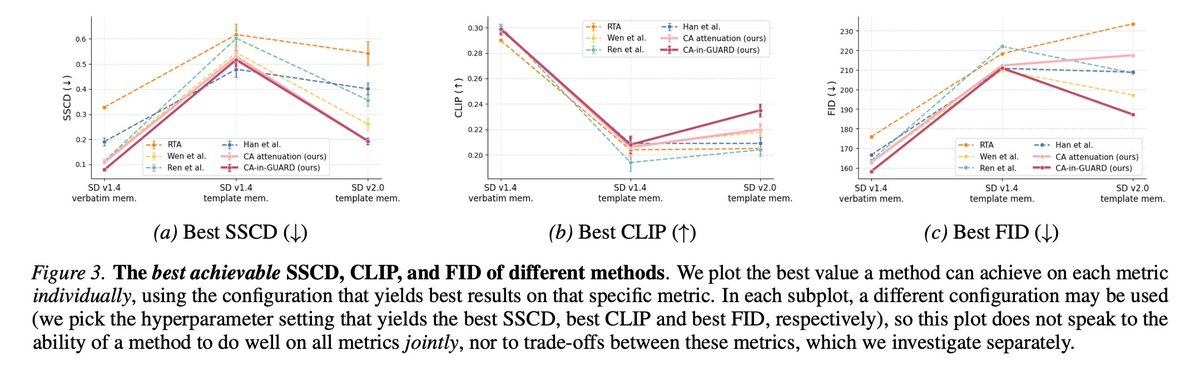
5/ Our comprehensive evaluation across architectures and memorization types shows that CA-in-GUARD is strong and robust, outperforming prior SOTAs on both memorization mitigation and generation quality.
1/ T2I diffusion models can memorize training data, reproducing near-identical copies of training images and raising privacy & copyright concerns. Our #ICML2026 paper asks: can we stop this at inference time? Joint work w/ @Eleni30fillou@PeterTRIANTAFI1
https://t.co/LN79MLYDmW
4/ So we built a detector that dynamically finds these attention "spikes" per-prompt, then attenuates them at those flagged positions — this positive target instantiates GUARD as CA-in-GUARD.
7/ For further insights into scaling RUM, check out our follow-up work, “Scalability of Memorization-Based Machine Unlearning”, where we explore various memorization proxies and their impact on unlearning performance [https://t.co/GSZ712t9xl]
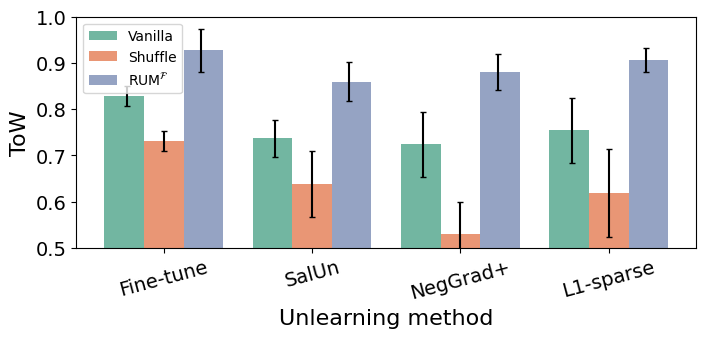
1/ What makes machine unlearning hard? And what can we do about it? Our #NeurIPS2024 paper explores key factors affecting unlearning difficulty & introduces RUM🍹, a new framework to improve unlearning pipelines - w/@meghdadkurmanji, George Barbulescu, @Eleni30fillou, @PeterTRIANTAFI1 [https://t.co/dcLkB1yiP4]
6/ Making RUM practical at scale
How can we keep RUM powerful without the heavy computational cost? By replacing memorization scores with efficient proxies in RUM’s refinement step, we maintain its strong performance with minimal overhead!
Two weeks into the unlearning challenge and there are already 400 submissions! Now’s the perfect time to join the challenge and help develop new machine learning algorithms that can safely and effectively unlearn outdated or harmful information.
https://t.co/XFp7nJgmve
📢The NeurIPS 2023 Unlearning Competition is now open for submissions @kaggle !📢 Goal is to develop algorithms that can unlearn a subset of the training data. Competition is open to all, and there are prizes for the top performers!. https://t.co/KhoenxhQqG