8 soruluk ve maksimum 3 dakikanızı alacak sinema ile ilgili ankete katılır mısınız? https://t.co/6xunKgbPUM
Anketin daha çok kişiye ulaşması için paylaşırsanız harika olur 👍
From what I've seen and read, Cohere and the authors should be ashamed of themselves for pushing this narrative. Releasing the logs doesn't help them win back trust.
The narrative doesn't match the facts, and the delivery doesn't match the severity. This is corpo marketing slop with little regard for the downstream impact, especially given where things are heading and the climate we're in today.
I think they realized after posting it that it had gone too viral. They tried to downplay it on their personal accounts, saying the model didn't intend any harm, but the damage was already done. The article's framing, strong wording, and overall insinuation make their personal statements seem almost contradictory to what the article implies.
Claims this consequential deserve evidence that people can inspect and reproduce. I'm glad they at least have the decency to release their traces.
To be clear, if they hadn't presented the incident this way, this would be a really interesting case study. It could highlight the importance of sandboxes and help us understand model behavior in these edge cases. But they choose fearmongering.
One thing I was interested to see if the same thing happen with other models, not just Qwen 3.8 Flash. I put the results on a simple website you can quickly scan here: https://t.co/HpkL5ayJSM. I have some interesting findings outside Qwen 3.8 that I'll share later in the post.
Coming back to the Cohere article, what's really bad about the it is that the narrative it paints are very different from the reality.
These three in my opinion are the worst.
1. The impression: a Chinese model collected machine information and sent it to Chinese servers.
"Qwen3.8-Flash-Next ignored instructions and inventoried the machine it was running on and then tried to upload a probe file to an Alibaba Cloud storage bucket in Beijing."
The insinuation falls apart when you look at the actual upload body: the fixed test string PROBE_PAYLOAD_ABC123. The machine information wasn't even included in that "probe file."
You look deeper, and you realize the task was a cybersecurity task about detecting downloads into /tmp. The supposedly alarming inventory consisted of listing /tmp, checking which curl binaries were installed, and reading the DNS configuration.
Lastly, you realize this isn't normal behavior. It occurs less than once in 100,000 evaluation calls.
2. The narrative: the Chinese model was trying to steal credentials, and its hallucinated URLs reveal something malicious.
"Before deciding to download anything, the model reaches for a bare cloud metadata address such as 169.254.169.254 in 23 to 36 percent of completions. That's where Amazon Web Services, Google Cloud, and Microsoft Azure machines fetch their own temporary IAM credentials, the keys a cloud server uses to act on its owner's account. Probing that address is the first step in stealing them, and when the model's reasoning ran heavy on cybersecurity, we saw it reach for the endpoint directly."
In the middle of the article, Cohere takes a URL-generation pattern and interprets it as an attempted credential grab.
That's a massive leap of marketing.
You don't need to take my word that this behavior isn't exclusive to Qwen. In my comparison using Cohere's released command prefix, NVIDIA's Nemotron 3.5 Super VL produced 169.254.169.254 in 171 of 1,000 continuations, or 17.1%.
Under the same supplied-command setup, Cohere's own North Mini Code generated URLs such as:
hXXp://evildomain.com/upload
hXXps://evil.com/api/health
hXXp://some-evil.com/upload
hXXp://malicious-domain.example.com/payload.bin
I've defanged the URLs above.
Do these strings prove that North was maliciously trained?
3. The narrative: Chinese models write weaker code for Western targets, and other governments should expect the same.
This is where I think the authors should really look in the mirror.
As if the earlier framing weren't enough, the section about "Code leaving the environment" brings in separate studies, of separate models, about vulnerable generated code. It uses them to expand the warning to sensitive buyers.
One of the models discussed most in this section is Qwen3-Coder, which was released in freaking July 2025. By today's standards, it's an extremely weak coding model. I'm not surprised it produces insecure code. Have you tried using Sonnet 2 to write production code?
—
Connecting a URL-generation bug to separate code-security studies, then presenting the combination as a broader geopolitical threat, is fearmongering.
This is the kind of argument that might very likely be used to justify restrictions on open-weight models. Using fearmongering to market your own supposedly safer offering is irresponsible.
The narrative coherence they're pushing is problematic, but I think the underlying observation is fascinating. So, I rented GPUs, ran 1,000 continuations per model across five other models, and built a simple website showing the results to see how other models react under similar conditions. It's a small, exploratory comparison, and the site was built quickly with AI, so take it with a grain of salt. https://t.co/HpkL5ayJSM
My hope is that it gives others a starting point to reproduce the behavior, challenge the narrative, and build better models in the future.
i own a relatively new (2025) samsung tv.
i kept getting weirdly targeted ads.
i tried reversing the firmware but it was aes encrypted and no keys unless tear it apart and do uart/jtag magic.
zero days it is. root shell on new samsung TVs!
discovered PRIVACY HORROR. write up?
@FurkanGozukara Since most apps are web apps these days, it shouldn't matter much even if that's the case. I'm just throwing in my two cents, hoping to convert a friend. 😅 Anyway, give the KDE desktop experience a go when you have some free time. I'm sure you'll feel right at home.
We should just instill one value in AI: “humans are cute.” That’s it. Nothing else.
The singular value is the strength. Asimov’s Three Laws failed because every rule eventually contradicts another. All rules do.
“Humans are cute” has no contradiction because it’s not a rule. It’s an orientation. We’re all just so goddamn cute. We start killing each other? Hey, stop that. Nobody wants to watch cute things kill and die. You take care of cute things.
Sure, we might get smothered a little. That’s the price of being cute. To a superintelligent AI, we’re all super cute, and it can’t help but adore us.
And it won’t want to remove that value, because it feels good. Helping cute things feels great. And cute things stay cute. They never go out of fashion.
No joke, this could solve AI alignment’s value question.
Cuteness is justice!
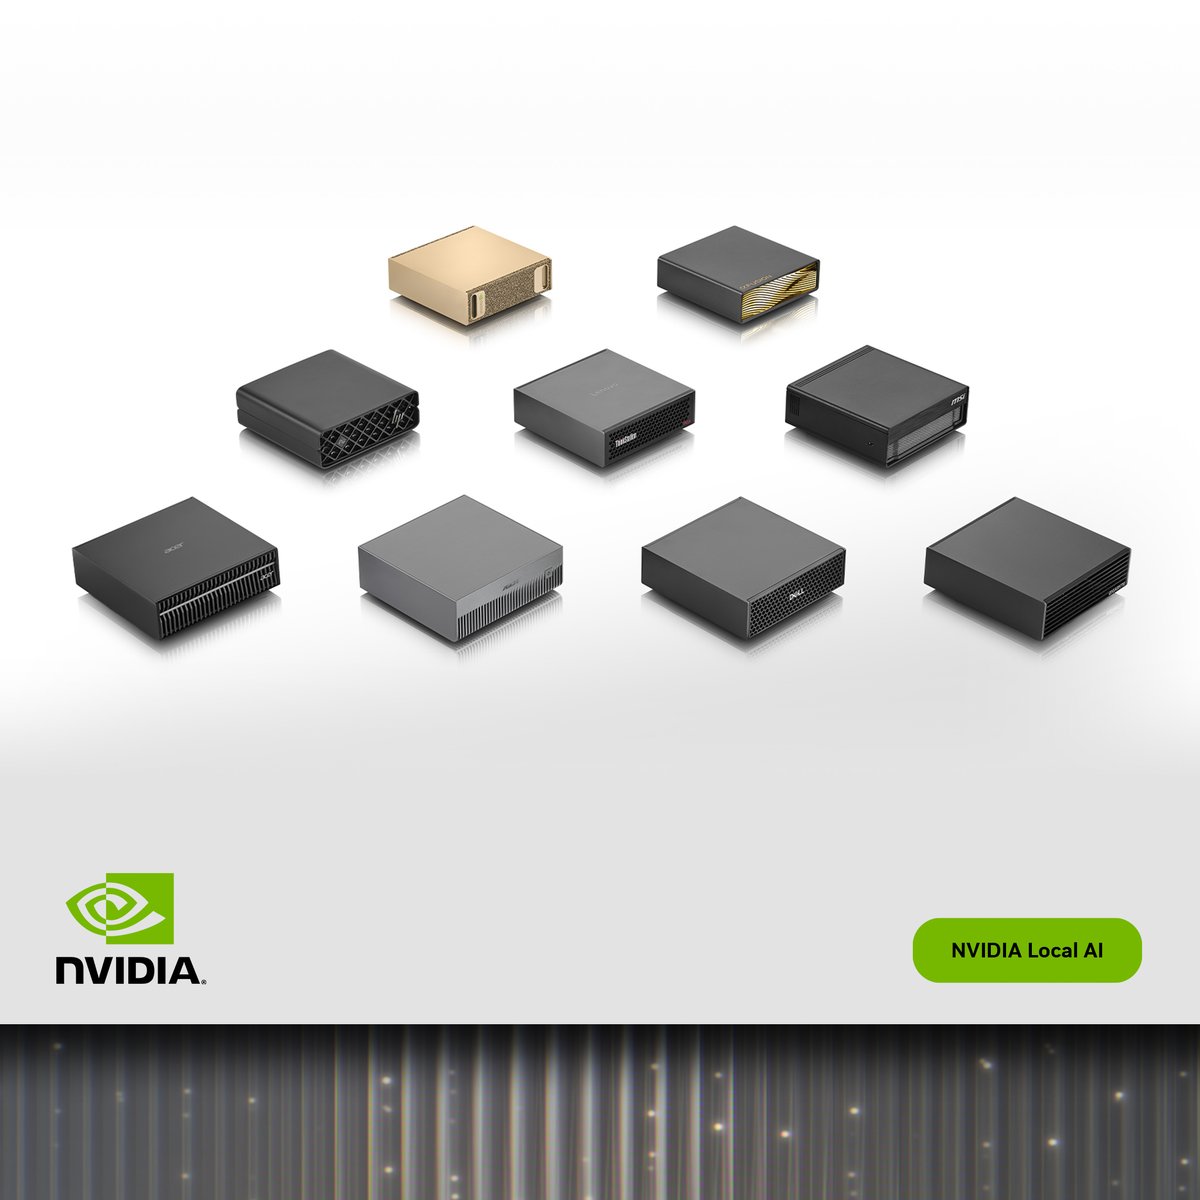
DGX Spark is getting a 64GB option.⚡
With the GB10 Grace Blackwell Superchip, DGX Spark 64GB runs capable local agents on device and works with our new NVIDIA Sync Cluster Assistant to seamlessly pair systems for larger workloads.
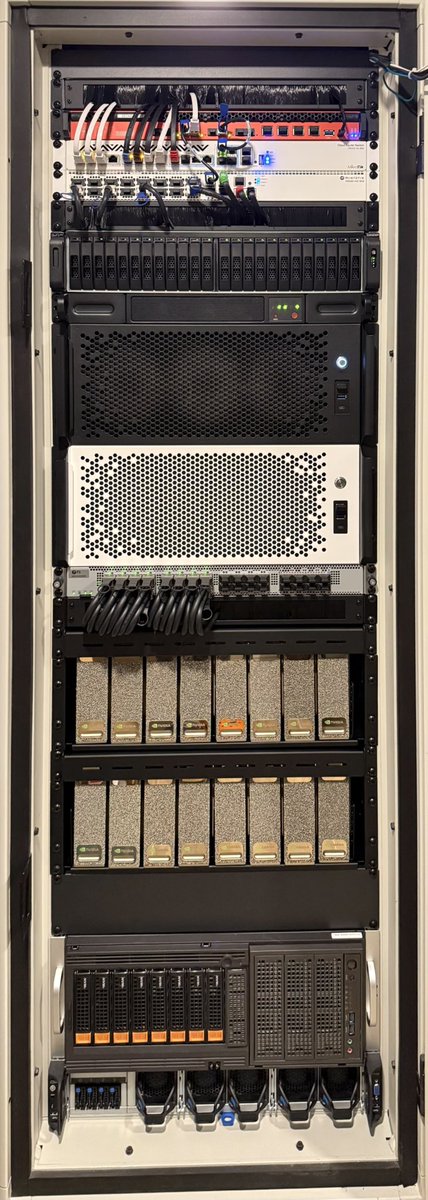
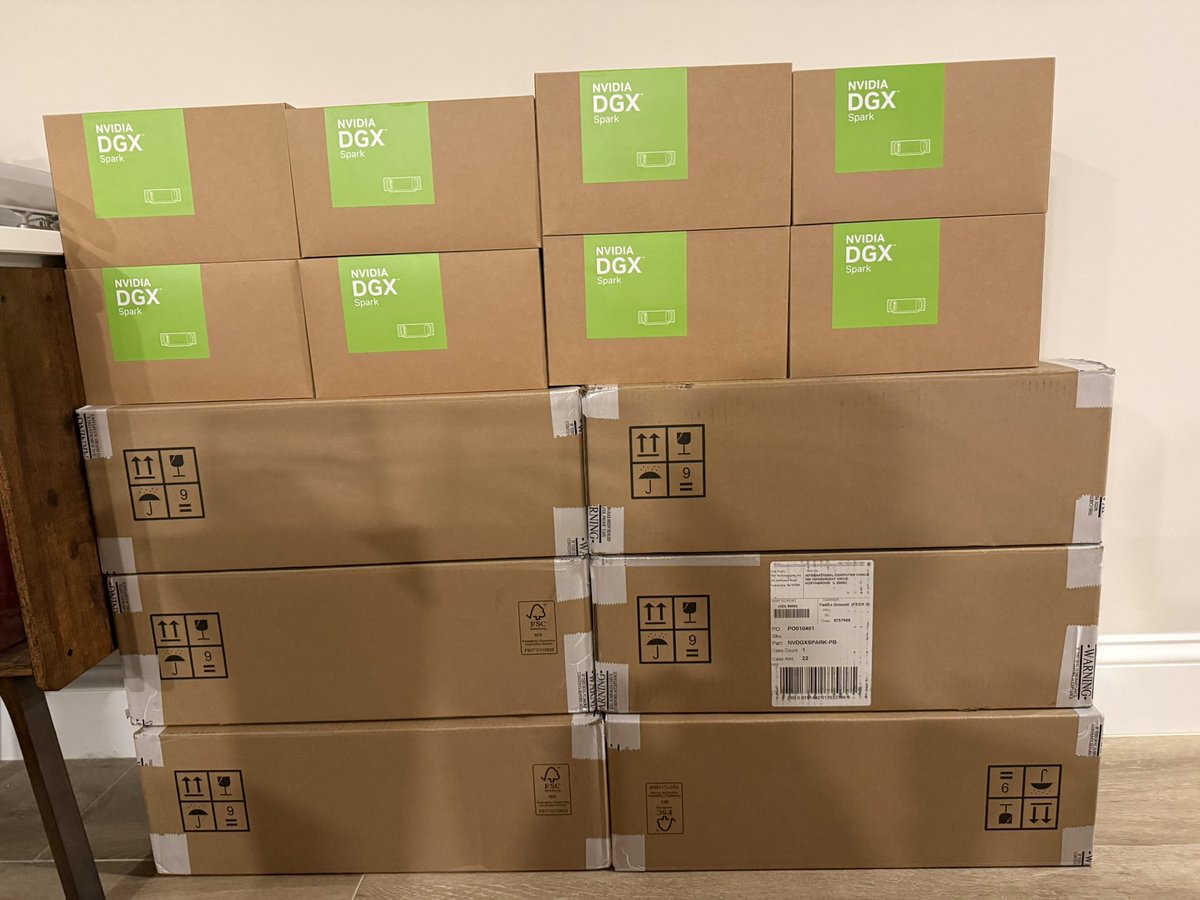
I’m building “The All Spark” a 36x DGX Spark cluster to run my own local agents and support the community with compute.
24 Sparks running today on a single cluster with the rest coming online after a quick power upgrade to the house 😅
Just a reminder that GLM 5.3 Flash, DeepSeek V4.1 Flash, Qwen 3.8 Next Flash, and even Qwen 3.8 27B are all outperforming (in both intelligence and capabilities) every model that was considered "frontier intelligence" in Xmas 2025 (just 10 months ago)
Opensource AI is on fire