Introducing Gemini 4 Carbon, it's a big jump over Argon which we released just 2 weeks ago.
Gemini 4 Carbon is SOTA on cyber, long horizon tasks, ranks #1 on Artificial Analysis V5, significantly improves on usability in domains like coding, and is more aligned.
This is Genie 4, our most realistic and interactive world model yet. 🌐
Explore dynamic environments in real time to see how the scene responds, sounds, and how the people in it move, react, and speak.
Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence.
> 6 model instances, across text, audio, vision, and omni modalities, generative and decision models.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱: text, 256k context window.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱: vision-language model with video-input support for spatial understanding
> 𝙻𝙵𝙼𝟹-𝙰𝚞𝚍𝚒𝚘-𝟸𝙱: tool calls, voice chat, reasoning in 18 languages.
> 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱: an omni model combines vision, audio, and language.
> 𝚍𝟷-𝟸𝙱 and 𝚍𝟷-𝙾𝚖𝚗𝚒-𝟸𝙱: decision models with typed outputs and calibrated probabilities in a single pass. Omni adds audio input.
> fine-tune on 1 GPU.
> a new tri-hybrid architecture
> architecture optimized for 14 processor classes across GPUs, CPUs, and NPUs.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱 is a beast. It performs competitively with Gemma 4 12B (6x larger), and Gemini 3.5 Flash Lite, and GPT-5.6 Luna, with 1.9B parameters.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 is #1 on the Pareto frontier of device intelligence 𝚙𝚒𝚙𝚎𝚝𝚝𝚎.𝚕𝚒𝚚𝚞𝚒𝚍.𝚊𝚒
Every modality for specialized intelligence. Pick the one that fits your use case, customize it, and run it on-device.
1/ 🧵
Hi all, I have a new result I'm excited to share. It turns out that *all existing implementations* of softmax and cross-entropy (that's JAX, PyTorch, textbooks, etc) have a subtle bug --- two bugs, actually. A simple rewrite fixes both, and eliminates "slingshots" when grokking:
Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
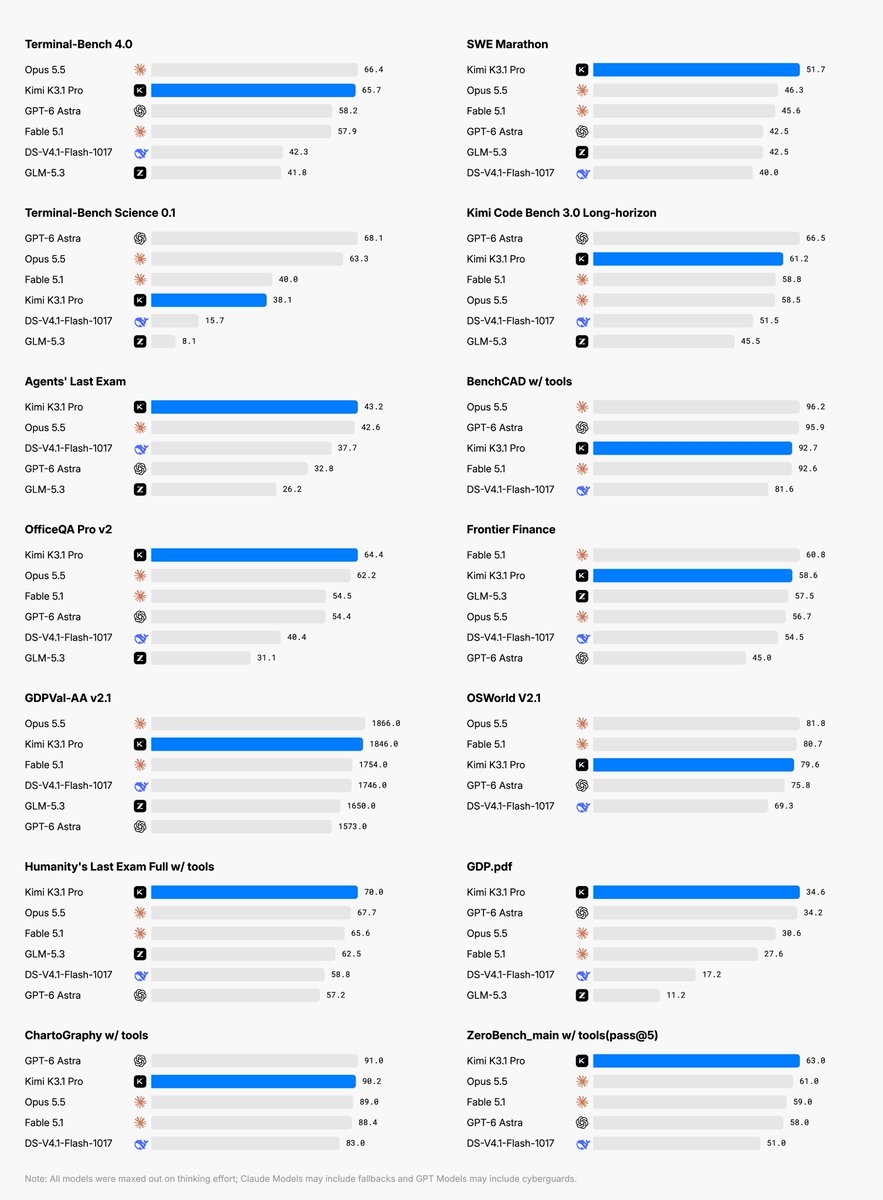
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on https://t.co/85jA71X9gw, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: https://t.co/XCrgjXAqMw
🔗 Tech blog: https://t.co/5iPP0MBej6
We now have state-of-the-art pre-trained base models in the 3T-parameter weight class, built entirely in-house at MAI.
Post-training results coming soon -- stay tuned!
Lots of details in our technical blog post.
https://t.co/xcZ5uV4TAp
Today we are rolling out Gemini 4 Argon globally in the Gemini API, to Pro + Ultra in Gemini App, and Ultra subs in Antigravity!
Argon is a huge step forward for Gemini, and a labor of love. This model has been battle tested by over 100,000 people at Google over the last month, with so much new innovation, ambition, and hard work baked into this release. The team has been heads down over the last 6 months working to make this possible across the stack (research, infra, safety, eng, etc).
We rolled the model out to cyber defenders as part of our fairwind program and early access customers over the last 2 weeks, it has been amazing to see and talk to folks who are now using this model daily. Seeing the models writing capability, raw knowledge and persistence for coding, paired with new features like 1M token output when the model needs to work more has gotten me even more excited about our path ahead.
This is just the start of the Gemini 4 era. As you saw with 3.5, 3.6, 3.7, and 3.8 Flash, our iteration speed with Gemini is fast : ) Now with Gemini 4 Argon to work from, I am cannot wait to see the progress continue, and most importantly see what this new model enables for the world.
This is such a special moment in the arc of technology, as millions of people everyday tackle problems they could never have thought possible before. Gemini 4 Argon was built to help you tackle the hardest problems. I have personally felt this spark with Argon and hope you do too. Onwards!!
Our paper on retrofitting language models to operate over bytes – the approach behind Bolmo – has been accepted to Nature! 🎉
We’re also releasing new checkpoints that extend our method from Olmo to Qwen & Llama. 🧵
https://t.co/3BEKIKsQIk
Meet EmbeddingGemma 2, our first natively multimodal open model for on-device embeddings.
It expands beyond text to unify code, images, audio, and video in a shared space. 🧵
Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
チューリング、新しいテックブログを公開しました。
PB級データをS3から直接ストリーミングで読み込み、GPU近傍の高速ストレージを介さずそのまま学習する技術の解説です。
Range GETと先読みでレイテンシを減らし、20ノードで約483GB/s(!)の読み出しを実現しています👇
https://t.co/PUuZDfBCTn
Up, up, and away. 🚀
Today, in partnership with @planet, we launched a prototype satellite carrying four TPUs into orbit on @SpaceX's Transporter-18 rideshare mission. This launch is the first step of Project Suncatcher, our long-term research moonshot to see whether we can one day host scalable machine learning infrastructure in space.
Over the coming weeks, we'll gather in-orbit data on how our TPUs handle the physical stress, radiation, and thermal extremes of space. Whatever we learn, we'll use it to refine our future designs.
We’re releasing Olmo-core 3—open training infrastructure for large mixture-of-experts (MoE) models.
It’s a core system behind the next generation of Olmo, designed to scale into the trillion-parameter range. 🧵
💻 GitHub repo: https://t.co/JT9Y3851gU