Voice is the biggest untapped dataset in the enterprise. We've been going after it from day one, and today we're adding fuel. 🚀
Otter has closed $320M in growth financing from @generalcatalyst's Customer Value Fund to accelerate our mission of becoming the voice system of record for every enterprise.
40M+ users. 86% of the Fortune 500. 1B+ meetings transcribed. $1.5B in customer ROI. And we're only getting started. ☄️
https://t.co/I94E9vcpd0
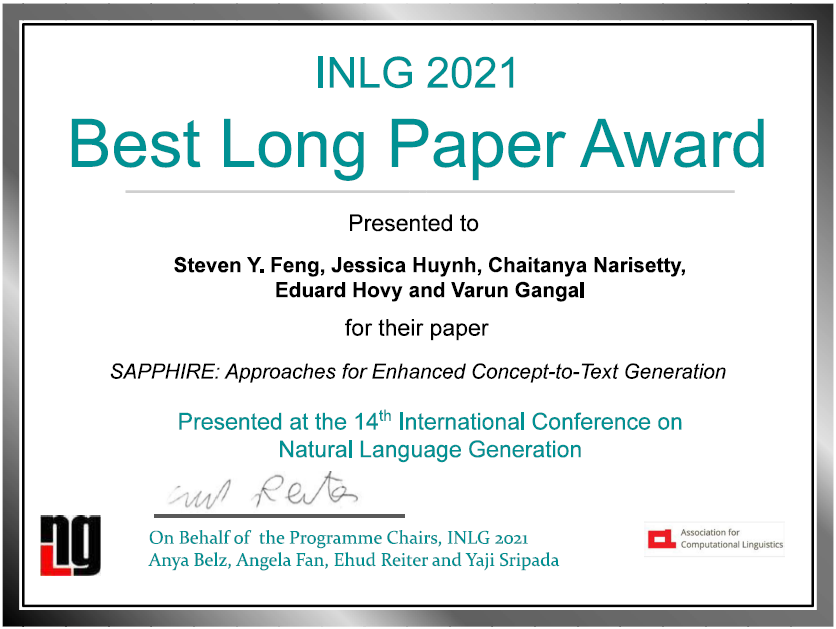
Congrats to LTI members @stevenyfeng, Jessica Huynh, @neonatil, Eduard Hovy, and @VarunGangal on winning Best Long Paper at #INLG2021! Check out their poster tomorrow at @inlgmeeting from 1:40PM-2:40PM (UTC+1, Aberdeen time), or 8:40AM-9:40AM EST. Paper: https://t.co/bmwQyHGoF7
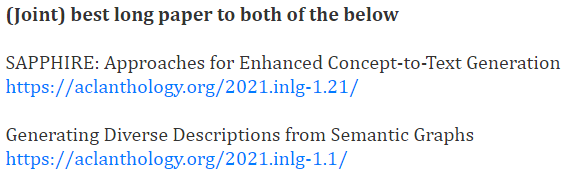
And we have two joint winners of the best long paper award for #INLG2021: "SAPPHIRE: Approaches for Enhanced Concept-to-Text Generation" by Feng, Huynh, Narisetty, Hovy, & Gangal and "Generating Diverse Descriptions from Semantic Graphs" Han, Beck, & Cohn!
Thrilled to announce that our SAPPHIRE work has won BEST LONG PAPER at #INLG2021! Paper here: https://t.co/zDoQK0vv6g
I'll be presenting a poster tomorrow (Wednesday) at @inlgmeeting from 1:40PM-2:40PM (UTC+1, Aberdeen time), so 8:40am-9:40am EST. Come check it out! #NLProc#NLG
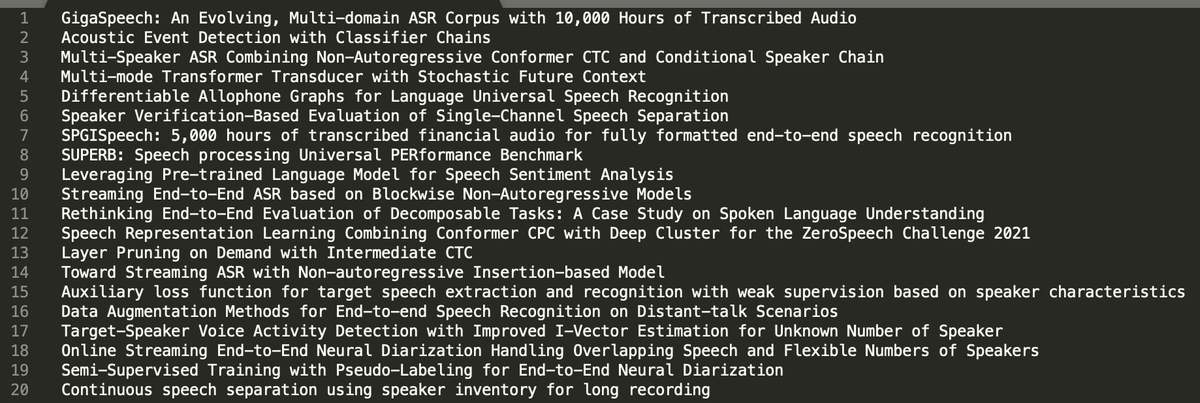
Our lab will be presenting 20 papers at #INTERSPEECH2021!
This is also our inaugural tweet 👋
Follow for updates future updates on our research activities in **end-to-end speech** recognition, enhancement, translation, etc. + open-source developments on ESPnet.
@AdityaPrasadN Tensorflow has a custom release for M1 that's incredibly fast, at least for inference. Still waiting for pytorch to release it's supported version.