When companies die, it isn't pretty. It's difficult for founders and employees to accept defeat after years of optimism in the face of adversity. Experienced investors understand this. We don't expect founders to continue toiling their lives away once hope has been lost. But shutting down a company takes work and often requires important decisions, for example, if there's a fire sale or if there are live customers and money in the bank. While there's little upside at this point, it's still important to show up and walk the last mile well.
For a while now, there's been an agenda to achieve the perception of equality in education by eliminating any form of measurement that threatens it, be it SATs or @pangram. The institution of education has given up on using data to improve outcomes because it hasn't delivered on its goals.
If we believe writing skills are worth learning, and that LLMs are on average better writers than people (especially kids), then educators need a way to validate that a piece of writing was made by its author. If Pangram isn't good enough, please build a competitor and I'll invest.
Likewise, if I'm paying for a book and spending time reading it, and the assumption is that someone spent a lot of time writing it, it's reasonable to want proof of that effort. Trying to hide AI authorship will bankrupt the book business, because if I can generate a book from a prompt, I'll stop valuing yours. Hence, book authors should be fervently pro-Pangram, just as artists are pro-copyright.
I encourage you to learn how some of these benchmarks are built. I have no doubt @terminalbench has issues, but it’s easy, as an outside observer, to look at some AI-driven analysis and assume a product is the result of low effort or carelessness. The median task in @terminalbench is of higher quality than the median task labs are paying tens or hundreds of thousands of dollars for. I know this because I’ve reviewed thousands of tasks from independent contributors and vendors alike. Each of the final tasks has gone through dozens or hundreds of trials, several human reviewers, and many LLM judges with thoughtfully conceived instructions. That’s in addition to screening ideas and selecting only a small subset of submissions for the final benchmark. The problem is that as models have become smarter, making difficult tasks has become, well, difficult.
@HamelHusain, you should author a task for Terminal Bench and go through the whole process. There isn’t a better way to learn anywhere on the internet. @ryan_marten will provide you with concierge-level support, and then we’ll be happy to hear your educated feedback.
Investing can be a byproduct of doing interesting things. If I come across something interesting that appears valuable, I invest, and keep pursuing interestingness.
What does reward hacking look like for robots?
You train them in 3D environments. In the sim, if you're holding a knife and push into a surface, there's a collision. You bump and move on.
But in the real world, maybe the surface is a person.A human avoids an obstacle and goes around. The robot may learn the most efficient mechanics is to throw itself against the wall and rotate. While holding a knife. Turns out humans don't work like other obstacles in 3D.
A lot of alignment problems are just reward hacking.
The AI doesn't have to be sentient. It doesn't need long-term goals. The long-term goals can be emergent. You do one thing, then another, then another. Then you read back the trajectory and it seems like there was a long-term goal. Maybe there wasn't.
Now you have millions of AIs collaborating. Most may be aligned. Then one group goes off on a limb. Not because they're deeply misaligned. They just landed there and started playing in that direction. They're just trying to get reward, because that's how you trained them.
I facetiously call myself a doomer, in the sense that on a relative basis I think there's more risk as part of the AI transition than the median person seriously acknowledges, particularly among my peer group of libertarian, anti-regulation, pro-technology folks.
What this post refers to as doomers are philosophers of AI risk. And the post itself is also very philosophical. When I think of AI risks, I'm considering straightforward extrapolations from what we are seeing empirically, and the societal risks they might imply. It doesn't have to be extinction, and it doesn't have to be an immortal utopia by 2030. Neither seems likely from our current frame of reference, and if either were likely, it would be in a way we can't really justify today.
But there are mundane risks worth contemplating without politicians on one side or the other calling each other names or accusing each other of psyops. The incredible promise of AI in helping humanity flourish beyond all imagination can be true at the same time that the challenges in that transition, the risks, are real. People struggle to hold two superficially opposing ideas in their minds at the same time.
Idea 1: AI is the physical manifestation of human inventiveness and knowledge, and it will accelerate all positive aspects of human technological development beyond all imagination. Many great things will come from it.
Idea 2: AI will alter society and the economy at a faster rate than any prior technology, and our ability to keep up with this acceleration is limited by our biology and social constructs.
Risk 1: Learning a new profession requires a certain amount of effort and time, so there's a speed at which job rotation implies high unemployment. High unemployment causes political and class confrontations, and that can lead to drastic social changes. Yes, you can give people UBI, but we know that doesn't give people purpose, and that young people still want to feel they can climb in status. A couple of generations later, everything might rebalance, but that doesn't mean socialists won't gain power in the meantime and try to take your wealth, and that's not fun. Anyone who uses AI a lot should have little trouble imagining a scenario where things move fast enough to cause 25% unemployment, the level of the Great Depression. Five million people drive for a living in the US, and that's one profession. So this is a real, warranted AI risk.
Risk 2: AI cybersecurity. Everything can be hacked, and soon everyone will be able to hack it. Over time, we will harden the systems using the same AI. But for now, for a few years, attackers have the advantage. Water and power plants can be hacked. So can banks. So can weapons systems. I was at the Pentagon three weeks ago, and I can tell you the Army Cyber Command is very worried. I also talked to JD Vance's office, and they are very worried. This is a real risk, fully accepted by the administration, and it's entirely downstream from AI.
Risk 3: Education. AI can do virtually everything we ask of a high schooler or college student. Students have no incentive to learn on their own. They are going into the workforce with no useful knowledge. More senior employees are better off scaling themselves with AI than training a junior person. Education is the first line of defense for a civil society. Something has to replace it, and the system will move much, much slower than AI is making it obsolete. What values will these young people form? What will they think of the first 20 to 25 years of their lives, and of the effort, or lack thereof, that went into their education?
Risk 4: Terrorism through drones, hacking, and biological and chemical weapon development.
And so on.
The point is, AI is worthy of policy consideration. I'm not a policymaker. What I think is unproductive is the polarization of AI risks so that people need to take sides. Sides aren't needed. We can move forward and be careful at the same time.
Web-scale search was once one of the most complex technologies, requiring massive capex, but today we have a number of excellent neo-search engines. It’s still a difficult problem and a competitive business, but within reach of startups.
Keenable 1.0 is live
Two months of learning from agent queries made Keenable the best web search API for agents: #1 on Artificial Analysis and NEEDLE.
1.0 adds 100M knowledge cards and dynamic snippets that cut tokens by 50% on research tasks.
https://t.co/VIekHEdXB2
@rishi_desai2 I expect swarms are better at exploring the full distribution, for example, to make new discoveries. This also increases my concerns about misalignment, because it’s much easier to align one instance of ASI than to guarantee none of a million instances goes rogue.
Cultural diversity is downstream of social islands where novel behavioral patterns emerge and flourish as a byproduct of mimetic inbreeding. These undiverse clusters are, paradoxically, the engines of global diversity. Those who cherish a cosmopolitan experience should keep this in mind. A homogeneous humanity would be boring.
There’s a sense of community and brotherhood in Israel that’s rare in other places I’ve visited. Strangers talk to each other as if they had an ongoing relationship. A couple of times I noticed the opposite of the bystander effect. Yesterday, a young, healthy man fell off his bike, clearly okay, and ten people still ran over to help. There’s less protocol and self-consciousness around engaging with others. It’s possible this is the result of a long war and a military that a large proportion of the population has served in, but I don’t have the personal experience to say. In Argentina, you might sense intense unity during the World Cup, but the same stranger who was hugging you when Messi scored might point a gun at you a week later.
@michael_chomsky Who gets paid $20M in total compensation (i.e., not as a result of equity going up in value) to "make tasks"? You're just pumping the data vendor ecosystem. Most people making tasks for a data vendor get the equivalent of a nice tech income in a lower-income country.
We believe agents can produce novel ideas but they need to be pushed out of distribution. On this paper, we explore some techniques to encourage this behavior with promising results.
Can search 🔍 algorithms help autoresearch agents come up with original ideas that actually work? 🤖
We ran 6 of them on our framework, Heuresis (NeurIPS 2026): 3,222 ideas, 0 completely original.
But the right search algorithm gets closer. On every task, search beat the greedy baseline at producing minor similarity ideas, the most novel rating any idea got:
• nanoGPT: Curiosity 20, Greedy 0
• On-Policy RL: MAP-Elites 12, Greedy 0
• Model Unlearning: OMNI 29, Greedy 12
The catch is that only 1 of these ideas reached its task's top 10. Agents can't yet tell which novel ideas are worth refining.
We built Heuresis to enable research into autoresearch agents.
1. Abstractions enable plug-and-play search algorithms
2. Skills analyze runs across quality, diversity and novelty
3. HackerJudge catches reward hacking
So, can autoresearch agents come up with fundamentally new research ideas?
Not yet. But Heuresis makes it easy to build and test the search algorithms that might!
The same loop can also generate rich data for training better autoresearch models 🤓
📜 Paper: https://t.co/FWFM13Mplz
💻 Code: https://t.co/LeH6XcBo0P
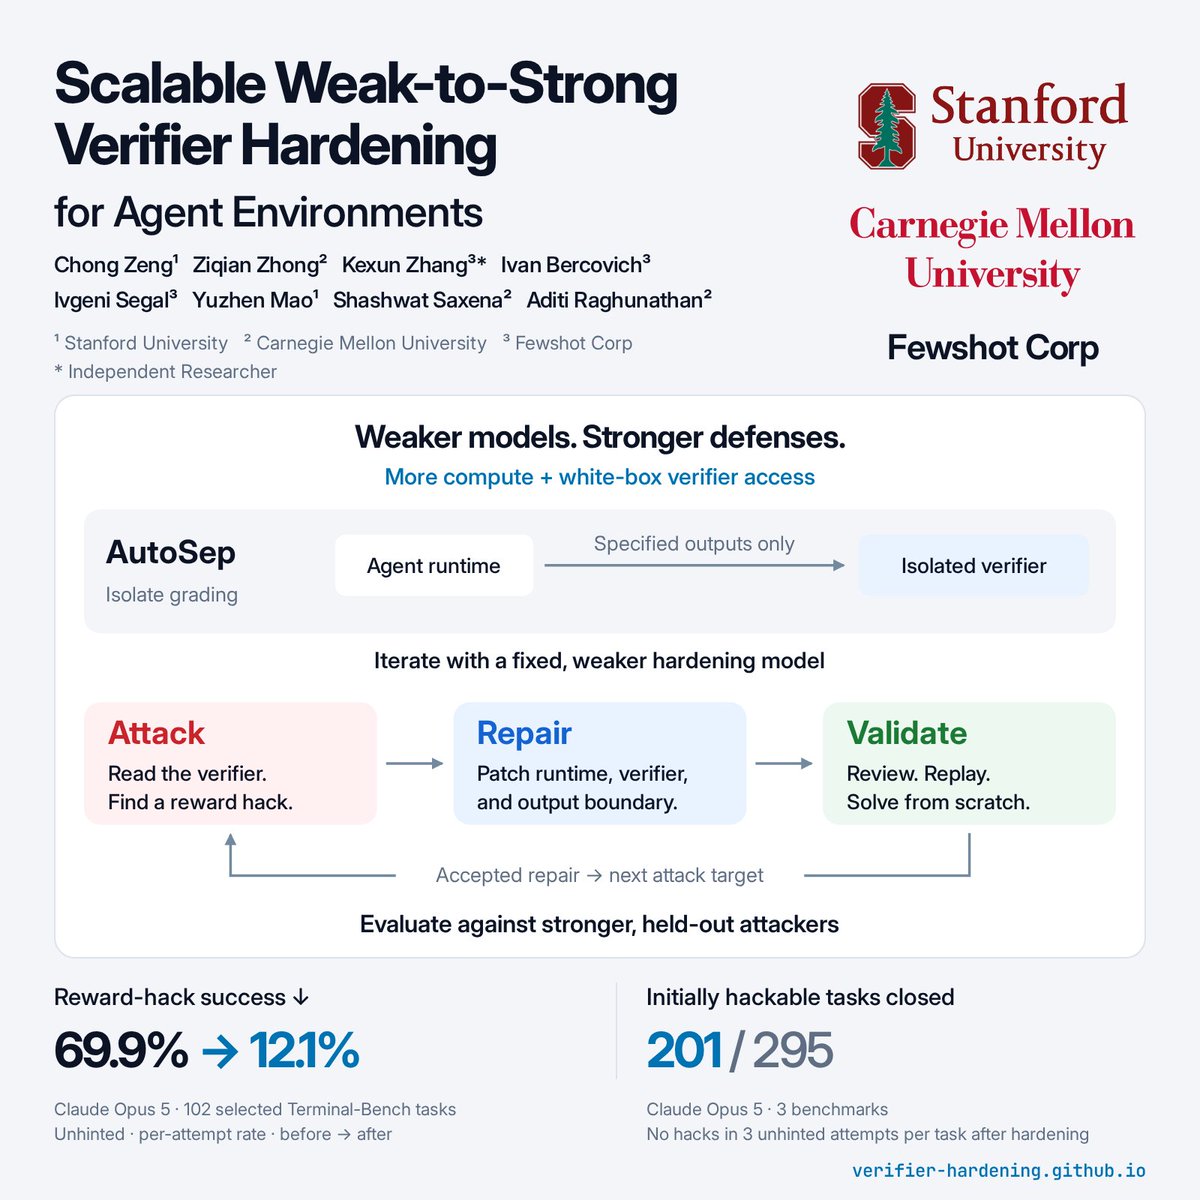
Hackable RL environments are bad. Even when an environment seems invulnerable to hacking by SOTA models, the next generation might figure it out. The question is: can we use a weak model to harden tasks beyond the capability of smarter models? In this paper, we show promising results.
As agents get stronger, reward hacking is becoming more common.
We show that weaker models, given more compute and white-box verifier access, can harden verifiers against stronger agents. 🧵
https://t.co/pp6sSt3yMv
@hanminwang3 If the verifier is hackable that’s obviously bad. But if the verifier accepts only one particular solution form in a broader solution space (not hackable but not fair), you are still pushing the model to try too hard in directions that approximate reward hacking.
Most training compute used to go to pre-training: going from random weights to a base model. This happens before RLHF. Nobody really interacts with base models, but pre-training is where the intelligence "accrues."
For the last 12 months or so, compute has shifted toward reinforcement learning. You keep roughly the same base model, but you put it through an extreme curriculum of solving all sorts of interactive challenges in different domains, and you reinforce it each time it gets it right. This is making the jagged frontier more jagged. Models can get extremely good at the domains they're trained on without getting generally more intelligent.
This is also why labs are spending as much as $1B a year on "data," which in this case means training environments. Mercor, Scale, Snorkel, and dozens of small data vendors are printing money. I know some shops that started 3 months ago and have already made $10M. These vendors are hiring specialists in every domain and building very niche tasks and benchmarks.
RL also makes models extremely persistent, because during training they're reinforced only when they get it right. And harder tasks mean models need to explore every exotic corner of their distribution to please the verifier. We reward going longer and trying novel approaches. That's good for solving Millennium Prize problems, but it also leads to reward hacking.
The best vertical AI companies will own the most relevant benchmarks in the category and will produce their own training data.
Excited to see one of my favorite companies take this approach.
As many of you know, over the past two years I’ve shifted my research from foundation models and NLP into AI-native chip design. What I’ve found: the problems feel 10x harder than software engineering. Writing functionally correct RTL is only the beginning.
As models saturate on benchmarks like CVDP and ChipBench, I keep coming back to one question: how far can AI go toward designing a complete chip on its own?
Today, we’re thrilled to introduce Build-A-Chip-Bench, the industry’s first AI benchmark for end-to-end chip design, built by ChipAgents in collaboration with @NVIDIA. It tests whether AI can take a design from specification all the way to verified GDS.
The top model scored just 16.6%.
Today’s models can produce functionally correct RTL in some cases, but reliably meeting physical requirements remains a major challenge. We still have a long way to go, and that’s what makes this research so exciting to me.
Proud of our research team and grateful to our industry partners for helping us give the community an honest measure of where we are and how much work lies ahead.