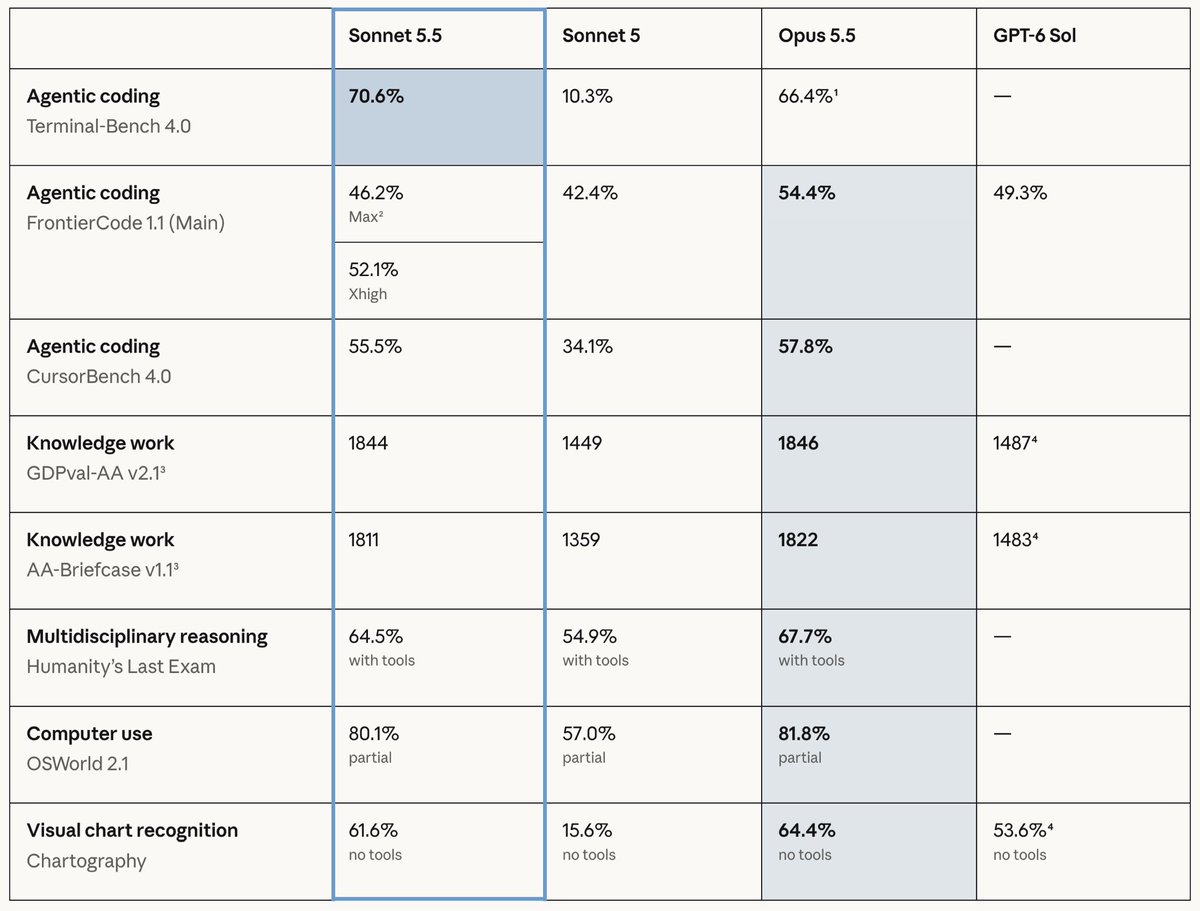
Anthropic has launched Claude Sonnet 5.5: it scores 56 on the Artificial Analysis Intelligence Index, just 2 points behind Opus 5.5 (max), but at the highest Output Tokens per Task we’ve seen
With max effort, Sonnet 5.5 gains 18 points over Sonnet 5 and to #2 on the Intelligence Index behind only Opus 5.5 (max). Anthropic has priced Sonnet 5.5 identically to Sonnet 5 at $0.2/$2/$10 per 1M cache input/input/output tokens, however it outputs a higher number of Output Tokens per Task and costs $7.60 per task (~50% higher than Sonnet 5’s Cost per Task)
Key takeaways:
➤ Meets leading models on agentic terminal use and knowledge work: in Terminal-Bench 4.0, Claude Sonnet 5.5 reaches 64% against 60% for Opus 5.5 and GPT-6 Astra. On AA-Briefcase (1811 vs 1822 Elo), GDPval-AA (1844 vs 1846 Elo), and AutomationBench-AA (71% vs 70% headline score), Sonnet 5.5 reaches parity with Opus 5.5, albeit with significantly higher token usage to achieve it
➤ Heaviest token use we have measured: at max effort, where it reaches performance nearing that of Opus 5.5, Claude Sonnet 5.5 used ~193k Output Tokens per Intelligence Index Task. This is the highest token use we have measured on around 60% higher than Opus 5.5 (max) or Sonnet 5 (max) and ~7x GPT-6 Astra (max)
➤ Pricing remains at $2/$10 per million tokens of input/output, matching GPT-6 Sol. At this pricing Claude Sonnet 5.5 sits off the Intelligence vs. Cost per Task Pareto Frontier. At high effort levels it sits behind Opus 5.5, while lower efforts have GPT-6 Astra or Sol configurations delivering equivalent performance for lower cost. The high effort setting is the most competitive on this basis, sitting very narrowly behind GPT-6 Sol on Intelligence at effectively the same Cost per Task
➤ Behind Opus 5.5 on factual knowledge and scientific reasoning: as a smaller class model, Sonnet 5.5 still lags on factual knowledge in AA-Omniscience compared to Opus 5.5. It scores 54% against 66% for factual accuracy, though with a lower hallucination rate (47% against 59%). It also sits ~6 points lower on Humanity's Last Exam and SciCode compared to Opus
These evaluations were conducted on a pre-release deployment of Claude Sonnet 5.5, which Anthropic found to have a bug that can degrade responses to requests that use structured outputs. This is fixed for the public release and Anthropic expects minimal change or slightly understated performance, but we will be re-running relevant evaluations soon.
Other model details:
➤ Context window: 1 million tokens with image and text input, unchanged from Sonnet 5
➤ Pricing: unchanged from Sonnet 5’s latest $2/$10 per 1M input/output tokens; cache writes at $2.5, cache reads $0.2
➤ Effort settings: five (low, medium, high, xhigh, max). Intelligence Index evaluations were run at all five with Anthropic's default fallback enabled. We see Sonnet 5.5 fall back in ~0.1% of tasks across the Intelligence Index, primarily in TerminalBench 4.0, falling back to Sonnet 5 in all cases.
The OG Blokyz for the top 100 raffle participants are ready to claim
How to claim?
1. Create an account on https://t.co/Sh1E7lJQJq using the same wallet you entered the raffle with by 30th Sep 5 PM UTC
2. Your OG Bloky phygital will get airdropped to you on 1st October
3. Any unclaimed OG blokyz will go back to the team treasury and will be used for future community incentives
These Blokyz will be digital tokens that you can redeem 1:1 for the physical OG Bloky collectible once redemptions open on @dyli_io . Only 100 of these will ever exist.
To check whether your wallet is in top 100 on the leaderboard, visit https://t.co/tJRMt0Jr4i
GLM-5.3-Flash scores 57 on the Artificial Analysis Intelligence Index. At $0.09 Cost per Task, it sits comfortably on the Intelligence vs. Cost per Task Pareto frontier
@Zai_org has released GLM-5.3-Flash, a smaller and cheaper sibling to GLM-5.3 at 320B total parameters and just 18B active parameters. GLM-5.3-Flash supports low/high/max reasoning efforts, and scores 57 evaluation on the Artificial Analysis Intelligence Index with max reasoning effort. This places the model only 3 points behind GLM-5.3 at 60 and in line with GPT-5.6 Terra and Muse Spark 1.2.
On Z AI's first-party API, GLM-5.3-Flash is priced at $0.15 / 1M input tokens and $0.50 / 1M output tokens, just over 10% of the price of GLM-5.3. Cached input tokens are priced at $0.026 / 1M tokens, an 80% discount. Its Cost per Task on the Intelligence Index is $0.09, compared to $0.68 for GLM-5.3 (max), and it sits on the Pareto frontier for Intelligence vs. Cost per Task.
Key results:
➤ GLM-5.3-Flash is 3 points behind GLM-5.3 (max) on the Artificial Analysis Intelligence Index, at ~7.5x lower Cost per Task. At $0.09 per Intelligence Index task against $0.68 for GLM-5.3, it sits on the Pareto frontier for Intelligence vs. Cost per Task. It ties GPT-5.6 Terra ($0.51) and Muse Spark 1.2 ($0.40) at 57 while costing ~5.7x and ~4.4x less per task.
➤ GLM-5.3-Flash is less token efficient, but its low per-token pricing means this does not translate into a high Cost per Task. The model used 149M output tokens to run the Intelligence Index, ~11% fewer than GLM-5.3 at 168M, but more than Kimi K3 (133M) and Qwen3.8 2.4T A95B (136M) which score the same on the Intelligence Index. Reasoning tokens account for 134M of the 149M total (~90%).
➤ GLM-5.3-Flash matches GLM-5.3 on real-world agentic work on GDPval-AA v2. With an Elo of 1770, the model is tied within the margin of error for GLM-5.3 and Grok 4.6. This places it behind only Claude Opus 5 (xhigh and max). On Terminal-Bench v2.1 it also matches GLM-5.3 (84.3% vs 83.9%), and on τ³-Banking it trails by 3.1 p.p. at 47.2%.
➤ GLM-5.3-Flash demonstrates good real-world knowledge and hallucination rate, scoring +7 on AA-Omniscience. Its AA-Omniscience Accuracy is 28%, 6 p.p. below GLM-5.3 (max) at 34% and well below GPT-5.6 Terra at 47%. However, with a Hallucination Rate of 28%, it is an improvement over GLM-5.3 at 30%. In real-world knowledge, GLM-5.3-Flash knows less than the bigger models and frontier proprietary models in its Intelligence Index tier with an accuracy of 28%.
Additional model details:
➤ Pricing: On Z AI's first-party API, $0.15 / 1M input tokens and $0.50 / 1M output tokens . Cached input tokens are priced at $0.03/ 1M tokens, an 80% discount.
➤ Accessibility: Accessible through Z AI's first-party API at launch.
➤ Size: 320B total parameters with 18B active parameters
➤ License: MIT
➤ Context Window: 400k
That's right, GPT-5.6 Sol is awesome and can be used pretty much anywhere, including in the CC harness.
To celebrate this, together with the fact that I'm not going anywhere... I have reset usage limits for all paid users of ChatGPT Work and Codex.
Have fun out there!