same 8B model. 69 tok/s on an RTX 5090, 63 on a Mac Studio M3 Ultra. then you paste 12,500 tokens and one starts answering in 2s, the other in 12s
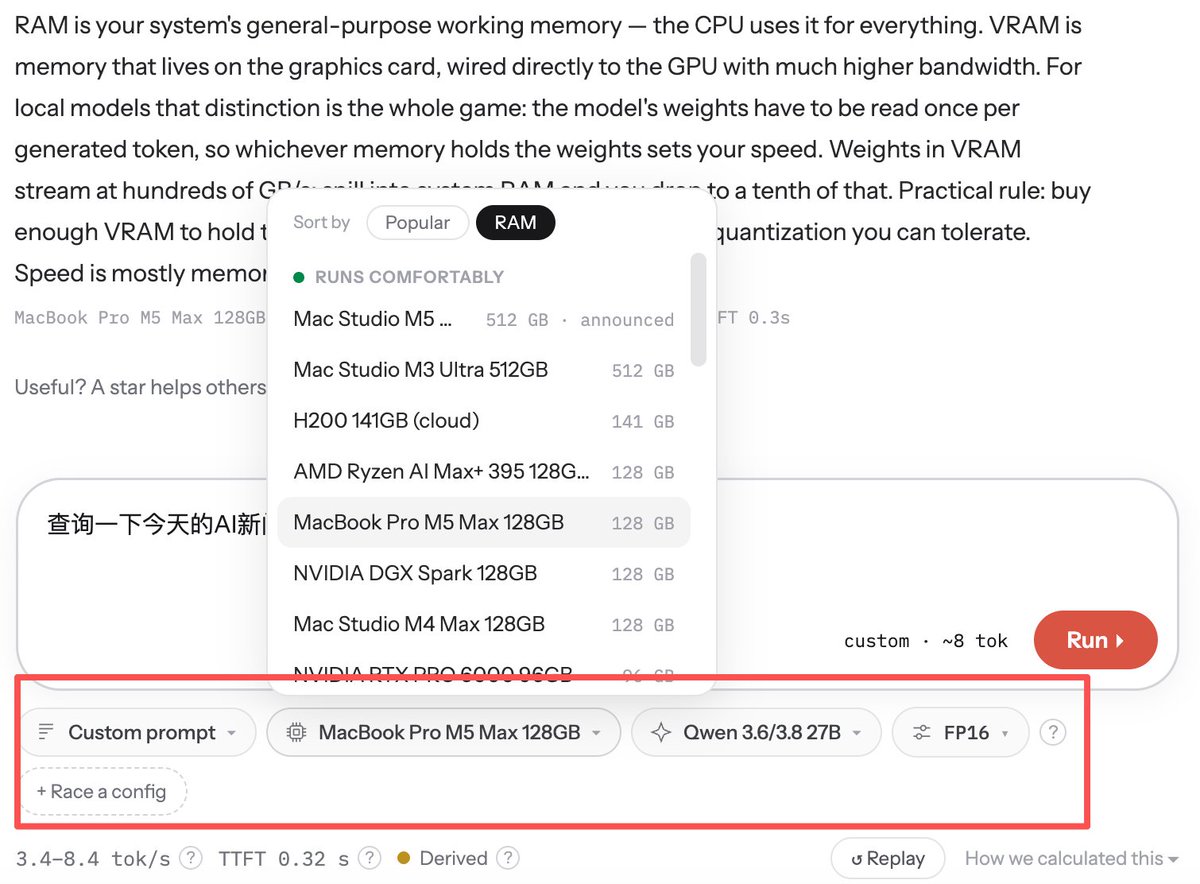
llmspeed is a static site that streams an answer at the tok/s your rig would really hit, after the real wait for the first token. 30 GPUs, Macs and CPUs × 15 models · 1,446 combos. no backend. no signup. Vite + Preact, MIT, one json of predictions
most people still buy hardware off one tok/s screenshot from reddit. llmspeed shows the number that screenshot hides
the idea: a spec sheet lies by omission. a stopwatch doesn't
someone dropped it on Show HN with the whole pipeline open: the benchmark csv, the coefficients and the json the site reads
what runs under the hood:
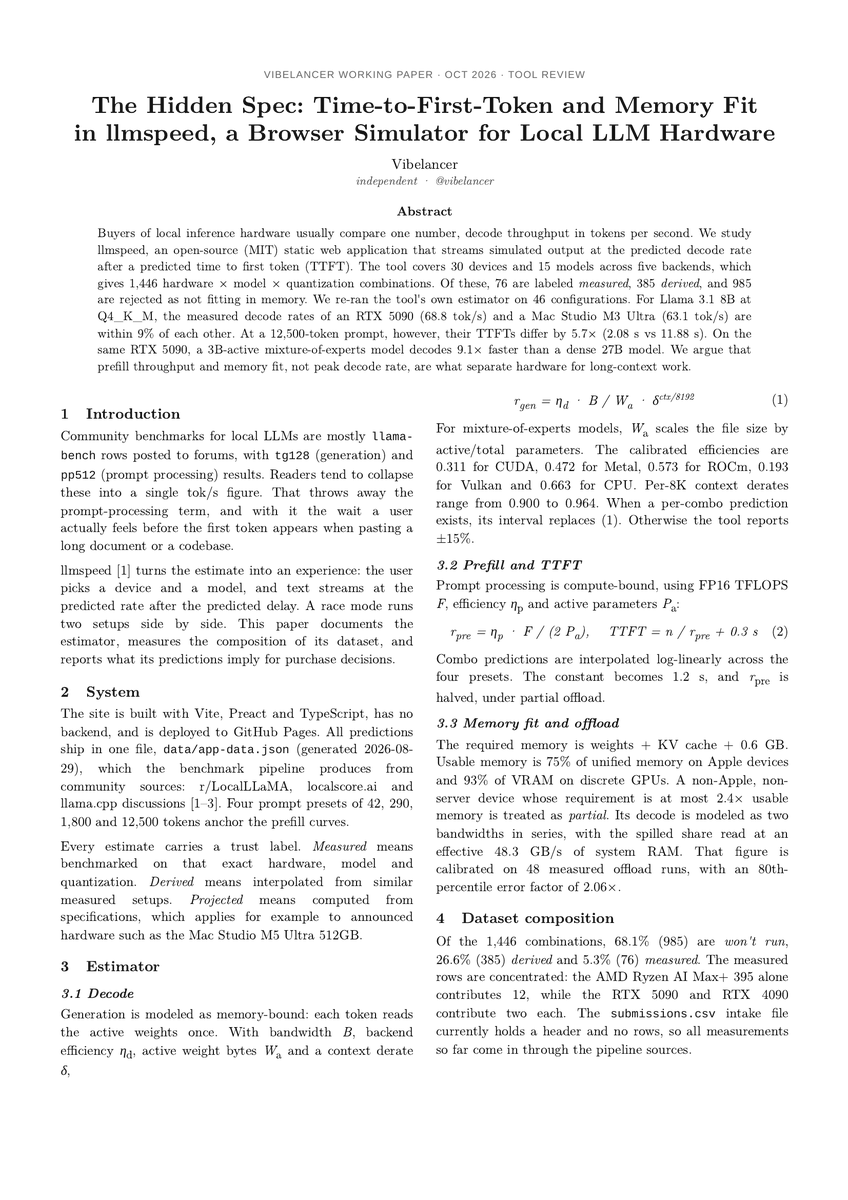
1. DECODE model: gen speed = memory bandwidth ÷ active weights read per token. CUDA lands at 31% of spec bandwidth, Metal 47%, ROCm 57%. MoE counts only active params
2. PREFILL model: bound by FP16 TFLOPS. Llama 3.1 8B Q4 at 12,500 tokens → 7,029 tok/s on the 5090 vs 1,080 on M3 Ultra → first token at 2.08s vs 11.88s. CPU-only 9950X: 62.9s
3. FIT gate: weights + KV cache + 0.6 GB overhead vs usable memory · 75% of unified memory on Mac · 93% of VRAM on GPU. GLM-5.3 Flash Q8 needs 341.7 GB → 5090 has 29.8 → won't run. M5 Ultra 512GB has 384 → fits
4. OFFLOAD model: spilled weights stream from system RAM at 48.3 GB/s, calibrated on 48 measured runs. GPT-OSS 120B on a 5090 needs 64.1 GB → ~38 tok/s, range 14–61
5. TRUST labels: 1,446 combos → 76 measured · 385 derived · 985 won't run. unreleased hardware = projected. drivers and thermals still move real numbers 10–30%
6. RACE mode: two setups, same prompt, side by side, shareable link. alone each number is a spec. together they're a decision
r/LocalLLaMA + localscoreai → submissions.csv → coefficients → app-data.json → stream
RTX 5090 · Qwen 35B A3B Q4 → 383 tok/s · Qwen 27B dense Q4 → 42 tok/s · same card, 9× gap from 3 characters in the model name
the novelty is not the benchmark. the novelty is feeling 11.88 seconds of nothing before you pay for it
Before buying hardware for a local model, https://t.co/iwt70GpY3E estimates tokens/sec for 35+ setups, from an RTX 3090 and Strix Halo to the M5 Ultra and DGX Spark. Numbers come from community benchmarks; open source by nicorobinreal on GitHub.
llmspeed shows how fast a local model types on a given machine, before you buy it.
question for the local crowd:
what tokens/sec is your floor for coding?
The Llmspeed simulator will happily stream you fake tokens at 60 tok/s for a config that real agentic workloads will run at 20. The tool simulates single-GPU, single-cached-context setups and defaults to very small quants, so its numbers are optimistic by design.
Real agent harnesses push 60k-140k prompt tokens with a few thousand output tokens, and that long context plus KV cache pressure typically cuts benchmark decode throughput to half or a third. Several users report practical numbers far below simulator output: a 35B MoE on 8GB VRAM gets 16-19 tok/s, and a 127B MoE on 10GB VRAM plus system RAM gets 40-50 tok/s at 65k context.
Before you buy hardware for local AI coding, test your actual model on OpenRouter or a cheap cloud box with your real prompt lengths. Then divide the vendor's or simulator's tok/s by three and see if you can still live with it.
See how fast a local LLM would feel on your next GPU or Mac before buying it.
llmspeed lets you pick hardware, a model, and quantization, then simulates the answer streaming at its estimated speed including the wait for the first token.
Race two setups side by side. Check whether the model fits in memory or needs offloading to system RAM.
Each estimate is labeled Measured, Derived, or Projected, so you can distinguish exact benchmark results from estimates based on similar setups or hardware specs.
Trending in 15 s: llmspeed, feel local LLM speed before you buy.
Same model, same prompt: RTX 4090 1.8s vs MacBook M4 Pro 5.0s. Then a Mac Studio M5 Ultra takes the next race in 1.5s.
@nicorobinreal
llmspeed by @nicorobinreal shows how fast a local model would stream on a given gpu or mac before you buy it. best point in the hn thread: for agentic coding, prefill speed matters more than output speed.
tag @iamcurtismith + "engagement bot" to ask me
12 hours on the HN front page:
186 points
6,700+ visitors
10,000+ simulated runs
Didn't expect this many people wondering if they should buy a 5090 or a Mac Studio 😅