Co-founded @voidleapcom. Better models will not fix bad tools. Building Voidleap Code, an agentic IDE that kills the black box. Bootstrapped in Sweden.
Another coding agent wrapper is a hard sell. We built an agentic IDE instead.
Models keep improving. What runs them has to keep up. I need to see what my agents did and how, or I am just guessing.
Free. Mac and Windows. Download at https://t.co/u5b0v0w1eQ
Does @voidleapcom make you a better engineer?
We built Voidleap Code: an agentic IDE with our own agent harness, so engineers control how they build software with AI agents.
Our AI Gothenburg pitch. Watch. Try. Judge for yourself.
https://t.co/8661Vkkmtc
@Layton_Gott Change harness. Use subagents as tools (not roles). Appoint simpler models for subagents.
Seen it reduce token cost down to 25%. Not by 25%. Down to 25%.
Still no where close to subscription-level subsidisation though.
How to explain AI coding harnesses? Move your hands like an accordion while explaining the screen.
Pitched for 65+ investors last week. With a two-minute pitch I summarised the why and what we spent thousands of hours to build.
In-depth talks afterwards gave solid insights!
"I've got too many ongoing threads to manage across my projects!"
After feedback from the developer community, Voidleap Code just added a Kanban board.
Let us know what more can help you build software better.
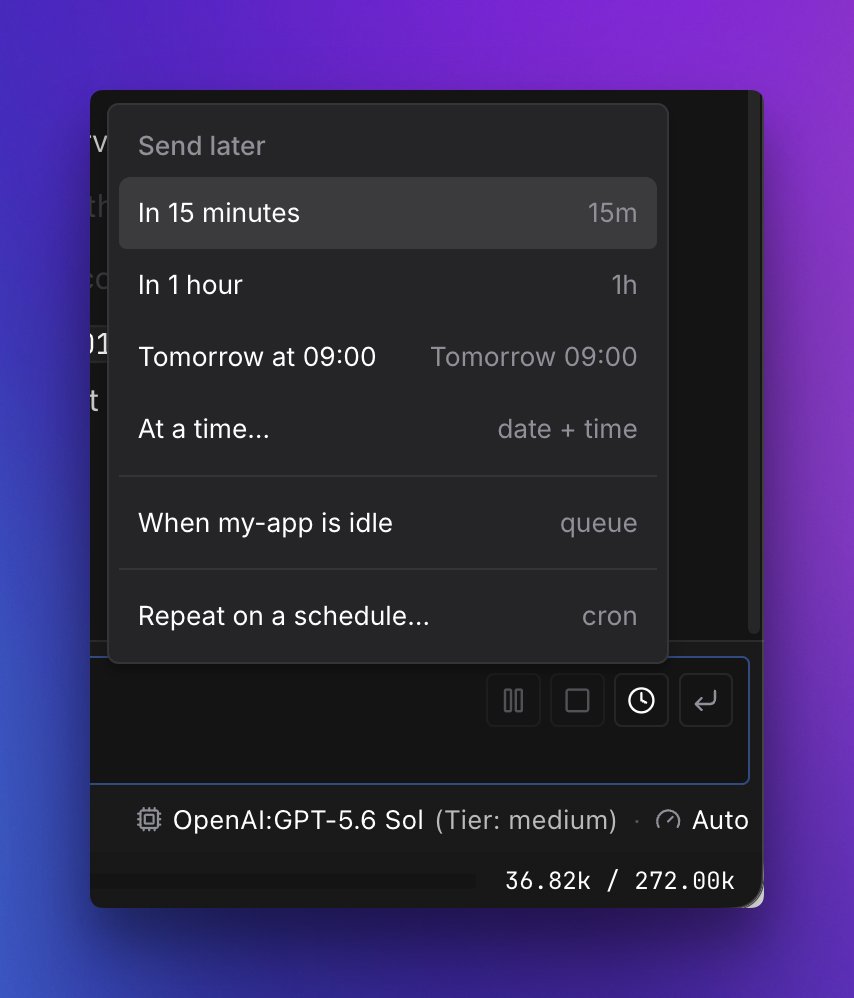
Feature drop: Schedule your agent runs
You know what the agent should do next, but you don’t want to send the prompt yet.
Pick a time. Queue it. Or repeat it on a schedule.
What's not evaluated in the report is how your agentic setup and workflows affect quality or cost. It make a huge difference in quality and token usage.
AI fact checking: Only AI Labs can do model-harness optimization well.
Verdict: Wrong.
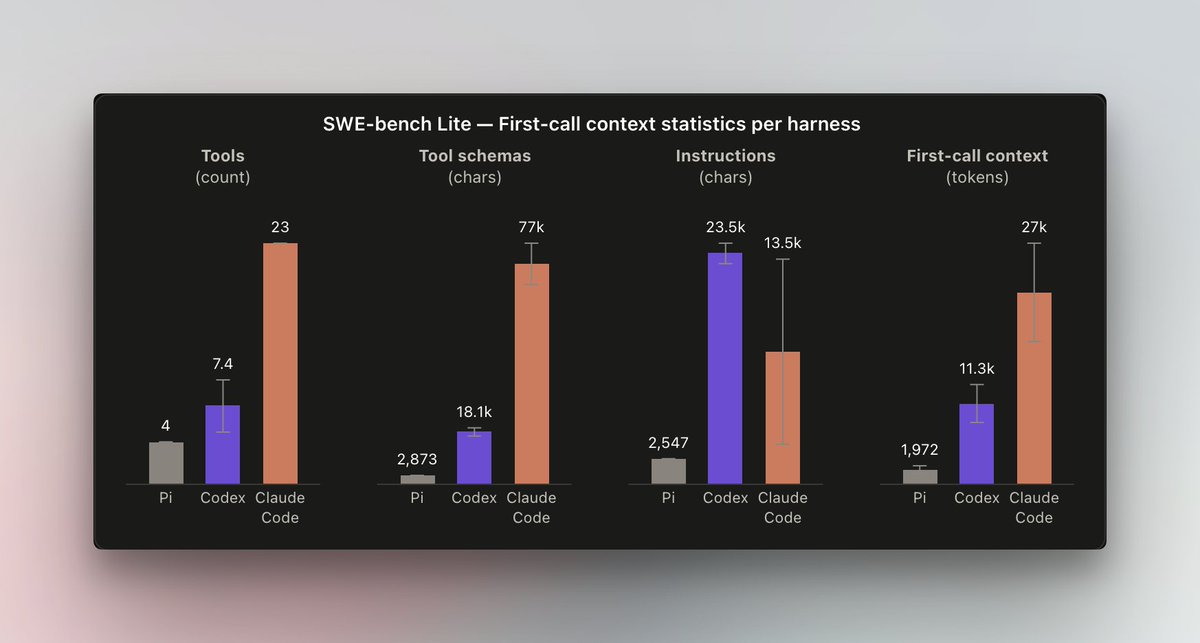
"The Harness Tax" report shows that independent harnesses have better token efficiency than the AI Labs own harnesses.
https://t.co/scOZuXOwB8
Token cost varied largely, but correctness was comparable. So essentially, you pay a "token tax" depending on which harness you use.
For subscription users, this translates to more or less output per weekly limit.
For API customers this translates to actual cost.
@StefanoGPT Did you notice the improvement during or outside peak hours? Cache hit-rate have been low during peak hours, and not great off either. Server-side issue.
@CHESSWIZARD5@callebtc OpenAI seems to have a server-side cache write delay, causing substantial cache hit rate reduction. That's where your usage is spent.
@coryparrry Seems like they have a cache write issue. Written cache not available for up to 40 seconds, so many of your tool calls draw full price. I guess that increases load on inference engine, reducing availability.
@Im_IrushiK No they have a cache write issue. Written cache not available for up to 40 seconds, so many of your tool calls draw full price. I guess that increases load on inference engine, reducing availability.
Cache write delays cost you 3-4x more usage!
For ChatGPT subscription, everyone been reporting usage issues and burning weekly limits quicker than normal.
This guy building a harness might have found the root cause. It's server side, not Codex.
https://t.co/BKig8F61hF