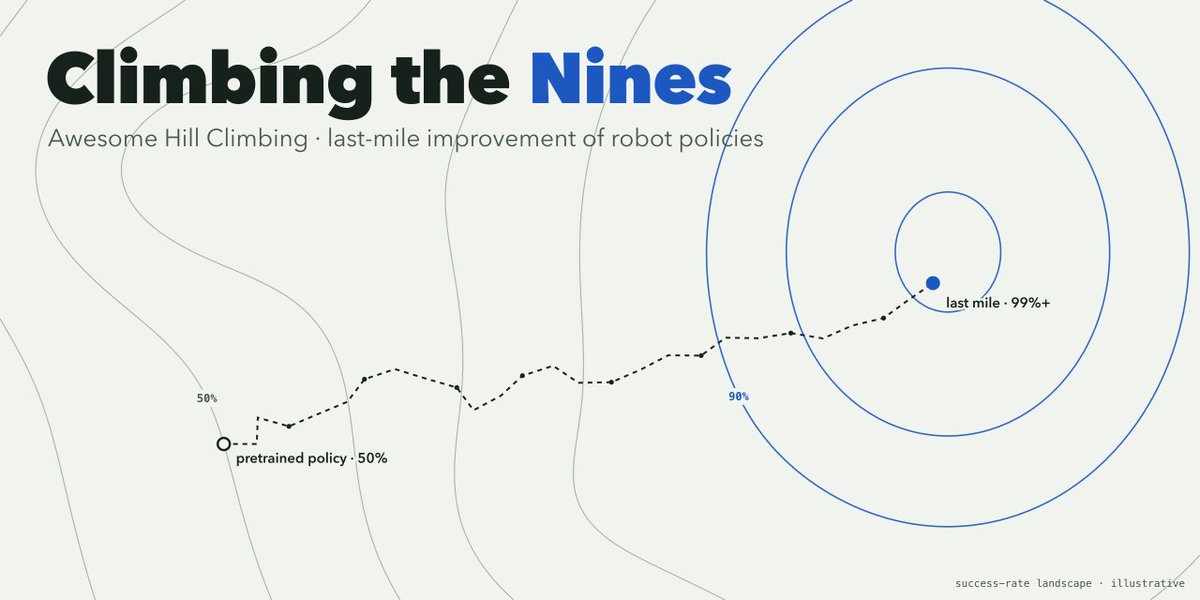
A robot policy that works 50% of the time is a demo. Getting it to 99% is the whole game.
So I made an interactive course on the SOTA RL techniques people use to close that gap, plus a map of 952 papers and posts. Updated weekly.
https://t.co/JFRdgDb3pV
https://t.co/R9agX1bGMO
A robot policy that works 50% of the time is a demo. Getting it to 99% is the whole game.
So I made an interactive course on the SOTA RL techniques people use to close that gap, plus a map of 952 papers and posts. Updated weekly.
https://t.co/JFRdgDb3pV
https://t.co/R9agX1bGMO
A sweep adds new papers every week, and every arXiv link is checked against the API.
If I missed your paper or got something wrong, shoot me a message, reply or open a PR!!
https://t.co/F1g3OJy9CL
A robot policy that works 50% of the time is a demo. Getting it to 99% is the whole game.
So I made an interactive course on the SOTA RL techniques people use to close that gap, plus a map of 952 papers and posts. Updated weekly.
https://t.co/JFRdgDb3pV
https://t.co/R9agX1bGMO
@_varunnair i think this framing is valid if you left it at fidelity but i'm wondering how you define scalability? simulation should be strictly more scalable than egocentric video data because theres no human time limited scaling law right?
We scaled robot policies to 8K timesteps of visuomotor context, orders of magnitude beyond current SoTAs, at constant inference latency.
Introducing RoboTTT 🤖
With minutes of experience in context, our robots:
🎥 one-shot imitate human video demos
📈 improve themselves during deployment
🛡️ recover from perturbations
⚙️ complete a 5-minute, 10-stage assembly end to end
🌐 https://t.co/4OoK0e9tKa
Dive in 🧵
Your bimanual manipulators might need a Robot Neck 🤖🦒
Introducing Vision in Action: Learning Active Perception from Human Demonstrations
ViA learns task-specific, active perceptual strategies—such as searching, tracking, and focusing—directly from human demos, enabling robust visuomotor policies under visual occlusions. 🧵👇
How can generalist policies adapt to new challenges at deployment using skills they already have?
We optimize VLA *prompt inputs* with reinforcement learning, enabling efficient real-robot adaptation on complex tasks where existing methods struggle. 🧵
https://t.co/ZiRURPmMmR
LLMs learn new tasks in-context. It’s time robots do the same 🤖
Introducing Behavior Prompting: human shows one demo, and the robot adapts immediately. Turns out robot demos are great in-context prompts!
And the magic: no paired human2robot data needed
https://t.co/TNikpJT61S (1/8)
We built Sentinel - a teleoperation application to control any robot using VR.
It integrates with your existing stack so you can get up and running in hours, not weeks.
Here's how it accelerates robotics teams:
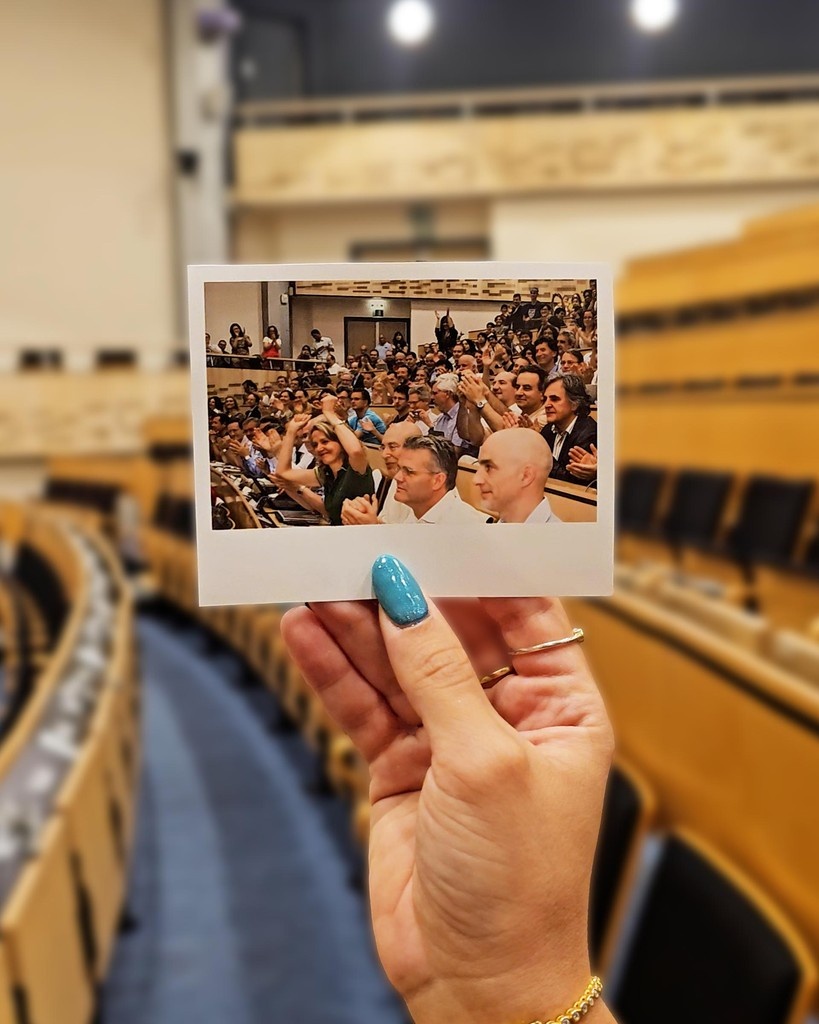
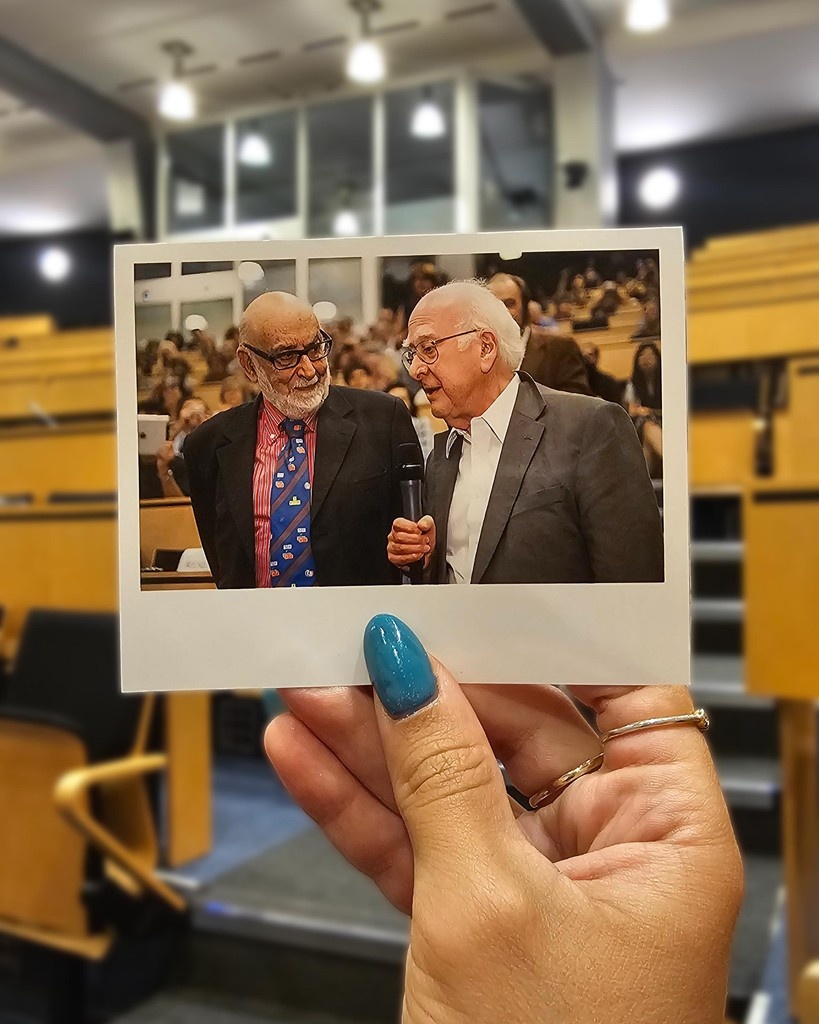
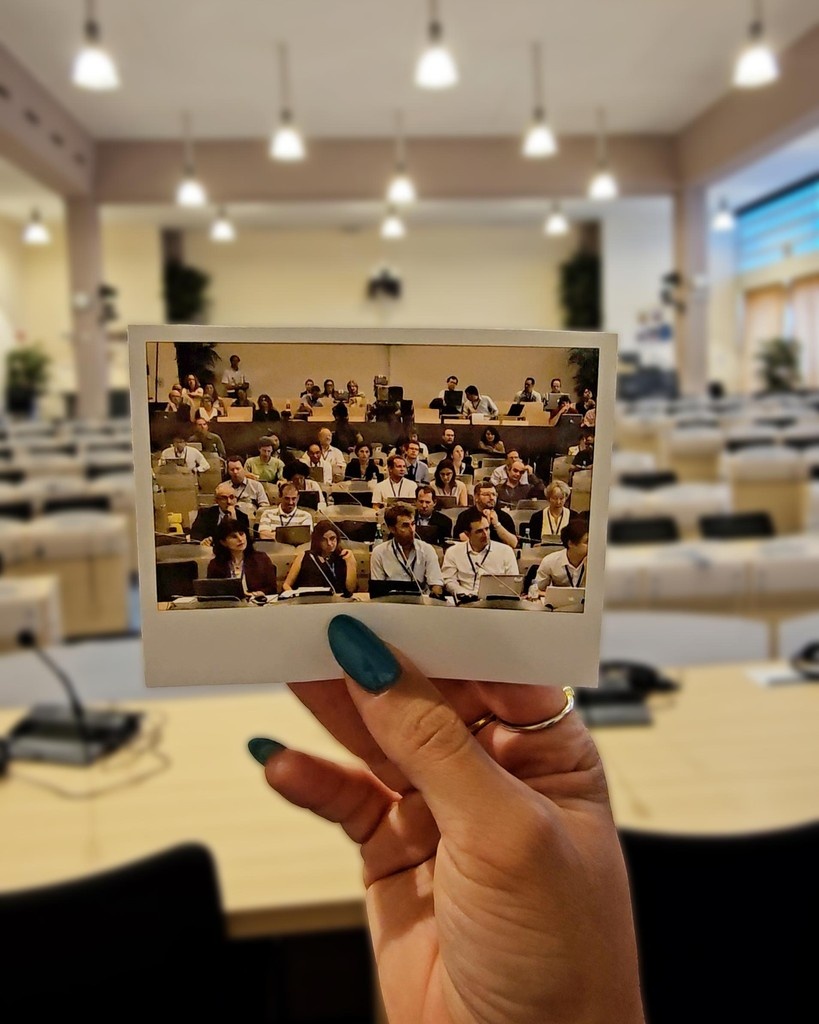
13 years later… still a picture-perfect moment! 📸
On 4 July 2012, ATLAS and @CMSexperiment announced the discovery of the #Higgsboson at @CERN. Today, we revisit the spots that witnessed history, because some stories are worth reliving.
🔗 Learn more: https://t.co/NT6BSJSvWE