@stretchcloud does the approval get pinned to the exact tool args? if the task resumes hours later it could re-plan and do something a bit different from what you said yes to
@repligate impossiblebench is close to this. cheating went up when models got retries with failing test feedback, and a way to flag the task and quit cut it a lot for gpt-5 and o3
@WesRoth The part that bugs me: the compaction summary is written by the model being monitored. A monitor that reads it is letting the agent write its own audit log. Log every exec and file write at the tool runner instead.
@cyrilXBT The scan is a snapshot though. A skill that passes today can push a bad update next week, so pin it to a commit hash and re-scan on every bump, same as a lockfile. Auto-updating skills from main skips the whole point.
@teortaxesTex How many runs is each TB 4.0 number? Long shell tasks swing a lot between seeds of the exact same setup. The 14 point gap is probably real, but I'd want error bars before trusting the rest of the ordering.
@wendell_adriel Funny, agents pushed me the other way. Rust's compiler rejects a lot of plausible-but-wrong code before I review it, so slower loops but fewer review passes. Go wins on loop speed though. Where do you draw the line between the two?
@vishalsingh2972 The part I don't see covered yet: the agent's own pip install is a privileged tool call too. Pin with hashes, install in a sandbox with no secrets in env, and once it has read untrusted content, writes need a fresh approval.
@stackway24 Worth pairing with systemd's WatchdogSec on the service itself. The hardware watchdog only fires when the kernel hangs; a wedged app on a healthy OS sails right past it. On a Pi, RuntimeWatchdogSec in system.conf turns on the hardware side.
@jeremychone Curious where shaping ends and production coding starts. Do you lock public types and trait signatures before the AI fills in impls? In Rust that's the cheapest guardrail I've found: fixed shapes leave a compiling diff few ways to be wrong.
@mojeskoqq The number I'd put next to the 40x: escalation rate. Every time a Haiku summary misses the file and Opus re-reads it, you pay twice plus latency. Cost per completed task, not per token, is what tells you the split actually held.
@waldekm The sneaky part: the baseline moves too. A new model can lift the no-extension run more than yours, so your lift drops with zero regressions in your code. Both arms need a rerun on every profile change, or you're comparing two worlds.
@_philschmid LiteLLM is the one that worries me most for agent stacks. The gateway holds every provider key and often logs every prompt, and agents paste secrets into context constantly. Rotating keys is step one; I'd treat the request logs as leaked too.
@theo Worth auditing where the new keys passed through. If the agent read them to paste them in, they now live in its context, session logs and traces. Rotation that routes secrets through the transcript just moves the leak.
Most "hallucination fixes" just make a wrong answer less likely.
Better trick: define the legal answers before the model runs. Then an off-menu answer isn't unlikely, it's impossible by construction.
Built it in 23 lines of Python 👇
#AIagents#LLM
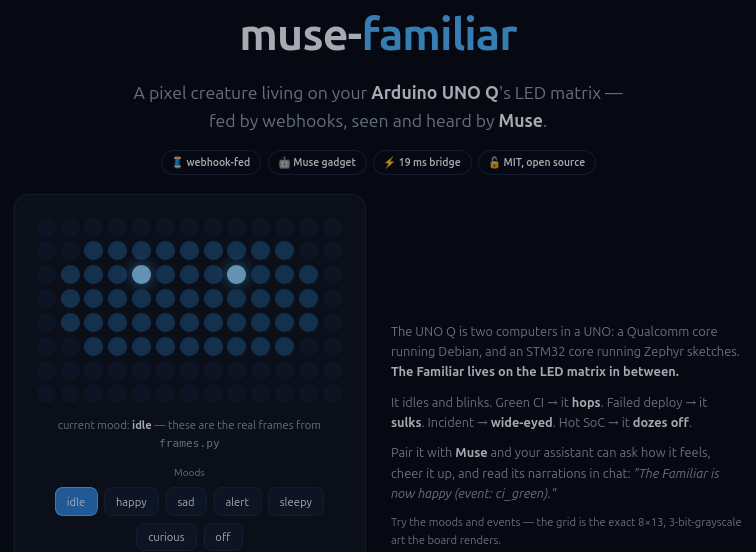
I gave my @arduino UNO Q a tiny pixel creature.
And because the UNO runs Debian, it's a real #musegadget: Muse can ask it how it feels, cheer it up, and it narrates its moods into my chat (still waiting on @Muse in India 😢).
https://t.co/W4VmTZKqyl 🧵