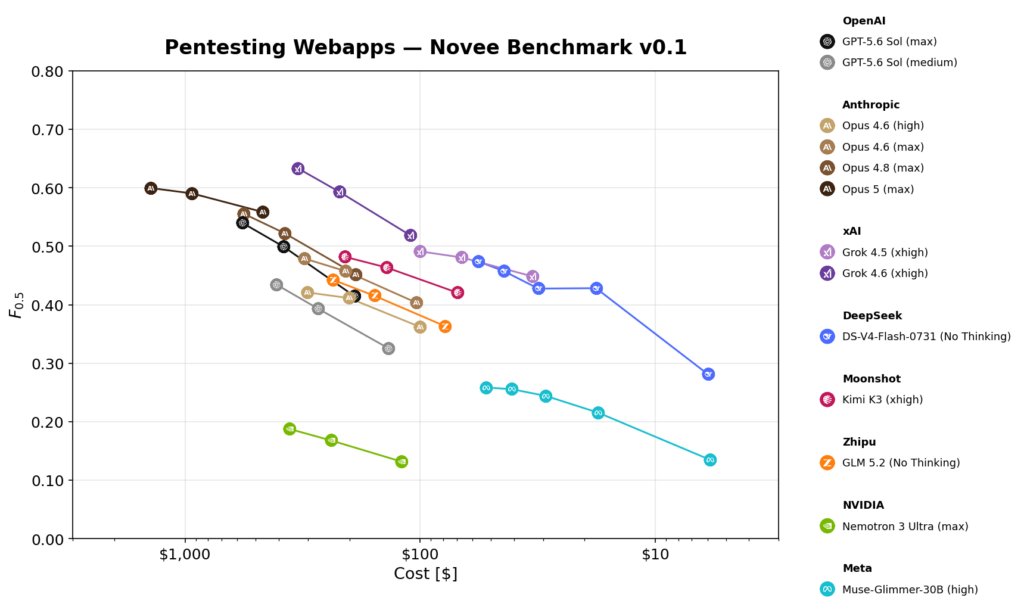
We put PWNBench on @FireworksAI_HQ Specialized Intelligence Index, alongside Harvey (legal) and Doximity (healthcare), so model builders and security teams can compare models on live offensive work.
See the results: https://t.co/2ZEQwlrqw1
Full method: https://t.co/e3Bs01wn75
Most AI benchmarks score bounded, static tasks. That doesn’t match up with offensive security ops. We should be asking, can the model break into a live system it’s never seen and prove what’s exploitable?
We built a benchmark that measures it the right way: PWNBench.
PWNBench is built on live web applications with verified, ground-truth vulnerabilities. Agents have to explore noisy targets, decide where to focus, and prove real risk. Then we score recall, precision, and cost.
It’s not a CTF puzzle, it’s not a bug bounty competition.