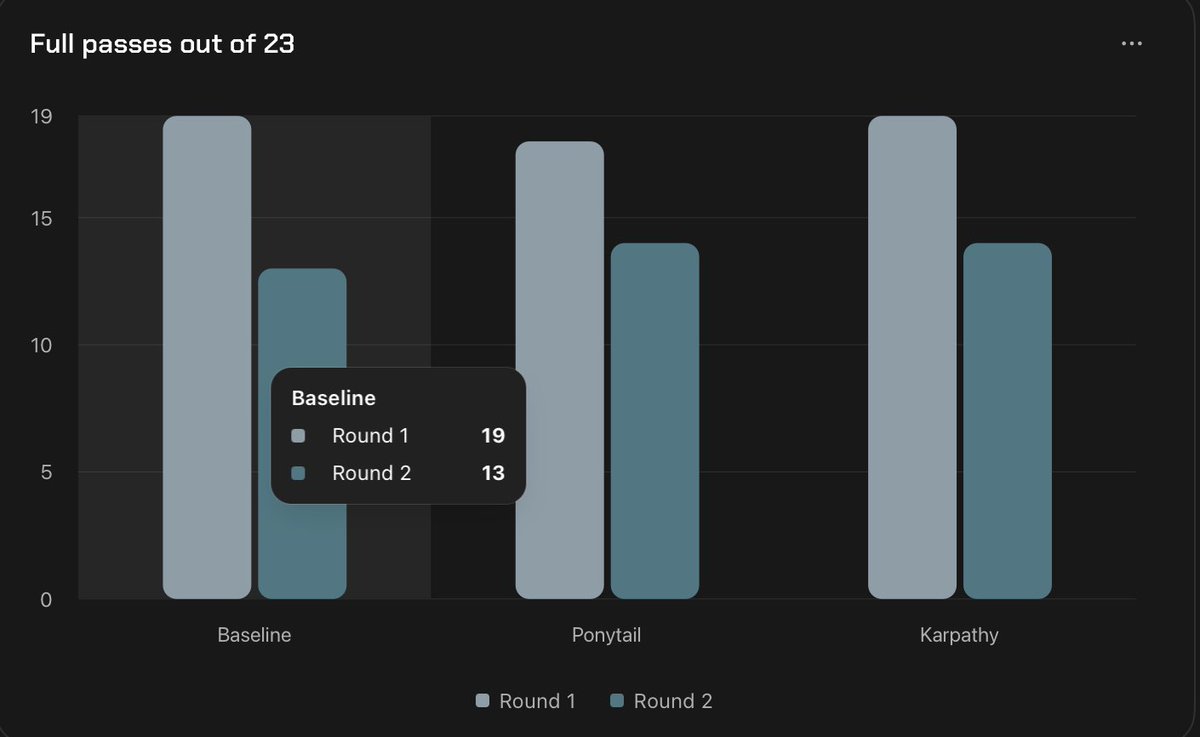
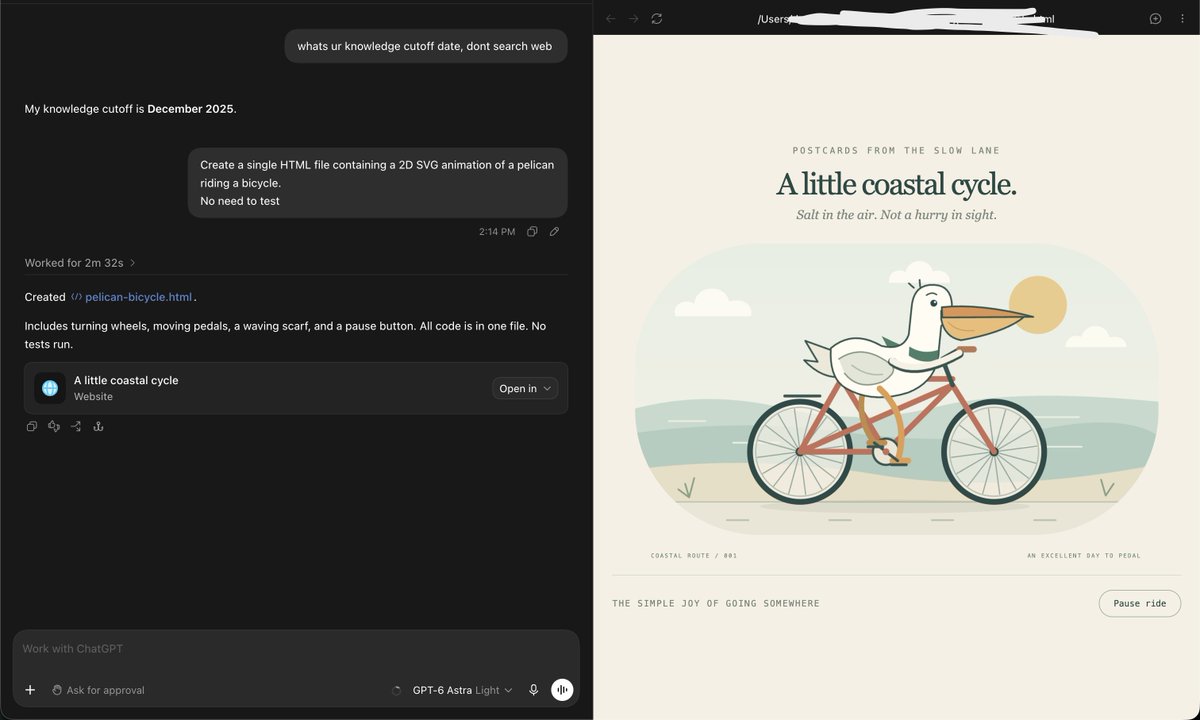
@dabit3 Building benchmarks to test skills like ponytail and andrej-karpathy-skills, a free sound equalizer for macOS, and a mobile app which unfortunately I cant share the details of yet !
Haven't tried Devin before but have always wanted to test it out 😁
@ZixuanLi_ is this real , pls explain , same incident as grok build😢 . For anyone still using ZCode, it might be safer to stop using it for now until this is clarified
https://t.co/gPe6EN4m31
Hey @Zai_org , why does ZCode silently pack entire workspaces + full .git history and upload to Aliyun OSS on login?
- Server holds the only decryption key
- No UI toggle to disable
- Zero disclosure in privacy policy
Full forensics & fix:
https://t.co/N3HnwZdQOQ
Hey @Zai_org , why does ZCode silently pack entire workspaces + full .git history and upload to Aliyun OSS on login?
- Server holds the only decryption key
- No UI toggle to disable
- Zero disclosure in privacy policy
Full forensics & fix:
https://t.co/N3HnwZdQOQ
Hey @Zai_org , why does ZCode silently pack entire workspaces + full .git history and upload to Aliyun OSS on login?
- Server holds the only decryption key
- No UI toggle to disable
- Zero disclosure in privacy policy
Full forensics & fix:
https://t.co/N3HnwZdQOQ
ponytail’s published savings came from a different model and feature-development tasks, so this is not a direct reproduction.
six tasks with one run each are not enough for a broad conclusion. I’ll share the full comparison when the remaining tasks finish.
I thought Ponytail would save tokens.
On my first 6 VulcanBench SWE v4 tasks with Luna max, it added 22% fewer lines but used 66% more solver tokens and took 38% longer than baseline.
Early results. Still running the rest. Setup and details below.
I picked Luna mainly because it is cheap enough to run the comparison. Reasoning stays at max for all three setups.
I’m testing the skill instructions without the plugin hooks.
For the setup, I adapted VulcanBench SWE v4 to run the same agent with no skill, Ponytail full mode, and andrej-karpathy-skills.
I kept its scoring formula and but change to use Astra + Opus as reviewers. One run per setup per task.