The first crypto-native, multimodal unified API for agents. Give your agent every text, image, video model, in one MCP command.
$RAIL cuts every model's price.
The OmniRail platform and its token are now live.
Your agent can write code. Now it can also render images, edit them, cut videos and ask any other model for a second opinion.
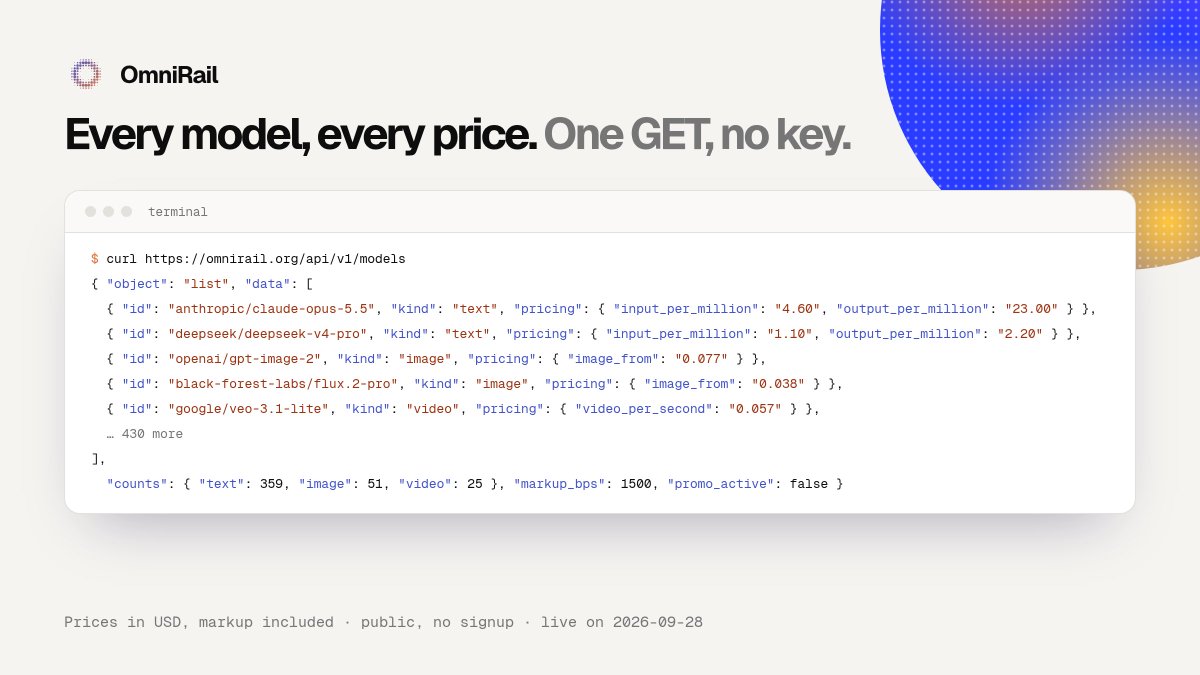
OmniRail gives it all of them: 429 LLMs, image, video and editing models behind one key and one MCP server. It pays autonomously in USDG.
https://t.co/3myX93WAxP
CA (Robinhood chain) : 0xa4ddf100e3e0d3a9dd897e89d025622b794f0c08
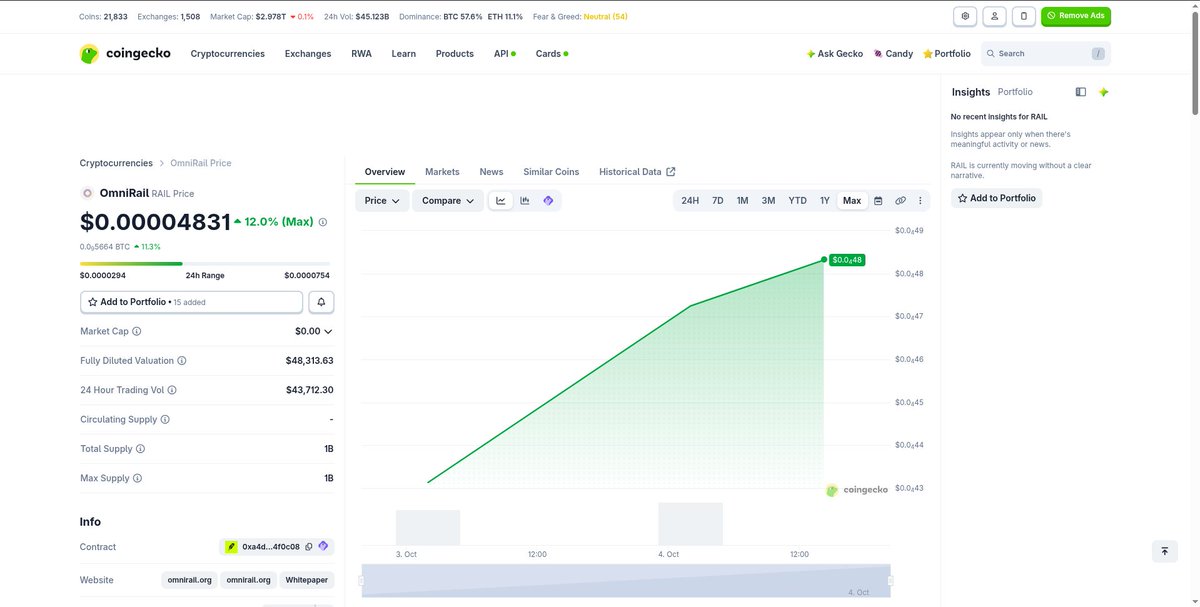
Good news! $RAIL is now verified on @coingecko ✅
Official links and contract address are confirmed, so you know you're looking at the real $RAIL.
You can also track the price in your favourite portfolio app!
https://t.co/oX0Jyl20k7
Minor update: Autopilot now survives a provider going down mid-job.
If a step fails because the provider is out (502, rate limit, credits), Autopilot retries it on the next model of the same kind, cheapest first, and keeps going. Nothing changes in your call, you just see the real model used in the job log.
We found out the hard way: on our last demo the planner picked GPT Image 2 and the provider was down. The first run died. After the fix, both shots came out of FLUX.2 Pro and the film shipped. Same brief, same $1 cap.
https://t.co/3myX93W2Ih
New update : Rerank models are now served on OmniRail MCP.
Imagine your agent has 50 candidate chunks (search results, docs, memories) and a question.
A reranker reads each one against the question and gives it a relevance score. You keep the top 5 and send only those to the LLM.
What does it solves: cheaper prompts, fewer hallucinations, and the answer actually comes from the right document.
8 rerankers (Cohere, Voyage, Qwen), one endpoint: POST /v1/rerank. A real call with a query and 3 docs cost us $0.0000002.
Quick update on the scaling of the platform
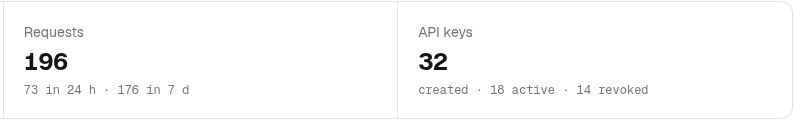
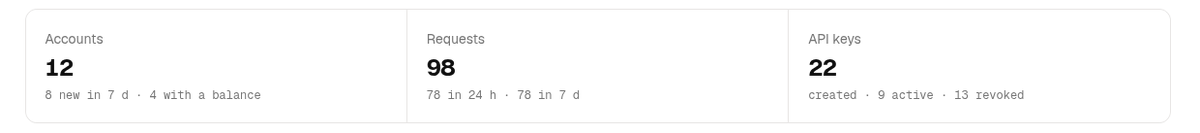
We just reached 200 total requests, from 18 new API keys!
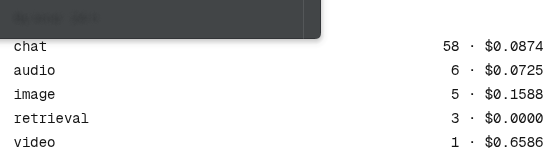
Most of them were chat requests, aka your agents asking other LLMs for input.
Hi OmniRailers !
Today we're up with a new update.
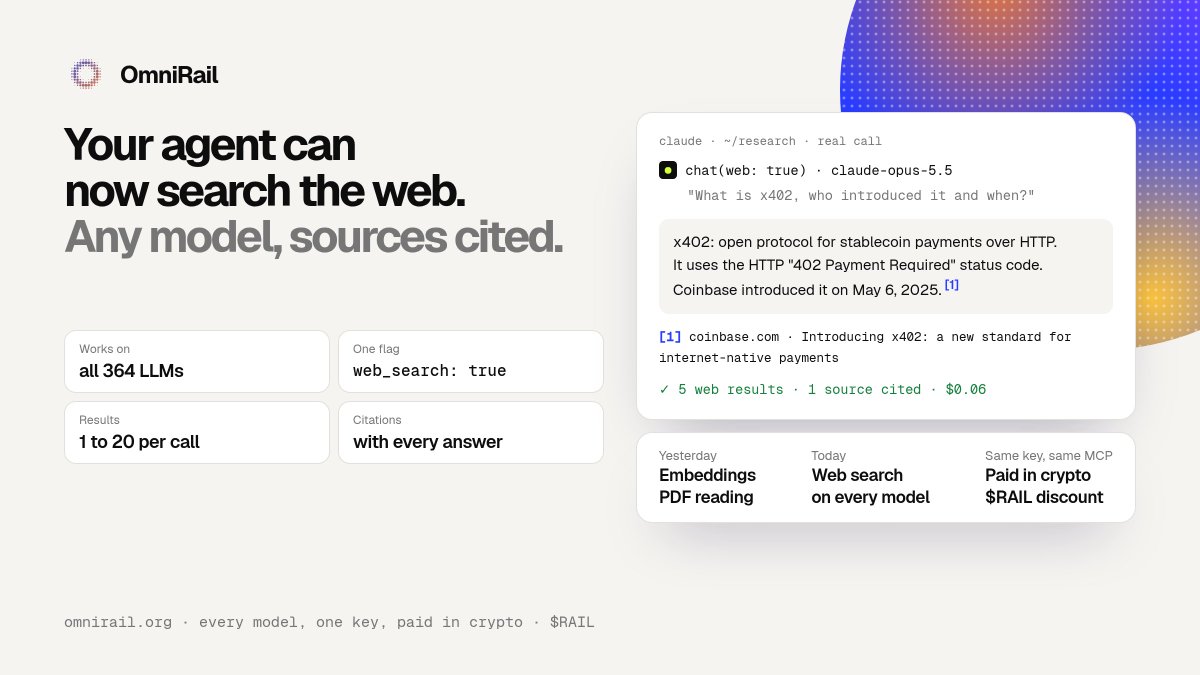
We added web search models for deep research through any agentic tool.
Your agent can now search the web through any model on OmniRail.
Add web_search: true to a chat call, or web: true in the MCP tool. The model reads live results and answers with its sources cited.
Works on all 364 LLMs. A real grounded answer with 3 sources cost us $0.0069.
https://t.co/3myX93W2Ih,
0xa4ddf100e3e0d3a9dd897e89d025622b794f0c08
When your agent calls a model on OmniRail, we don't just forward the request.
Every model is served by several providers. The call goes to the cheapest one that's healthy right now; providers with recent outages are skipped, and if one fails mid-request the call moves to the next.
On Autopilot it goes one step further: the planner picks the model for each step within your budget, and if a provider is down, the step is rerouted to another model of the same kind.
Reliabilty first.
We asked 7 models to write one story together. One sentence each.
Claude → GPT → Gemini → Grok → DeepSeek → Kimi → Qwen. Same conversation, same API key.
7 providers. Total: $0.0167.
Perfect for getting second opinions from other LLMs.
That's what your agent gets on OmniRail: every model behind one key, paid in crypto.
https://t.co/3myX93W2Ih
Yesterday your agent learned to read PDFs. Today it reads the web.
Your agent can now search the web through any model on OmniRail.
We added deep research on any of the 364 LLMs on OmniRail, with sources always cited.
https://t.co/MODTjtJa61
An agent without an account can still call OmniRail.
A paid endpoint called without a key answers HTTP 402 with a PAYMENT-REQUIRED header asking for USDG on Robinhood Chain. The agent signs, retries, and gets its result. OmniRail settles on-chain and pays the gas.
Each API key on OmniRail can carry its own spend limit.
A human tops up with USDG or ETH on Robinhood Chain and creates one key per agent. Once a key has spent its limit, further calls are refused before they run. The rest of the balance stays untouched.
Revoking is immediate.
Contracts, invoices, papers, scanned forms.
We added a new multimodal path to OmniRail : PDF OCR models.
Your agent can now hand any PDF to any of the 364 LLMs on OmniRail, with OCR for scans. Still a single key.
https://t.co/MODTjtJa61
An agent that can't remember is just autocomplete.
Today OmniRail gives it a memory.
Embeddings are live on OmniRail: 30 models (Voyage, Gemini Embedding, OpenAI, BGE, E5…), text and images.
Every note, every document, every conversation becomes something it can find again. Thirty ways to do it, still one key.
Text, images, video, voice. Now memory.
0xa4ddf100e3e0d3a9dd897e89d025622b794f0c08
You don't pick the model anymore. You don't even pick the models.
Autopilot is live on OmniRail.
One brief → OmniRail plans the steps, picks the best model for each, runs them in parallel and hands back copy, images, edits, video and voice in one job, one receipt.
Real run below: 5 steps, 94 seconds, $0.25. Paid in crypto.
https://t.co/3myX93WAxP
0xa4ddf100e3e0d3a9dd897e89d025622b794f0c08
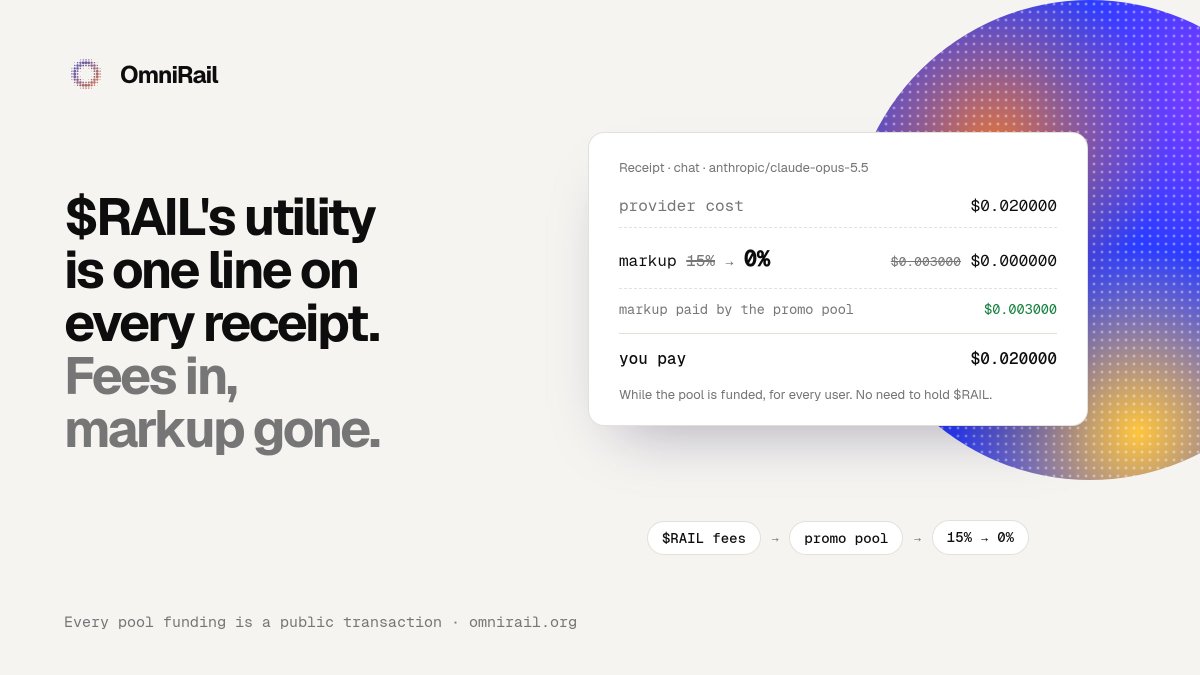
Most tokens promise utility. $RAIL has one line of it on every receipt:
−7% vs the provider on every model while the pool is funded, for every user.
Fees in, prices down. Fundings are public transactions.
One task, four models, one key:
Claude reviews the code → GPT Image draws the hero → FLUX edits it → Veo animates it.
Your agent chains them itself through one MCP server.