🎉 We’re excited to announce the ACL 2026 Student Research Workshop (SRW) website is live!
🌐 https://t.co/AOjgbMV6MC
brings together students across NLP to present research, receive mentorship, and engage with the global research community.
🧵 Key details ⬇️
#ACL2026#NLProc
We are happy to announce the second release of HPLT bilingual datasets:
- 50 English-centric language pairs = 380M parallel sentences (HPLT) 🤩
- 1,275 non-English-centric language pairs = 16.7B parallel sentences (MultiHPLT) 😮
Available at the HPLT dataset catalogue and OPUS.
The 18th MT marathon will be organized in beautiful Helsinki in the end of August, 2025. We invite you to a week-long gathering of researchers, developers and students with lectures, labs and hacking projects. More information will come - stay tuned!
This week I won't be able to present in person at #WMT#EMNLP, so here's our poster on our participation to the Shared Task on Translation into Low-resource Languages of Spain organized by @transducens We produce fast models that translate Flores+ in 4 seconds and can run on CPU!
🚀 Excited to introduce EMMA-500! 🌍✨
A multilingual model continue-trained on 546 languages, enhancing coverage for low-resource languages. With the MaLA corpus and Llama 2 7B, we're pushing boundaries in cross-lingual transfer. Check it out: https://t.co/FBSbuy3qft
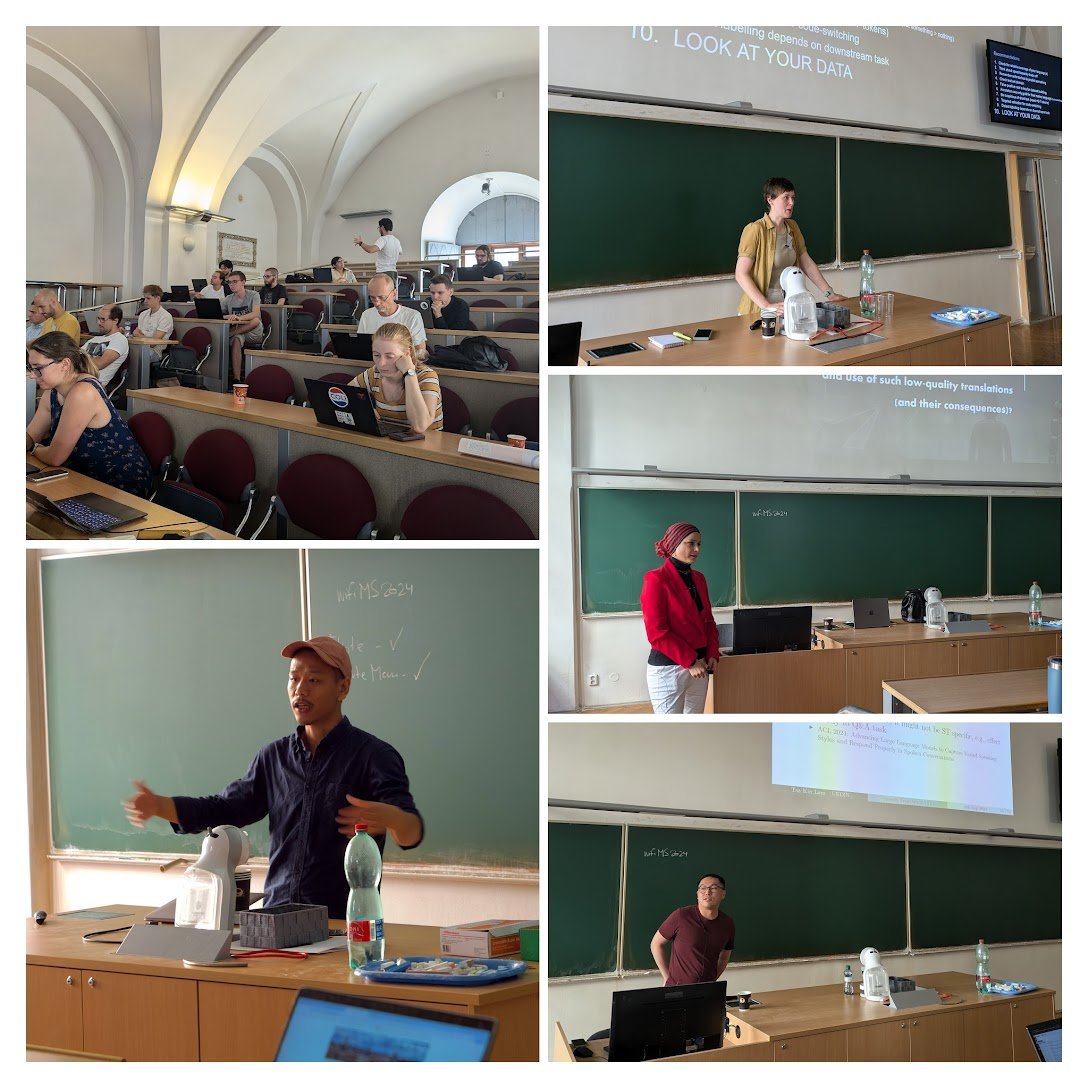
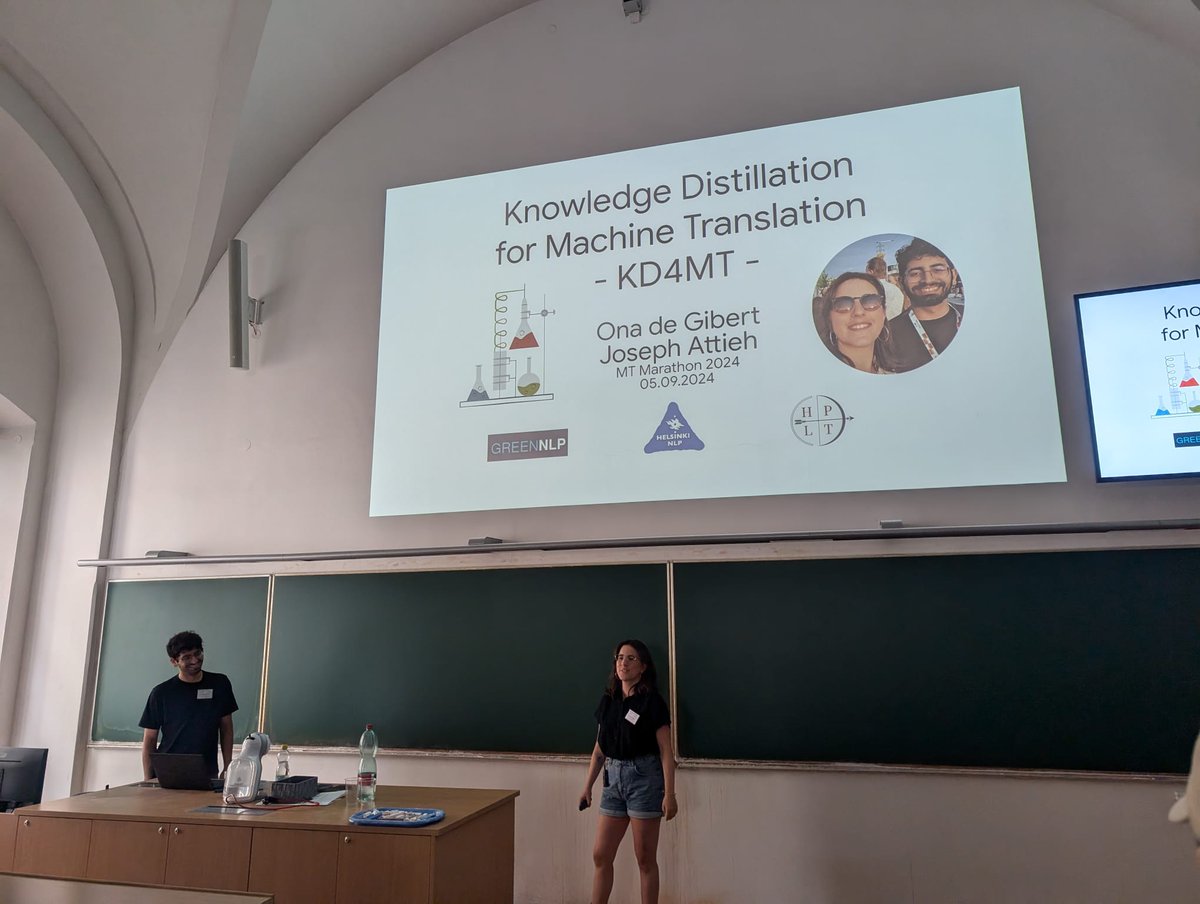
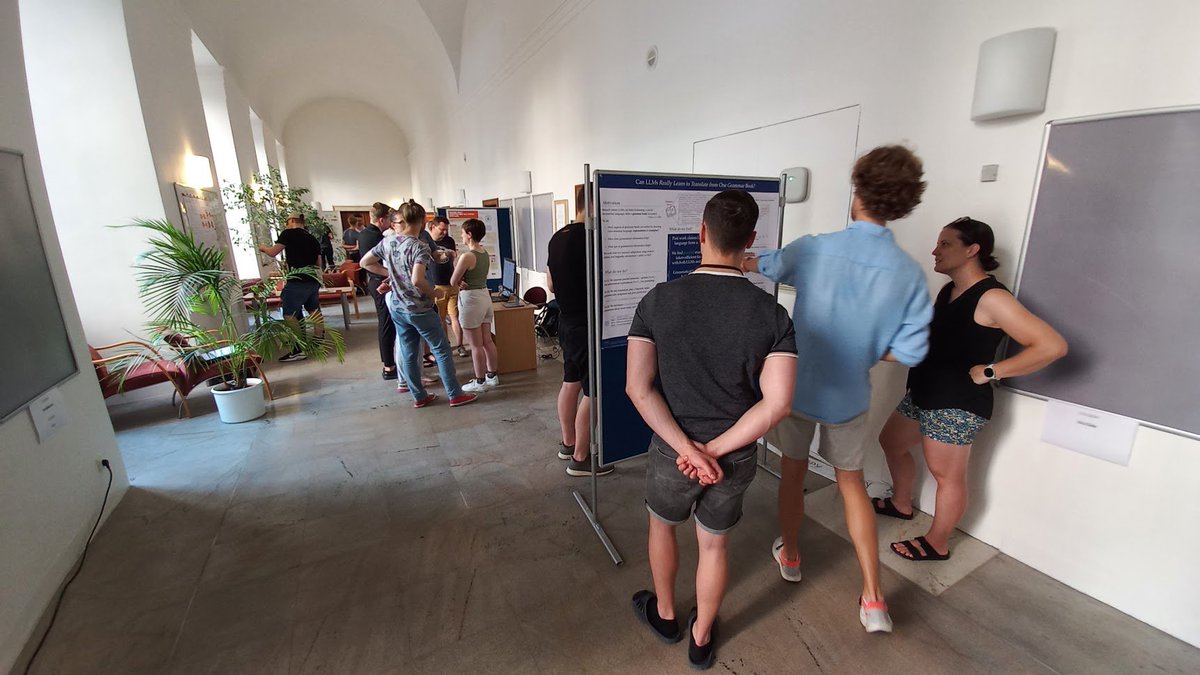
The MT Marathon continues on its third day! We already had great talks by @OndrejBojar, @prajdabre1, @zouharvi, and @esalesk 👏 and a poster session with 10 posters 🖼️. Today, we continue with more talks, and of course, the week-long hackathon continues with interesting projects.
Last call for participation! MT Marathon 🏃🏃♂️🏃♀️ starts in less than a week. 🤩 If you plan to attend, please do not forget to register https://t.co/e3xtkRg28Y
Did you miss the presentation? No worries, you can check out our video here: https://t.co/SWsd3z3gSr
A New Massive Multilingual Dataset for High-Performance Language Technologies @ LREC-COLING 2024
@LrecColing has arrived! We will presenting our work on how we built the HPLT datasets!
📅 Friday 24th of May
⏰ 9.20h-9.40h
📍Room Londra
⌛️Session D3-S1-R3 - Multilinguality, Machine Translation, and Translation Aids II
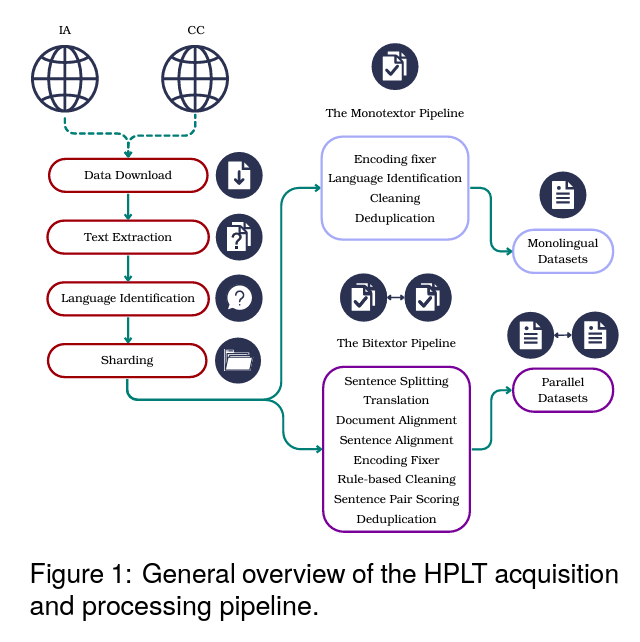
We will be presenting the HPLT datasets HOW-TO and insights at @LrecColing in Torino. Paper already in https://t.co/JiXooVNzvz: https://t.co/iPlRX7Cfj5.
Still recovering from the excitement of #lreccoling2024, where we presented the @hplt_eu resources! We introduce:
- monoHPLT: monolingual collection covering 75 languages
- biHPLT: parallel data for 18 language pairs
- multiHPLT: synthetic data obtained through pivoting
Nothing says Italy like 𝐺𝑒𝑙𝑎𝑡𝑜! Spending the week in beautiful Torino for @LrecColing#LRECCOLING2024#lreccoling Can't wait to listen to great research, reunite with old friends and make new ones!
Will you be at @LrecColing next week? HPLT will! 🥳
Don't miss:
- our poster on Thursday 23, 15:30, about FastSpell, one of the langID technologies of our dataset pipeline. (paper 1571)
- our presentation on Friday 24, 9:20 for all details about HPLT massive dataset (paper 2199)
🚀 Attention MT scientists and developers! We announce the #WMT2024 shared task on machine translation into these underrepresented Romance languages of Spain: Aragonese, Aranese, and Asturian. Joint effort @UA_Universidad+@UOCuniversidad. Details here:
https://t.co/PrCfGJwEHR
☑️ Gràcies a l'esforç comunitari, la Viquipèdia en català ja ha arribat a 40.000 articles sobre dones!
La biografia que ha culminat aquesta fita és la de Miriam Tey.
Ara mateix, el 21% de biografies de l'enciclopèdia són sobre dones. El 0,22% són sobre persones no binàries. 📈