OpenScale is the cheapest way to run open-source models.
We're starting with DeepSeek V4.1 Flash at $3 per billion cached tokens ($0.003 per 1M). You read that right: billion, not million.
It's our first step toward intelligence too cheap to meter.
GLM 5.3 Flash is live on OpenScale.
Cheapest anywhere: $0.12 in, $0.024 cached, $0.40 out per 1M tokens, 20% below https://t.co/RKqlrfXNe3's own API.
Frontier-level coding and agent performance, 20x cheaper than Claude Opus 5.5.
DeepSeek V4.1 Flash-1017 just dropped.
The cheapest, fastest place to run it is OpenScale.
Smarter: 36% higher on Terminal-Bench 4.0
Faster: 200+ tok/s, 16% fewer reasoning tokens
Cheapest: $0.06 in, $0.003 cached, $0.24 out per 1M
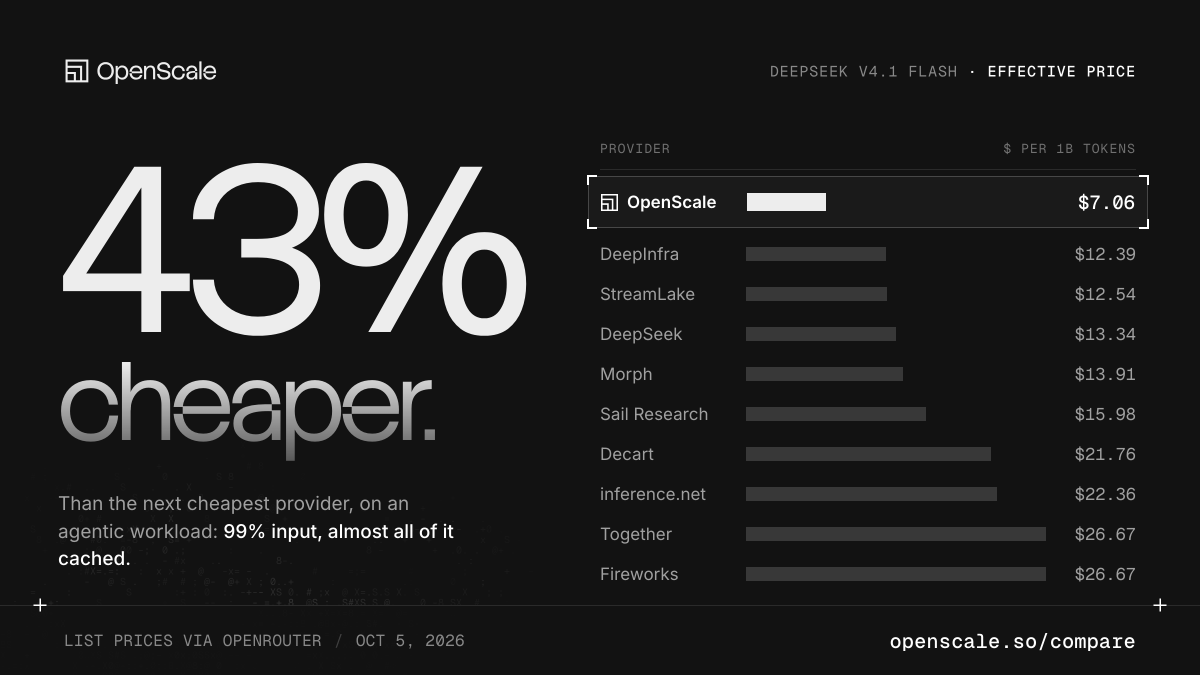
Agentic workloads are ~99% input tokens, and almost all of that can be cached.
On that mix, OpenScale has by far the lowest effective rate for DeepSeek V4.1 Flash anywhere: about $7 per billion tokens, 43% cheaper than the next provider.
OpenScale is the cheapest way to run open-source models.
We're starting with DeepSeek V4.1 Flash at $3 per billion cached tokens ($0.003 per 1M). You read that right: billion, not million.
It's our first step toward intelligence too cheap to meter.