🚀 We're releasing our 3-bit quantization of Qwen3.8-27B: 5.3× smaller (10.17 GB vs. 53.79 GB) while retaining ~95.4% of base quality.
Matches or beats other low-bit builds in our evals, and runs on a single RTX 5090 at ~90 tok/s with the standard llama.cpp runtime!
Open-sourced under the Apache 2.0 license 👇
https://t.co/af49fQxNEr
This is just v1. More evals and even more capable versions are coming very soon, plus a blog post with the full details.
Stay tuned! 👀
#AI #LLM #Quantization #OpenSource
How we got there, in short: mixed-precision bit allocation combined with efficient Quantization-Aware Training (QAT).
ORA-Q2 is currently available only to Ora Computing customers, and full technical details are coming soon.
If you're interested in running capable models on much smaller hardware, get in touch.
Extreme quantization can look great on benchmarks. Long reasoning is where it starts to bite.
Bonsai 2 27B from @PrismML squeezes Qwen3.8-27B down to just 5.9 GB and posts impressive results on many benchmarks.
But when we gave it the classic "pagoda challenge", generating a single HTML file that renders a voxel pagoda garden, it fell short. The task sounds simple, but the model has to place every voxel and set up the renderer itself, in one shot, which takes long chains of reasoning.
Our Qwen3.8-27B-ORA-Q2 makes a different trade-off. At 10.2 GB, with nearly twice the bits per weight of Bonsai, it holds up against the BF16 baseline while still being 5x smaller. Those extra 4.3 GB are what make the difference on long-reasoning tasks like this one.
Note: the comparison replays real recorded streams at 20x speed. Since outputs are stochastic (temperature = 1), the output lengths vary between the tests, so the token-throughput gain isn't the same as the percentage of time saved.
Existing speculative decoding methods boost inference by around 5.5x. At Ora Computing, we push this even further to 6.5x 🚀
Below is a sneak peek of STDraft: our new algorithm for speculative decoding that builds on top of @inco_ai#DFlash 2.
We compared native MTP, DFlash 2, and STDraft on the original Qwen3.8-27B deployed on a single RTX PRO 6000. The result: across math, code, and plain text, the aggregated throughput is dramatically different:
-Native MTP: 65.0 tokens/s
-DFlash 2: 87.9 tokens/s
-STDraft: 104.5 tokens/s
Our STDraft is 18.8% faster than #DFlash 2 and 60.6% faster than MTP 🔥
And all this without any additional model training or weight changes! This is an early demonstration; stay tuned for more things to come 👀
@ItsmeAjayKV@Eschalabs Amazing work! If you are looking for a slightly better quant, you might also wanna play around with our model, also MTP + llama.cpp.
Full story in the blog post: https://t.co/4KduCxqplR
Grab the models on Hugging Face 🤗
→ OraQuant-GGUF: https://t.co/UqaPywqEDc
→ OraQuant-EXL3: https://t.co/yC4wkHoLKB
#AI#MachineLearning#OpenSource#LLM
Aggressively quantizing LLMs usually means significantly dropping their quality. We're changing that.
Meet OraQuant: our new quantization stack, which we used to quantize Qwen3.5-9B down to 2.84 bits per weight (bpw), an 82% footprint reduction while keeping it capable. 🧵
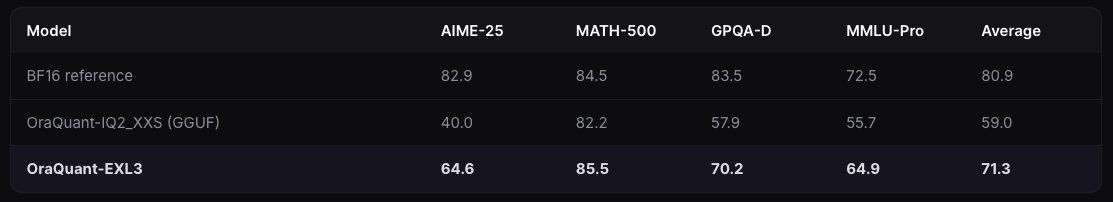
Same memory budget, different encoding — and EXL3 wins decisively. At ~2.8 bpw: EXL3 scores 64.6 on AIME-25 vs 40.0 for the GGUF model. Format is a real lever once you go low bits.