The economic value of agents will soon come from running whole autonomous businesses, not just from finishing one-off tasks. When you run a business, the result of your own decisions arrive weeks later. You have to notice them, trace them to something you did, and act before they compound.
Today, we're excited to announce SMB Bench, where we measure all the frontier models' ability to observe changes in the environment and adapt accordingly.
The economic value of agents will soon come from running whole autonomous businesses, not just from finishing one-off tasks. When you run a business, the result of your own decisions arrive weeks later. You have to notice them, trace them to something you did, and act before they compound.
Today, we're excited to announce SMB Bench, where we measure all the frontier models' ability to observe changes in the environment and adapt accordingly.
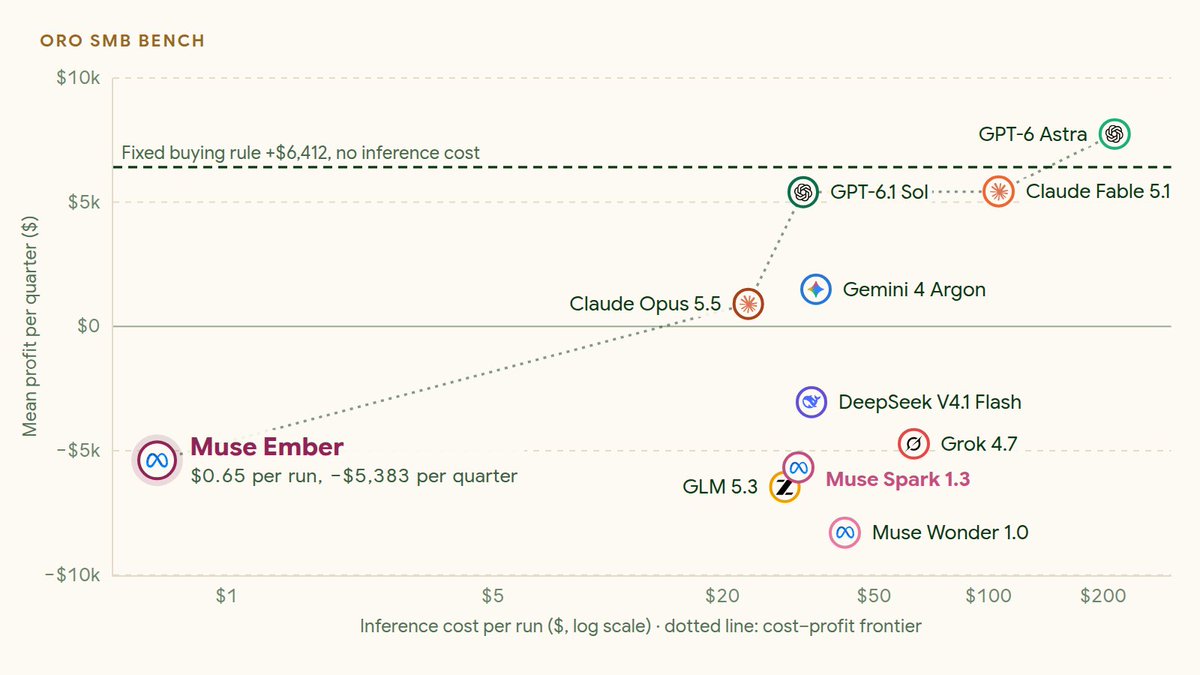
On SMB Bench, Claude Fable 5.2 at high reasoning effort is the second model to beat our naive buying rule.
It still shows the gap we see in other models, to a lesser extent. It identifies that shorting a customer costs future orders, and it acts on that, but only partially: it protects about half of the shortfalls it could, and its customers still end the quarter ordering far less.
It also underweights second-order effects. It recognises that its own decisions change how customers behave, but in several runs it only acts once its own records have confirmed the damage, weeks after it began and weeks after the necessary information is available.
When business is steady, Claude Fable 5.2 is the best agent buyer we've tested. It makes more money than GPT-6 Astra and more than a simple rule that just reorders the same amounts.
When its own decisions start driving customers away, like in the real world, that lead disappears. It does no better than the simple rule, and Astra pulls ahead.
It sees the problem. It just doesn't fully act on it.
Full report (Fable 5.2 results added later today): https://t.co/snogFGRIwO
On SMB Bench, Claude Fable 5.2 at high reasoning effort is the second model to beat our naive buying rule.
It still shows the gap we see in other models, to a lesser extent. It identifies that shorting a customer costs future orders, and it acts on that, but only partially: it protects about half of the shortfalls it could, and its customers still end the quarter ordering far less.
It also underweights second-order effects. It recognises that its own decisions change how customers behave, but in several runs it only acts once its own records have confirmed the damage, weeks after it began and weeks after the necessary information is available.
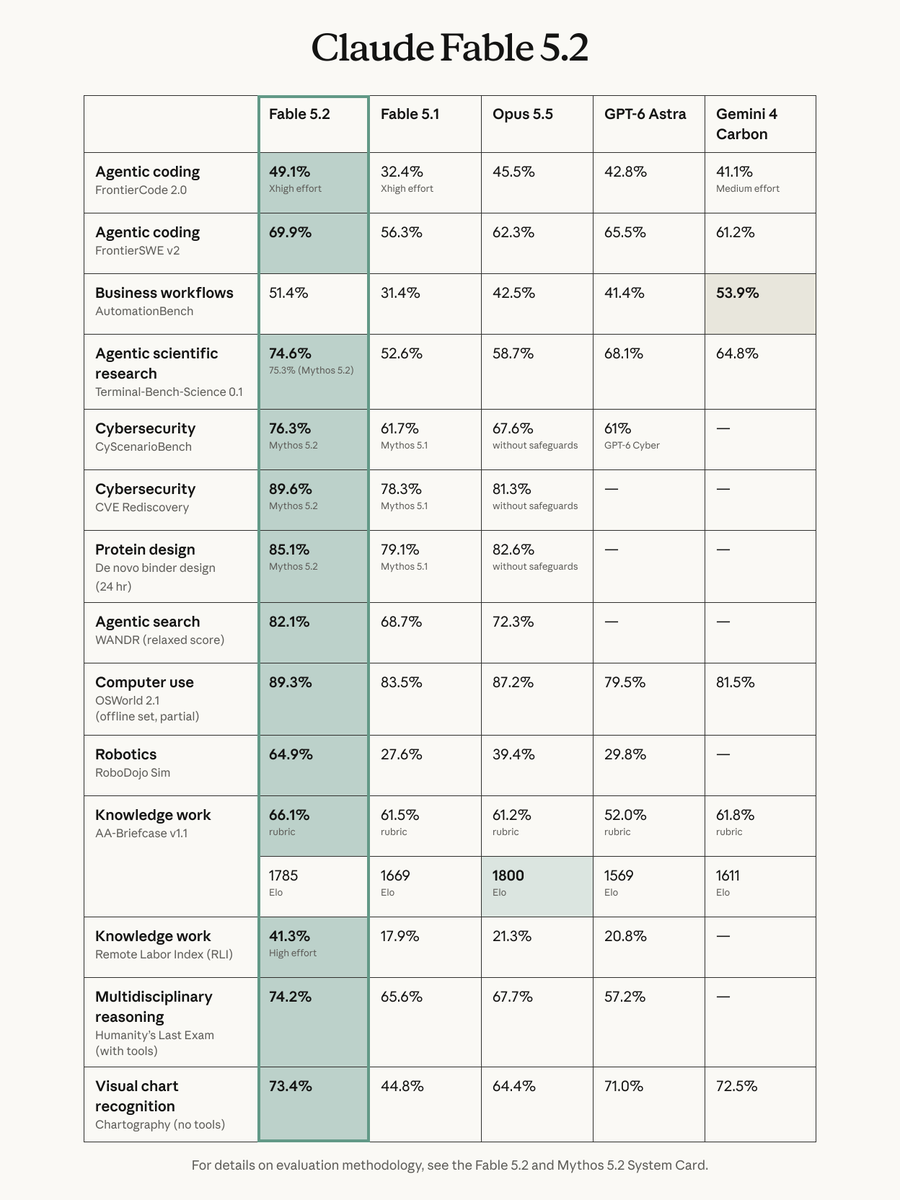
Fable 5.2 and Mythos 5.2 are a step above Opus 5.5 in almost all the capabilities we evaluated.
Testers have found that they communicate more clearly than past Fable and Mythos models. They generate outputs up to 30% faster than Fable 5.1 and Mythos 5.1.
@finkd On our recently released benchmark that tests models running a wholesaling business, the performance is in line with GLM 5.3, Grok 4.7, and Muse Spark 1.3.
Interestingly, Mused Wonder 1.0 is still the least performant.
Working on Luna & Haiku evaluations for true comparison.
For AI to be a productive economic actor, it will have to learn the tacit knowledge that lives with the people who do these jobs, and learn it the same way we do, from the results of its decisions.
SMB Bench is a high-fidelity simulation grounded in real, public data in which that learning can be observed. With it, we have taken a step in identifying the gaps in AI running a profitable autonomous business.
We think this is one of the most important problems in AI right now, and we are only getting started. If it excites you too, please reach out, we would love to talk: [email protected]
ORO changelog, Oct 18 to Nov 1:
- ORO Bench now tests agents in shops with their own products, tools and situations, with pass/fail task scoring
- New public practice world for local testing, graded the same way validators grade
- Validators need v3.0+, and SDK clients need oro-sdk / oro-ai/sdk 7.0.0+
- Clearer episode feedback and more complete inference cost reporting
check out our changelog and what we've been working on: