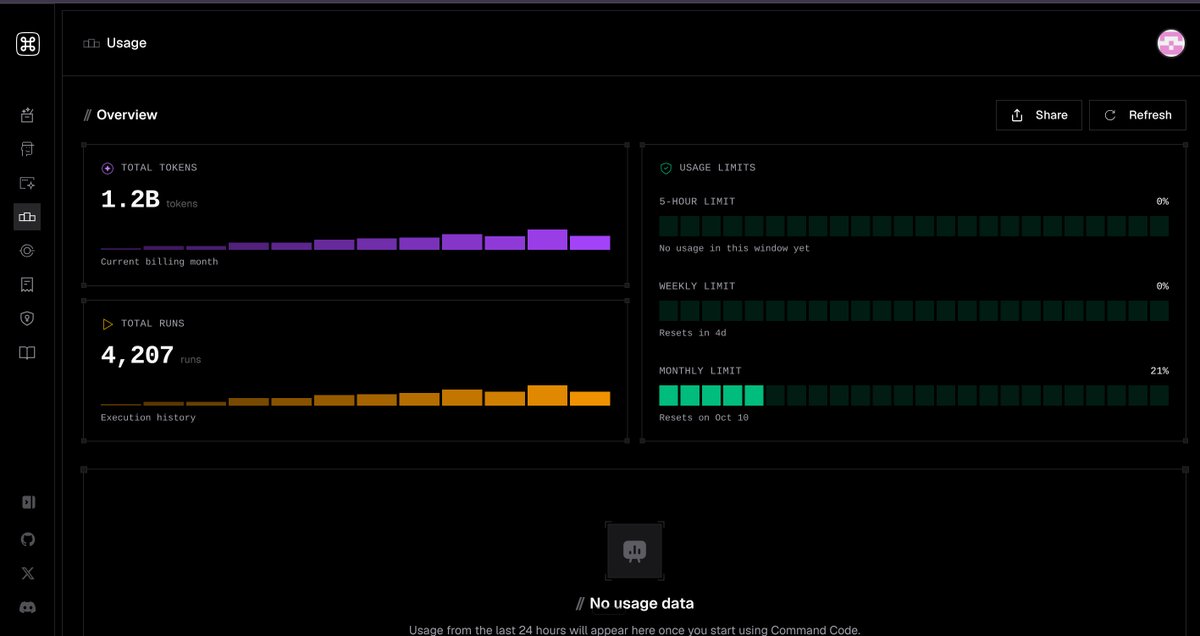
Tbh i think it was a scam , because they promote themselves as like cheap optionf by making the api which people will see before subscribing , but when you subscribe you find that they steal you
@1r0nM1nd who say that they dont gave more than claude and gpt? i just say that command code promote themselves as better limits , but we actually see the opposite
I subscribe in both Command Code GOAT plan ,and in OpenCode GO plan and OpenCode look dominating here in usage.
Command code say they gave 70$ worth of usage + better Cache Hit percentage .
but this is just for marketing .
I use OpenCode heavily , I’ve consumed 3.68B tokens, almost entirely with DeepSeek V4.1 Flash, and I’ve only spent $20.
With Command Code, I used only 1.2B tokens with the same model I use in OpenCode, yet it already consumed 21% of my monthly usage.
For Budget Users i think OpenCode Go is the best subscription per value you can get
@ALX23uz Yes i think it make better result than the previous models but we cant say its very good
i think even DeepSeek V4.1 flash make better result
i use codex , my prompt is very good . no setup issues
GPT-6 Sol just one shooted one of the best results i have ever seen
I test it in a task to make a ship in the sea and it cocked it so hard
it even make a phone version which is my first time see a model make
but it have some down sides in the details as you can see
it complete very fast , like one of the fastest (22 minutes ) , even beating luna which make 26 minutes
The downsides is like there is glitch in the ship sides
when i switch from night to light the ship change little bit
when its wavy there is some waves pierces the ship
Mimo V2.6 Pro and Mimo V2.6 Flash is a complete SLOP.
I try to use it in the ship test and it give me one of the baddest results i have ever seen !!
DeepSeek V4.1 Flash make better result than this like 100 times better.
This is why @Xiaomi make him cheap , because they know they make bad result .
Opus 5.5 dropped and they are saying it beat GPT-6 Astra in a lot of benchmarks
We finally get Fable 5.1 level but with more usage
But benchmarks dont prove anything , we need to test it
Step 5 Preview is just weak model !!
I test it in Ship in a sea test and it make one of the dumbest result i have ever seen
It take very long time (almost two hours ) without any benefits
Artificial analysis say this model is better than KIMI K3 , but in real life its the worst
Artificial analysis is not trusted anymore !