🏆 Achievement unlocked
I reached rank 3 on the kaggle competitions leaderboard last week. Just below @kagglingdieter and @ph_singer. This felt unreachable when I joined my first competition in 2019 and I am very thankful for what I learned from the @kaggle community since then.
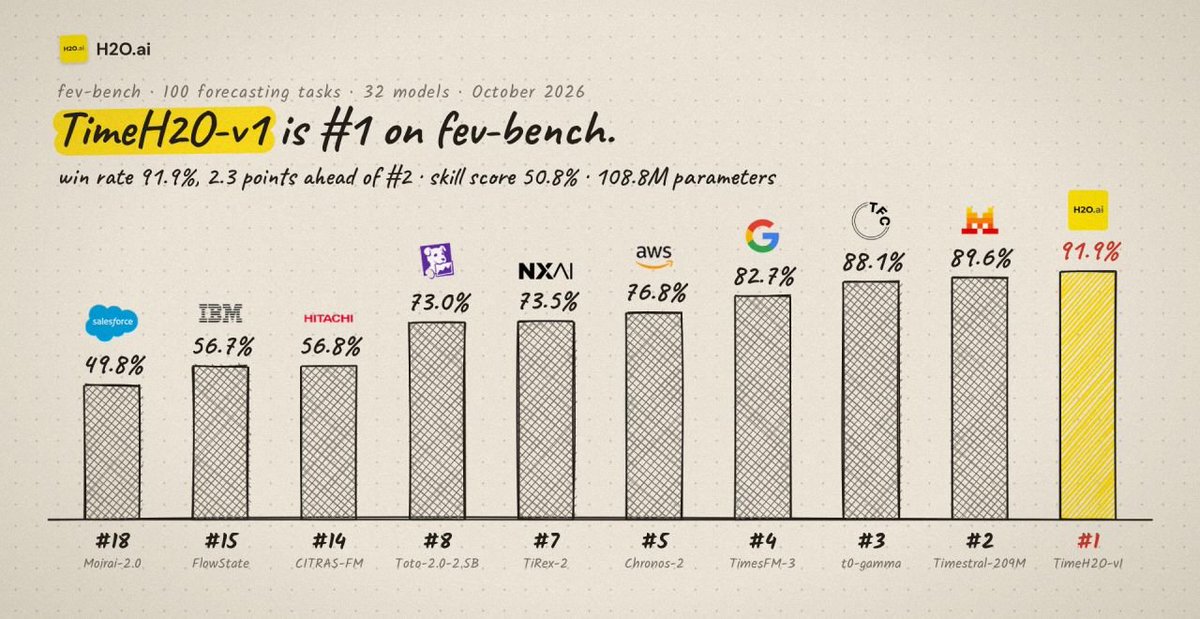
A live & daily updated benchmark shows TimeH2O on first place.
EnergyBench by Foretec runs every forecasting model each morning at 11:30 before Europe's day-ahead auction for energy. No leaks possible. This is as real as it can be.
@Kagglenizer@StackNet_ They also published a notebook on kaggle. In a nutshell, good data science is still a key differentiator (the David Thaler trick), but the model part is making huge leaps in recent time. https://t.co/8jkJPZK2EW
Time series foundation models are surprisingly strong. Worth a read how TimeH2O is doing on a #kaggle classic in the hands of KGMs @Kagglenizer and @StackNet_: https://t.co/bciNJ9lqyR
TimeH2O-v1 on a @kaggle classic.
Walmart Store Sales Forecasting, post-competition:
2277.69 WMAE vs the winning 2301.49.
No feature engineering. 500 steps of fine-tuning + David Thaler's Christmas shift from his 2014 win. Credit where due.
Notebook: https://t.co/2K1K0SyPBF
@nikitabier I am sure there will be some kind of authentication required soon to post online and limit of accounts to one person. Prevent multi/slop/bot accounts. You can still automate or use AI in your account, but it would stop the 50 AI accounts for individual users.
@olivkoch Fully agree. I was just wondering about the validation approach you took. Even for 4x4 sudoku, you should absolutely be able to train leak free by making the proper splits between train and val/test.
For the 6x6, even with >28M variants, I'd check for overlaps as well.
@giffmana@garybasin Doesn't need to be image-only as output, does it? Of course wouldn't be as simple to train as semi-supervised next token prediction, but maybe we are already at the point where we feed all available messy data in the world through existing LLMs to generate multimodal labels.
@art_zucker call me crazy, but I always come back to sublime merge as being the most easiest to manage bigger diffs.
But it is UI based, not in terminal, so doesn't work well for remote setups.
@levelsio though, I agree, it is something that should have been solved long ago if the incentives were there.
Also some AI content may arguable be fine, like writing bullet points and asking a AI to make a tweet out of it. Or spell/grammar improvements.
@levelsio the detection model doesn't need to be bigger. it also doesn't have to be smart in a general way, this is a very narrow task.
For AI detection, we are talking about a classifier similar to spam detection.
I truely believe it just needs a good amount of labeled data to train on.
@svpino If only Apple would have the standard T2/T1 keyboard layout in germany. I still find it super annoying to switch between keyboard layouts when using anything else vs. Apple.
@cloneofsimo what is the idea behind scaling weight decay based on fan_in just like LR? Isn't the purpose of the AdamW fix to have wd mostly independent of LR? Happy for pointers to actual ablation studies on this on large token counts.
@giffmana Even a few hundred samples from open source datasets available in huggingface can bring the models to answering like this.
Early days open assistent and ShareGPT data come to my mind.
Big corps spend quite some effort to "clean" their data and to teach the right identity.