@amugnolo Started using FreeBSD because @amugnolo was using it. After 15 years of servers and laptops, I finally yielded to MacOS because of companies I worked at. I want to come back to my first unix love and this is a perfect opportunity. Thinkpads and FreeBSD nostalgia
Today's AI models are a technical marvel. With enough expertise, you can steer them almost anywhere. But by default they have to serve many masters, and easy prompts give you bland results.
Magnific is not build for "anyone." We serve creatives, and the default mode on these models is not what our users want.
Months ago we started a project with these goals:
1) built on top of existing models. Leverage the existing AI models as the building block. Get better when models get better.
2) make the default generation by and for creatives. Easy to get great results.
3) trivial to stay on brand.
A new model from scratch will be something that will become obsolete in weeks / months. Our approach enhances them for our users, making a useful contribution that is long-lasting and differentiated.
After many false starts, we landed on a pre, post-processing, and routing layer on top of a few of today's state of the art models.
We tested the model first with our employees, and later with external users, on two tests: best image for a given prompt, and best image overall (blinding the prompt). The first checks prompt adherence, the last checks image aesthetics.
Magnific One came out first on both tests by a wide margin.
You can use it exclusively on @magnific, test it yourself and tells us what you think.
Introducing Kardashev-0.7, the world’s first trained swarm made of 32 distinct models
Trained with RL for Population Scaling (RLPS), 32 models organically develop specialization & complementary capabilities, delivering frontier performance at:
- 0.007x ~ 0.02x of the inference cost
- 0.03x of the required memory
Civilization advances through different minds specializing and working together. We’re bringing that principle into AI
@BanburyRoadAI, we’re scaling intelligence by model count, toward civilizations of models that learn to build on one another
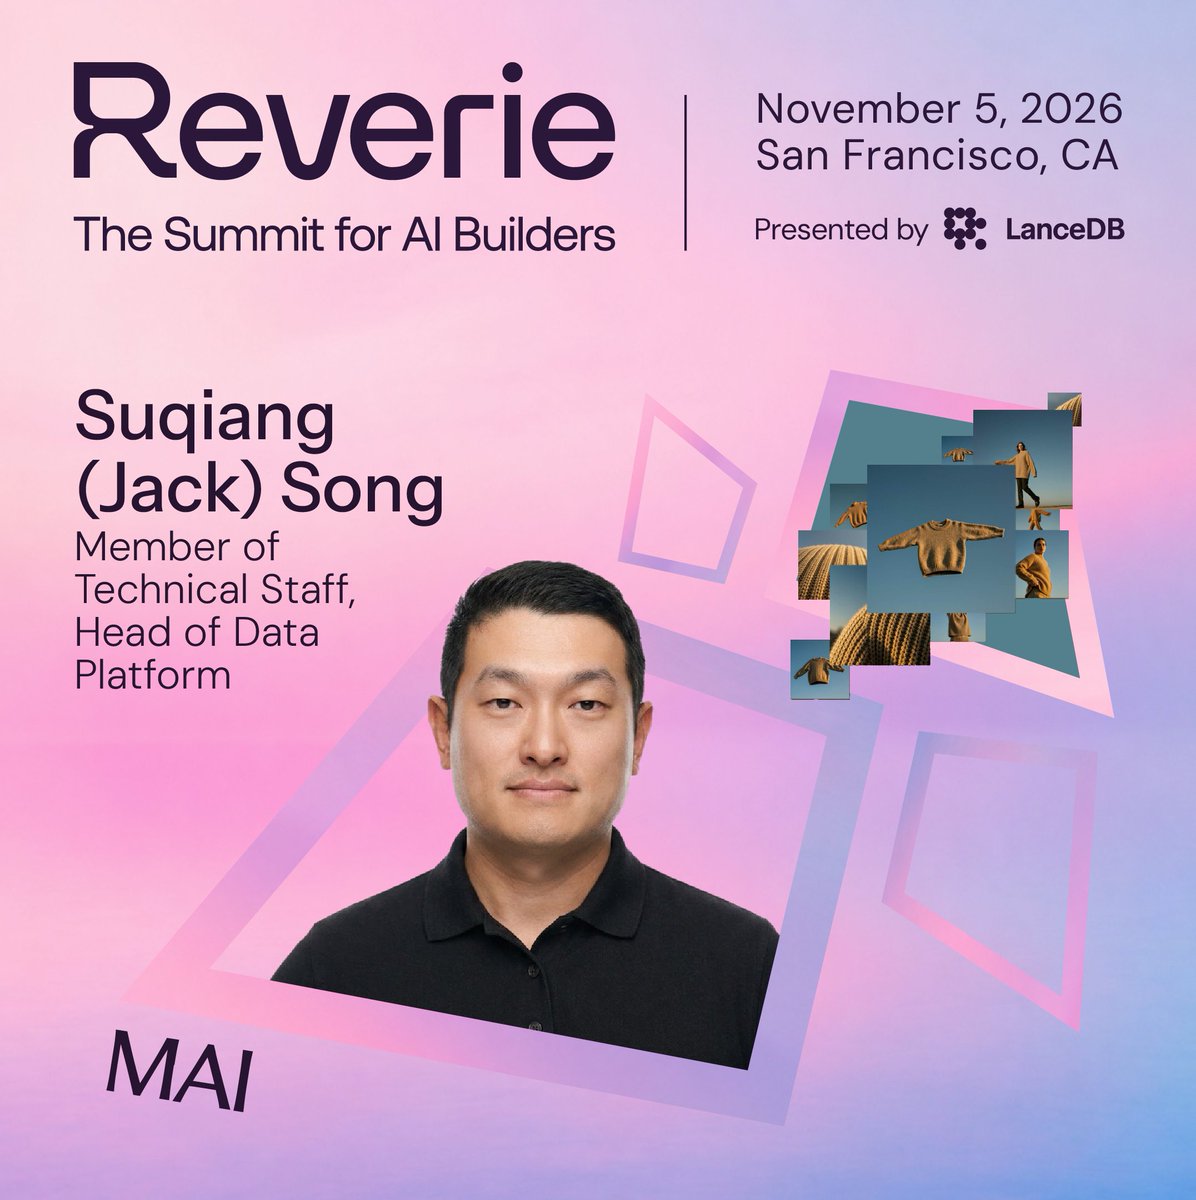
@MicrosoftAI’s Suqiang (Jack) Song is speaking at #Reverie2026.
Hear how MAI is building the frontier AI data flywheel, from curation and deduplication to search and training, with different workloads running on the same underlying data.
Apply to attend → https://t.co/Ol31DCH93G
We’re now offering custom keyboards for businesses.
Customize keycaps, logos, nameplates and packaging for your team or brand. Here’s a look at what we created with Raycast.
Explore the options: https://t.co/2De70JRALo
#nuphy#customkeyboards#brandcollaboration
🚀 Sol-Attn is here!
We present a training-free sparse attention method that accelerates video generation while better preserving quality.
Sol-Attn unifies dynamic routing, sparse computation, and approximate correction in a single online-softmax pass:
• On-the-fly block thresholding for dynamic yet controllable budgets
• Proxy-score reuse to approximate unselected blocks
Results (vs dense FlashAttention-3):
• Wan 2.1-14B: 2.02× end-to-end
• HunyuanVideo-13B: 2.12× end-to-end
• LTX 2.3: up to 2.4× end-to-end
When integrated into Sol-Engine (with kernel fusion + caching):
• Wan 2.1-14B: 3.48× end-to-end
• HunyuanVideo-13B: 5.08× end-to-end
Already available in Sol-Engine.
The B200 kernel is still under further optimization.
🎬 Project: https://t.co/WvnCcpyRx3
📄 Paper: https://t.co/R8hmPLnONM
🔗 Code: https://t.co/1E1GaRnWcd
Very cool to see @netflix releasing video datasets and models on @huggingface. They have a strong video AI team and would be amazing to see them open-source more!
https://t.co/5bVKjn6wEp
Data processing has become a GPU workload and is dominated by inference. A new architecture is required, and it is not Spark on GPUs. https://t.co/KmSL6aYDmz
1/ World model research is fragmented: every paper reimplements its own data pipeline, baselines, and eval harness. Comparing two methods fairly is weeks of infra work.
𝘀𝘁𝗮𝗯𝗹𝗲-𝘄𝗼𝗿𝗹𝗱𝗺𝗼𝗱𝗲𝗹 is a new open-source platform that standardizes the whole thing: https://t.co/Gg3V3LhKJr
in case you missed it @lancedb and HF are partnering up to unlock the next generation of large dataset storage on the Hub 🔥
And it's fire!
- Supports storing embeddings (and their indexes) directly alongside the data
- Vector search / similarity search is built-in
- Large multimodal datasets (text, images, video)
just use the hf:// prefix:
db = lancedb. connect("hf://datasets/julien-c/hub-stats-lance")
🔥🔥