Jon Hamm and Anna Osceola turned their Mad Men connection into a real-life love story. From meeting on set to enjoying their honeymoon in Mallorca, Spain, in 2023, their story is one Hollywood romance fans love to see.
Primer Propuesta: Violacion-Atencion-Farmacia Privada para medicamento
Segunda Propuesta: Violacion-Atencion-Prueba de Embarazo-<Farmacia Privada/Pastilla Publica
UNA PASTILLA!!!! Una Puta Pastilla!!!
@atrejoscr2_0 Con prueba de embarazo previa, comisión se compromete a reincorporar anticonceptivo de emergencia en proyecto de atención a víctimas de violación https://t.co/6Ic7kvr7C7
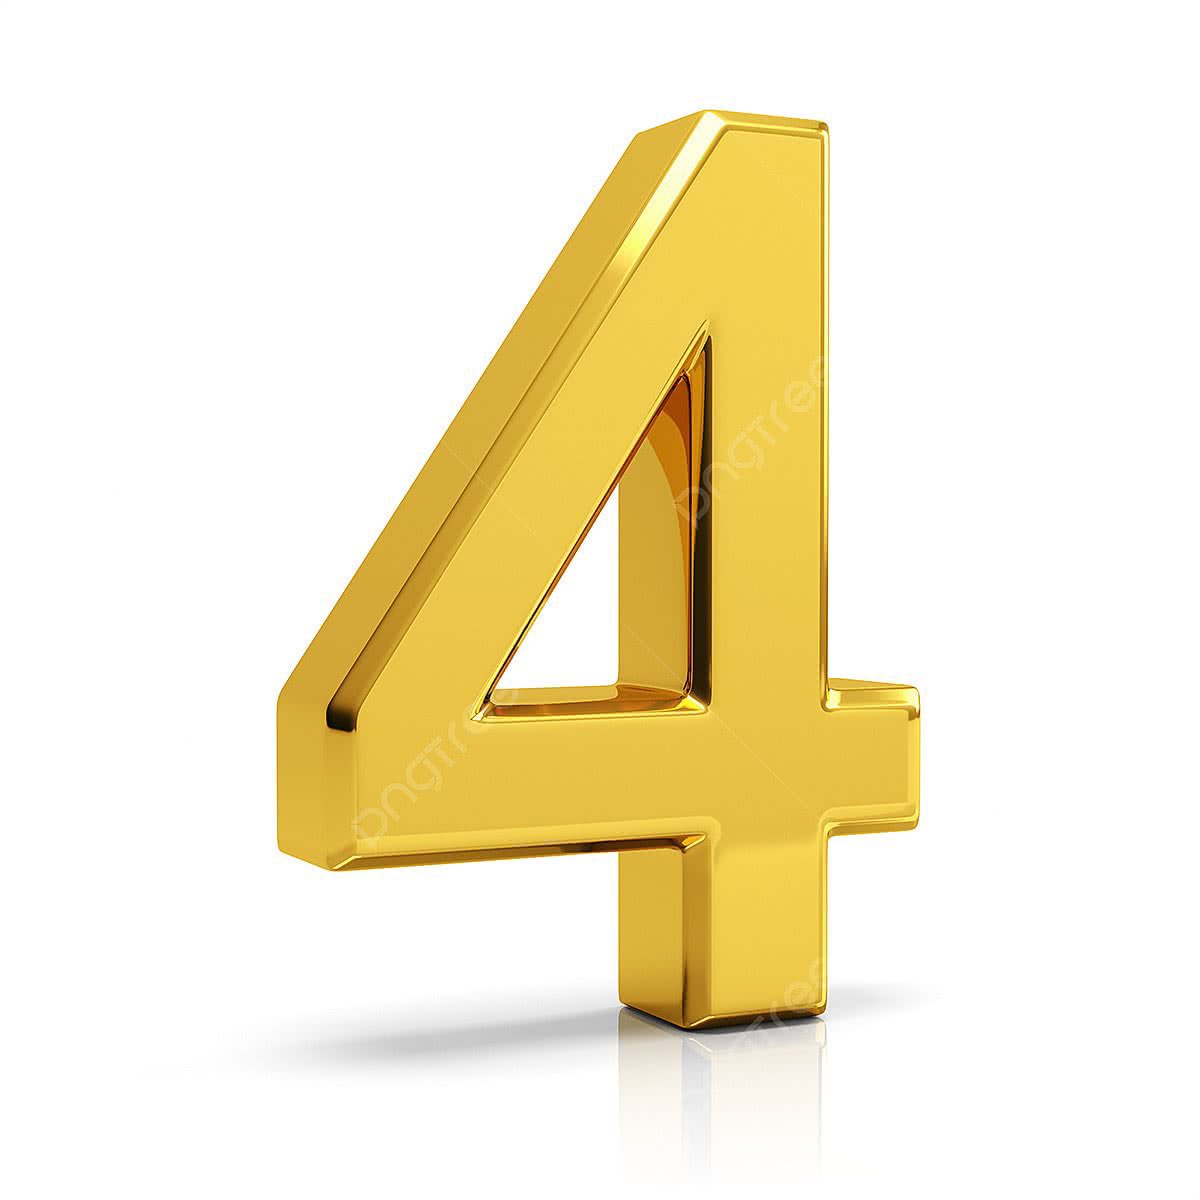
‼️ BREAKING: eMudhra, the Indian certificate authority whose private key was the number 4, is quitting the TLS business.
It blames social media for scrutiny "out of proportion" to a unit worth ~1% of revenue.
8 of its CA keys were numbers below 256, cracked in milliseconds.
@KarlosAvila Mae yo por la viajadera lo que hago es que dejo en la oficina la MacBook Pro y cuando salgo me llevo la iPad Pro, uso Moshi con tmux para remoto, hooks y hace poco ya jugando de vivo reacomode todo y arme un “Context Bus” sigo mejorando pero ya casi vale madre cual LLM se pega
Tal vez se perdieron esto, Vivek pensó que habia cocinado sacando a la mama de la Candidata Demócrata a decirle mentirosa, la mama había ignorado denuncias de violacion y abusos de la hija y jalo con el padrastro
🇺🇸🇮🇳 Vivek Ramaswamy is facing intense backlash after releasing an ad featuring his political opponent Amy Acton's own mother disavowing her.
Acton's mother lost custody of her children after years of documented neglect, including time spent living in a tent and a spouse who sexually abused Amy. Acton's brother has also confirmed this story.
Ramaswamy's betting odds for winning the gubernatorial race have plunged sharply since the release of the video.
Justo resumía eso en otro tuit; es una canallada dudo que sea un monto alto que se vaya en esas pastillas y por jugar de radicalitos hacen estas canalladas, lastima no se detenta la gente a pensar ni ellos pero bueno ayer subieron la foto de la ManzaPipa con 7 puros del hijo de la Diputada, fijo estaba puteada
As I said earlier, cybersecurity is one of the most important skills to learn today.
Look at what’s happening right now:
🚨 PHP Remote-Code Execution
🚨 LiteLLM Supply-Chain Backdoor
🚨 eMudhra Certificate-Key Compromise
🚨 Node.js Critical Vulnerabilities
🚨 Next.js Remote-Code Execution
🚨 TiDB Cloud Data Breach
🚨 Plex2Shell Active Exploitation
🚨 BeyondTrust Zero-Day Exploitation
🚨 Ivanti Zero-Day Exploitation
🚨 Railway Security Breach
One vulnerability can wipe out years of hard work in hours. AI is making it easier to build software. But securing that software is becoming an even bigger challenge.
The future won’t belong only to people who can build with AI. It will belong to those who know how to secure what they build.
WTF, $3000 Samsung TV has an always-on mic, automatic content recognition, geo tracking, network mapping, and ships your data to Samsung + 400 partners.
Bro Rooted a brand-new 2025 Samsung TV after noticing absurdly targeted ads.
Firmware was locked down, so zero-days it was.
Got a root shell.
then found: always-on voice service, ACR, geo, full telemetry pipeline, and four separate DRM systems.
This isn’t a bug, It’s the product bro.
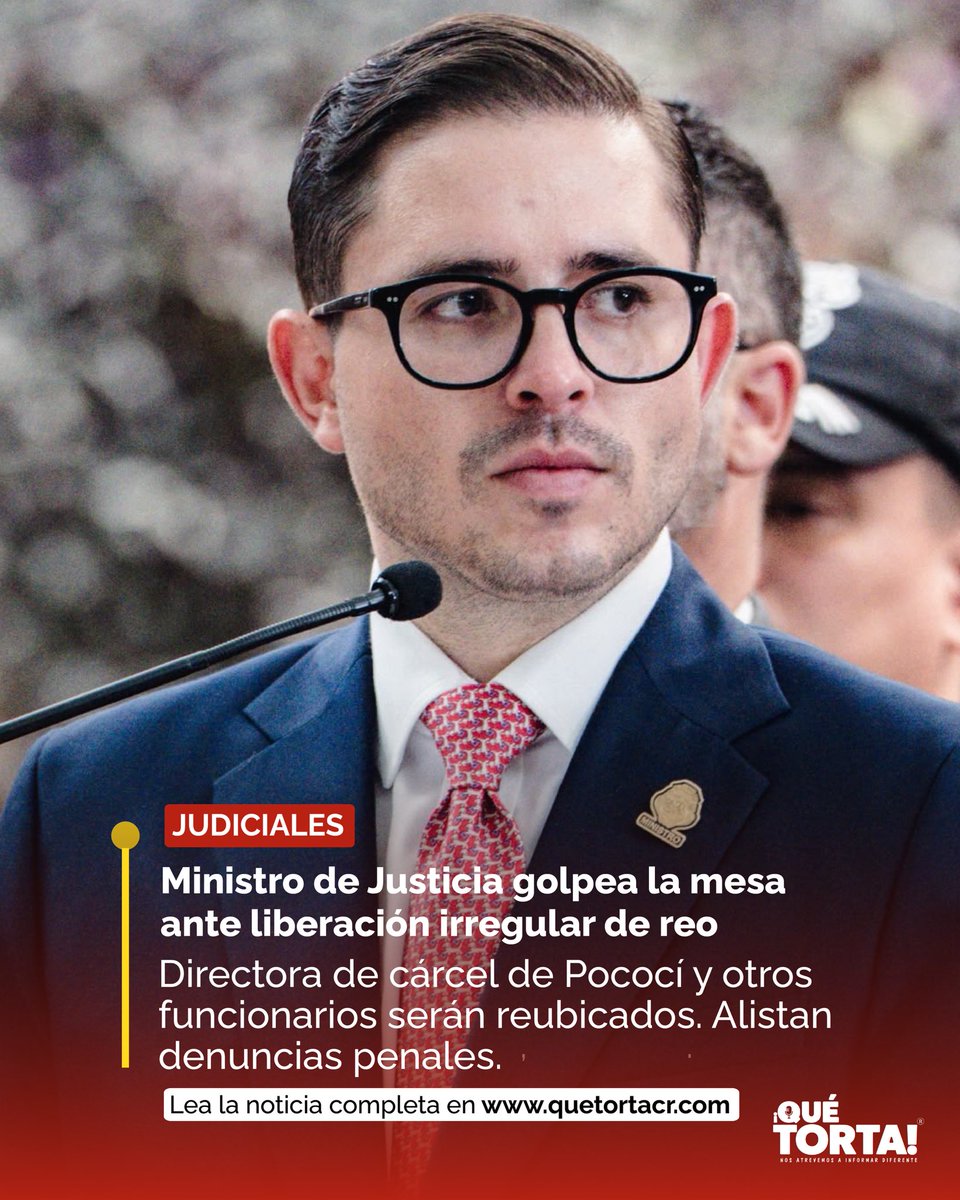
Si sale un mae denunciando malos tratos fue Carlo Diaz, Si vuela un drone sobre unas chozas amedrentando fue un Policía, si liberan a un compa por allá fue el funcionario; pero quien esta a cargo? Esto le pasaba al PAC? Al PLN? O solo al Chavismo?
@twostraws Apple is taking them at good prices for a swap, dropping mine for a Mini M6 in nov probably, i do have anothet laptop but iPad Pro+Moshi Combo works amazing as a side portable
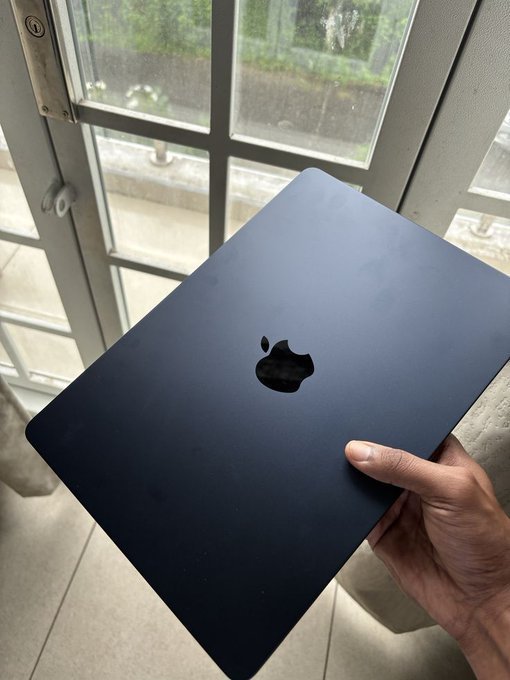
Qwen3.8-27B is reportedly reaching 70 tokens/sec on an M5 Max MacBook Pro with DFlash 2.
That is a substantial speedup for running a 27B model locally, especially on a laptop.
DFlash 2 is the next generation of speculative decoding technology, seeded at Z Lab and further developed by Inco AI.
The idea is to reduce the cost of generating text one token at a time.
In standard autoregressive decoding, the model generates a token, processes it, and repeats the process for the next token. This sequential process can become a bottleneck, even when the model already fits comfortably in memory.
DFlash 2 takes a different approach. It uses a draft mechanism to propose multiple future tokens, allowing the main model to verify them together. When the proposed tokens are accepted, the system can generate more text with fewer expensive decoding steps.
The result is potentially higher generation speed without changing the final output compared with standard decoding under the same settings.
The headline claim is up to 4.6× faster than conventional autoregressive decoding. The actual gain depends on the model, hardware, workload, and how many draft tokens the main model accepts.
The reported 70 tokens/sec on Qwen3.8-27B with an M5 Max is particularly interesting for people running larger open-weight models on Apple Silicon.
It suggests that local inference performance is not just about model size or buying a more powerful machine. The decoding algorithm and inference engine can make a significant difference, too.
One important distinction: the 4.6× figure is a claimed maximum, not necessarily the speedup achieved in the M5 Max test. A direct comparison needs the baseline speed, prompt length, context size, and exact decoding configuration.
If DFlash 2 can consistently deliver these gains across different workloads, it could make local coding assistants and other text-generation applications noticeably more responsive.