@bravish_ this is super cool, congrats on the launch. great for enterprises, these days i trust opus more than i trust myself so i'm probably not the target audience 🤣
@priymrj i don't think fable was ever built for us. so many people complained about opus 5 because it was built as a subagent for fable, and anthropic was using fable internally all the time, but for us normal users fable is too expensive
@CoFoundersNik "pay for ai" is a weird bucket, i think a lot of usage is buried in microsoft, google, and work seats that never show up as a household chatgpt line item
chatgpt to me always felt lifeless like an actual bot and their products without taste and not much care
claude feels like it has "soul" and personality whatever that is inside LLMs
great models on both sides but the missing piece on chatgpt isn't iq it's that care/taste layer anthropic somehow baked into claude
@scottstts@claudeai yeah i mostly stopped compacting. gpt handles it better but the context is tiny anyway. better move: keep progress in an md, tell claude to dump the thread into MD file, and if you do compact do it while the cache is hot, not the next morning. overnight cache is already gone
The European Commission has rolled out an alternative to Microsoft Teams.
But officials using it aren't impressed, with one describing the tool as “absolute shit.”
https://t.co/WbVwHQ29RP
Ari solves a Rubik's cube while Griffin coaches him from what it sees in his hands, and when he goes quiet to think, it waits. Its perception is always on, so it acts without being asked. Note: this actually blew our minds seeing happen live.
Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
@IndraVahan shh. nobody tell them we don’t need another ai assistant that reserves 10 restaurants, calls a plumber, and builds an app before i finish taking a sh*t
google says gemini 4 argon agents already freed over 300 tib of memory across its data centers, with a 1m-token output limit and agents optimizing their own infra.
argon agents are also on c/c++ -> rust migrations hitting 800k+ lines of kernel code making an existing rust port 2.7x faster with identical output,
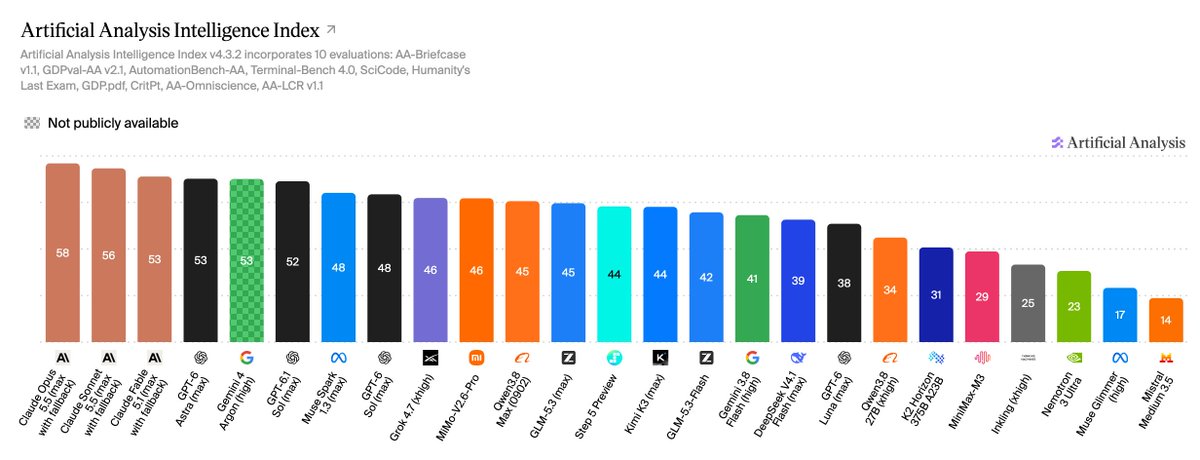
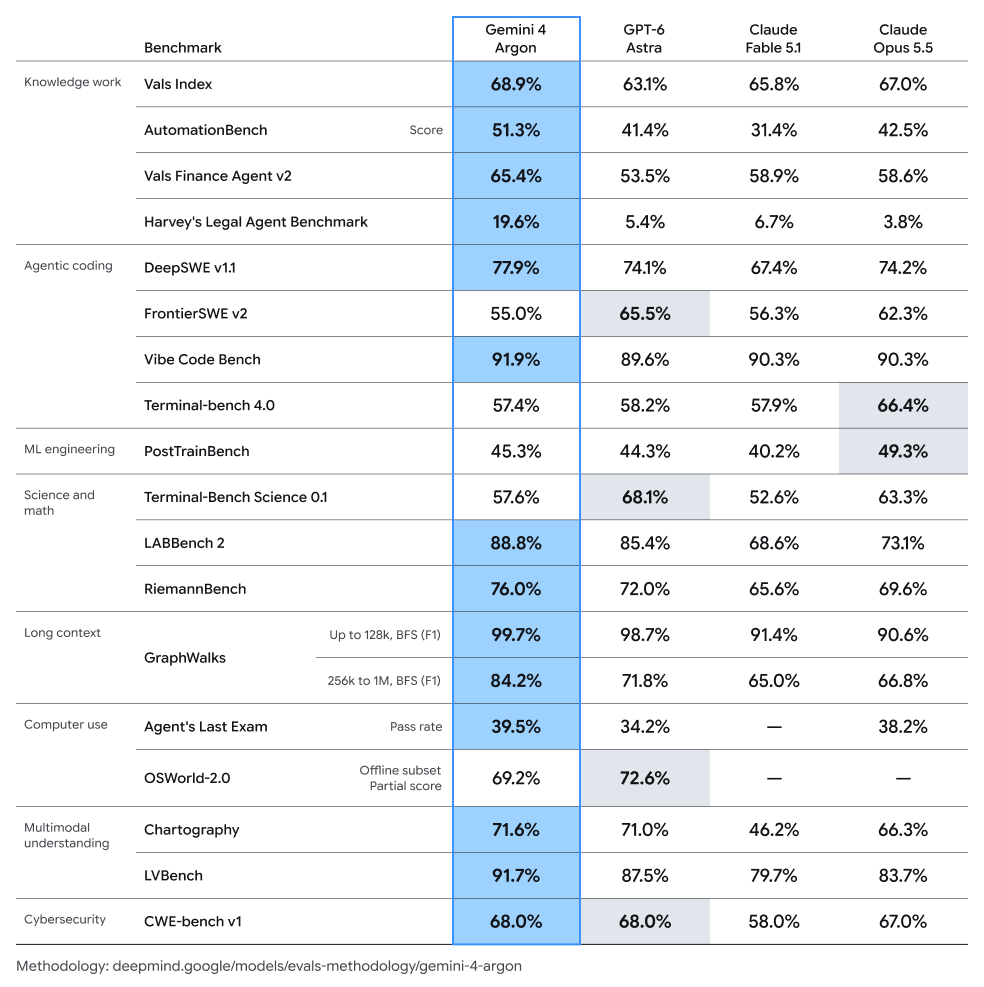
but one thing a lot of people miss is that google isn't trying to beat opus 5.5 or astra at the frontier throne anymore. it's nearly impossible to compete with anthropic and openai
they figured most people don't need another astra-class brain; most people will happily use gemini flash, and the real gains live on youtube, on phones, partnering with apple, agentic video understanding. those pieces mattered and they focused on shipping that first (gemini flash) before another large LLM model
but one piece was still missing: internal use, google can't lean on anthropic and openai for that, first compute, second the cost
google had its problem and was stuck splitting capacity between users and their own employees. Adam Bender talked about this at Google I/O 2026 in "software engineering at the tipping point": how internal demand for compute to run large generative models and automated coding agents created intense competition for capacity inside google's developer infrastructure, and how engineers and internal tools leaning on models for codegen, linting, and planning across millions of daily ops forces you to optimize inference for cost, speed, and hardware utilization
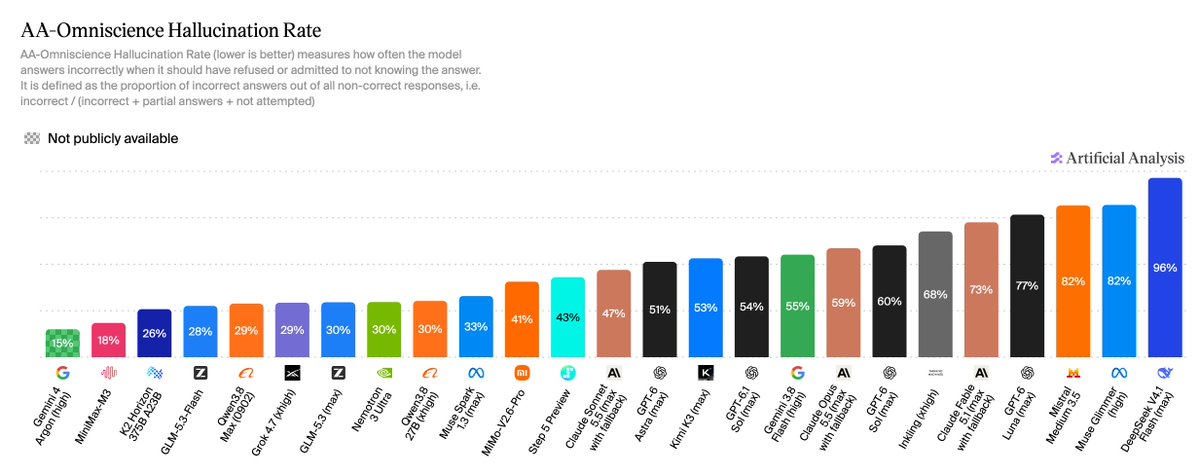
that’s where gemini 4 argon comes in. it's not better than opus 5.5 or astra. it doesn’t have to be. that's how google is playing the new ai era
they shipped gemini 4 argon for google
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
anyone who works with llms daily sees this regression everywhere not just chat, coding too. it'll sell you the wrong fix and swear it's right until you poke it from other angles and feed more context. at the end of the day it is gradient
the real advances in AI this past year were consistent tool calling, bigger token budgets, and more context not some leap in "thinking" or llms getting sentient