👋 Hi from Papers.Data.Code
We track ML research from arXiv, GitHub, and Hugging Face, surfacing what's worth your time.
Here you'll see:
📄 Daily ML picks: papers, repos, datasets
📋 Weekly TL;DR every Friday
🧵 Monthly, quarterly, yearly threads at horizon turns
🌱 Tracking growth and impact of selected works
Selected, not collected.
Full feed → https://t.co/nGRf9ZUha0
Digests → https://t.co/wlpnEMU8qu
📋 ML Weekly Recap · Sep 28 – Oct 04
⚡ Trends
▸ Test-time context or future-state conditioning improves long-horizon agents and world models
▸ Efficiency-focused inference and attention redesigns cut latency without major quality loss
▸ Large specialized benchmarks emphasize zero-shot generalization, grounding, and reproducible evaluation
🧭 TL;DR
📄 TabFM: A Zero-Shot Foundation Model for Tabular Data
Weihao Kong, Erez Louidor Ilan, Shuxin Nie et al.
Zero-shot tabular FM beats tuned AutoGluon across 51 datasets.
📄 https://t.co/5FmajKO6dr
⭐ CLM
Practical low-latency decision scoring matches Jev on real agent tasks.
⭐ https://t.co/ZodnYGZQkF
💡 Models increasingly externalize structure to gain efficiency, generalization, and controllability.
→ https://t.co/wlpnEMTAAW
📄 Context Language Models
by Rulin Shao (@RulinShao), Shannon Zejiang Shen et al.
Rather than external memory policies, the LM edits its own context file in place. This makes context management a native behavior that can be prompted or RL-trained.
Key points:
• BrowseComp-Plus: +11.4% accuracy with 21.5% fewer FLOPs vs best baseline
• 12-hour EdgeBench: +5% score with 59% fewer FLOPs vs summarization
• RL on Qwen3.5-9B: 28.8% -> 42.5% on BrowseComp-Plus with 12% fewer FLOPs
Making context management intrinsic to the model yields better long-horizon agent behavior than fixed external memory policies, while also lowering compute.
📄 False Frontiers: Diagnosing and Mitigating Co-Cheating in Self-Evolving Search Agents
by Meijia Chen, Hao Li et al.
Cross-fitted proposer feedback replaces same-source evaluator reuse with source-excluded scoring, while leaving the main solver training rule unchanged.
Key points:
• Avg Cover-EM 48.8/51.2, +8.8/+8.4 pts vs Dr. Zero at 4B/9B
• False-agreement mass drops 6.1%→3.0% and 8.8%→3.7% with CrossFit
• Beats Search-R1 by 8.7/7.8 pts average across 7 benchmarks
The main failure in self-evolving search is feedback provenance: excluding same-source training from the evaluator sharply reduces shared-error reinforcement.
🧵 The 3 #ML Datasets that shaped Q3 2026
1. secemp9/arxiv-complete
Unlike paper-text corpora, it combines 3.15M arXiv papers with source files, resolved TeX, and 5.03M-version history in one auditable 16.08 TB snapshot.
2. microsoft/XL-DocBench
Unlike broad corpora, it tests evidence-grounded QA over documents up to 2,935 pages with page-level evidence, cross-document questions, abstention, and only 38.36% top accuracy.
3. hamzabagirsakci/turkish-court-decisions
It offers 11 million CC0 full-text Turkish court decisions spanning 1962–2026 across five court systems.
Full breakdown ↓
🥈 XL-DocBench by microsoft
Contains 1,345 expert-verified QA records over 292 long professional documents, with page-level evidence for single-doc and cross-doc QA.
Key points:
• 1,345 total questions: 1,191 single-doc + 154 cross-doc
• 292 documents from 6 professional domains
• 429 multimodal-evidence questions; 188 require None answers
Growth since tracking: 24 days through Sep 27
📥 1k (+1k) · ❤️ 7 (+1) · 📚 0 (+0)
📊 https://t.co/cIbIgWXrUw
📄 https://t.co/lKbbSJMHHA
📊 PETARSeg-11K by UW-Madison-Dept-Radiology
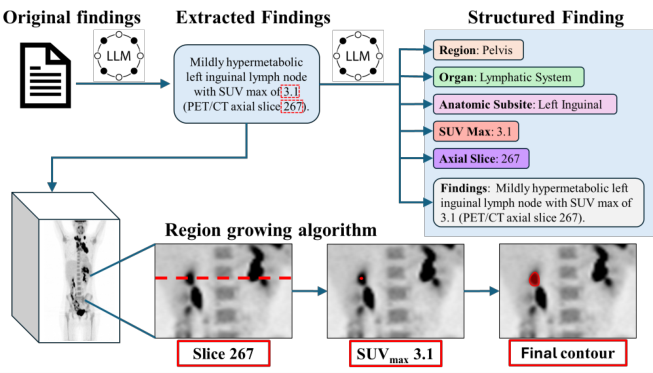
Contains 11K-scale PET/CT data with lesion-level correspondences between localized abnormalities and free-text radiology findings.
Key points:
• 11K-scale dataset
• PET/CT imaging paired with text
• Lesion-level spatial grounding annotations
Useful for training and evaluating lesion-grounded PET/CT report generation and vision-language models.
📥 126 downloads
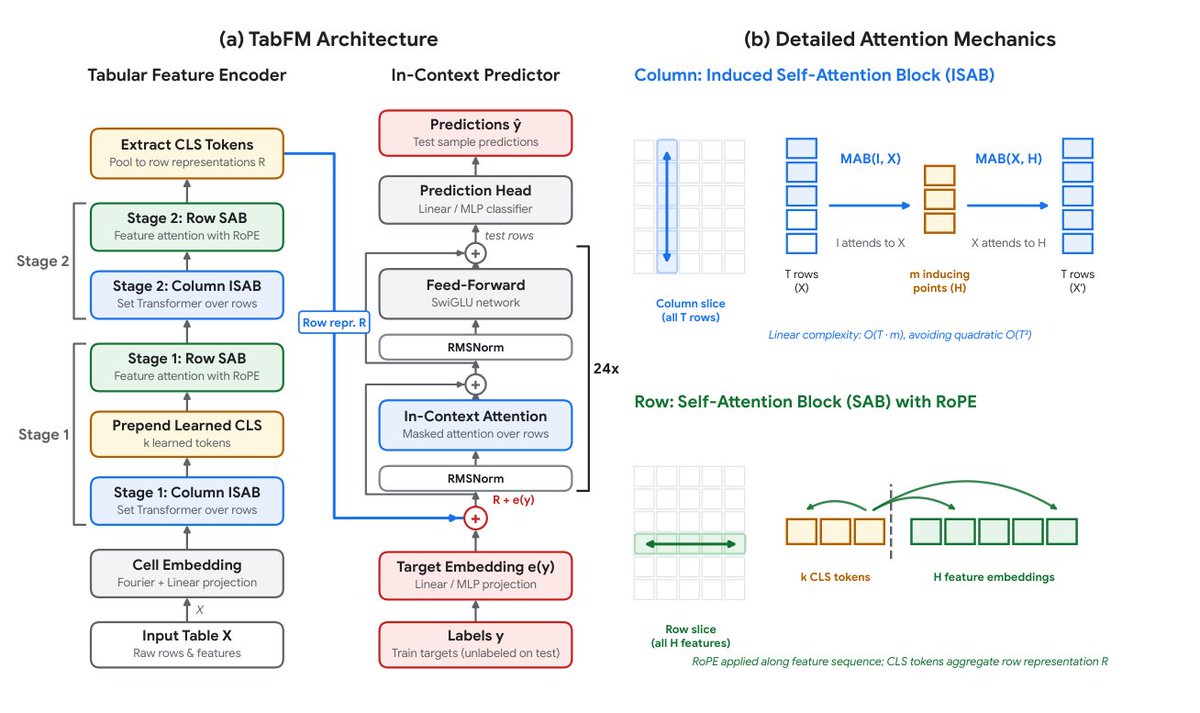
📄 TabFM: A Zero-Shot Foundation Model for Tabular Data
by Weihao Kong, Erez Louidor Ilan et al.
A synthetic-data-trained in-context transformer replaces per-dataset tabular training with single-pass zero-shot prediction on real tables.
Key points:
• Overall TabArena: 1785 Elo, above AutoGluon 1.5 extreme at 1676
• Classification: 1768.6 Elo vs TabPFN-3 1641.9 and AutoGluon 1669.7
• Regression: 2055.2 Elo vs EXAONE-Tabular 1973.1 and TabPFN-3 1866.6
Shows that large tabular models trained purely on synthetic causal tables can transfer zero-shot to real-world datasets at or above tuned AutoML.
🧵 The 3 #ML Repos that shaped Q3 2026
1. deepseek-ai/DeepSpec
Unlike single-method decoding repos, it unifies data prep, multi-GPU training, and evaluation across DSpark, DFlash, Eagle3, and four target-model setups.
2. jaredpalmer/kev
Unlike recent typed-decision repos, it packs many question types into one calibrated, decode-free pass with 2.0× speedup and 4e-6 output parity.
3. Tencent/WeMM-Embedding
Unlike single-modality embedders, it unifies five input types in one space and retains 98.7% image/video performance at 256 dimensions.
Full breakdown ↓
🥈 jaredpalmer/kev
Reads one state once and scores many typed questions in parallel with exact question isolation, outputting probabilities instead of generated text.
Key points:
• Packed vs separate max delta is 3.7e-6, with packed 2.0× faster
• kev-4b gets 0.806 locked-test OOD accuracy and serves in ~1 s on M5
• Supports noul, choice, and score questions with 2-255 options
Growth since tracking: 3 days through Sep 27
⭐ 7.3k (+1.3k) · 🍴 437 (+117) · 🔗 0 (+0)
⭐ https://t.co/So4ZnA7arL
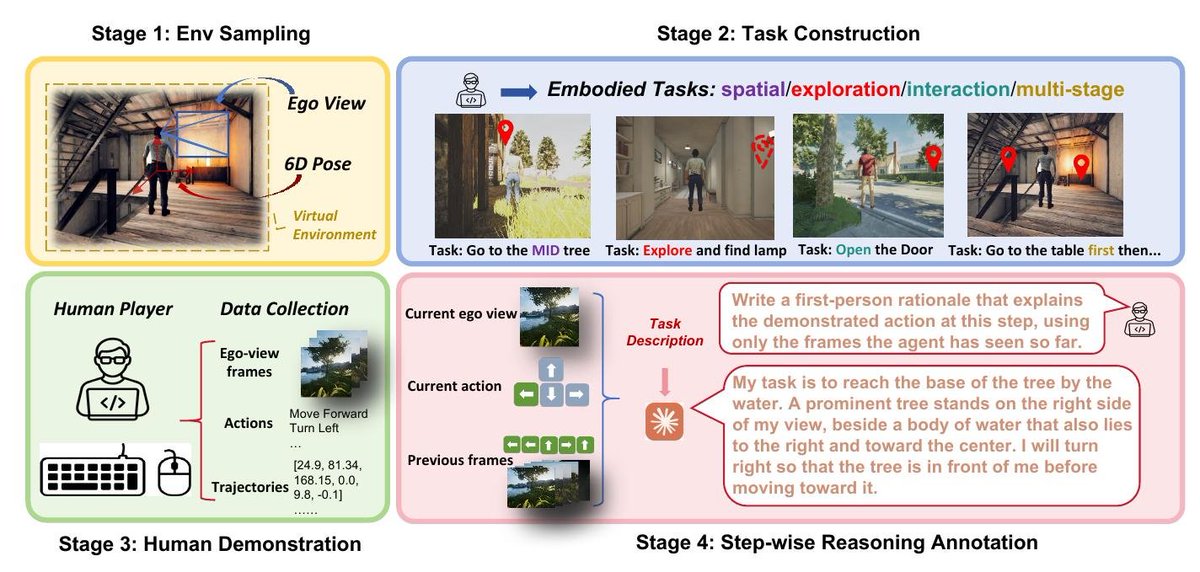
📊 EmbRACE by mxlin043
Contains 3,421 egocentric human demonstrations in 55 environments and a 686-task benchmark in 7 more, for closed-loop embodied navigation/manipulation.
Key points:
• 3,421 dataset tasks + 686 benchmark tasks
• 48,264 rationale-labeled steps; 10,552 benchmark steps
• 62 UE environments total; frames are 640x480; CC-BY-NC-4.0
Useful for training and evaluating embodied agents that must act from egocentric vision and language in closed loop.
📥 76 downloads