BizBench: Unveiling Hidden Challenges in Deploying Long-Horizon Agents for Real-World Business
BizBench evaluates long-horizon agents on 50 realistic payments tasks with 789 policy documents and 601 tools, checking intermediate validity alongside final outcomes.
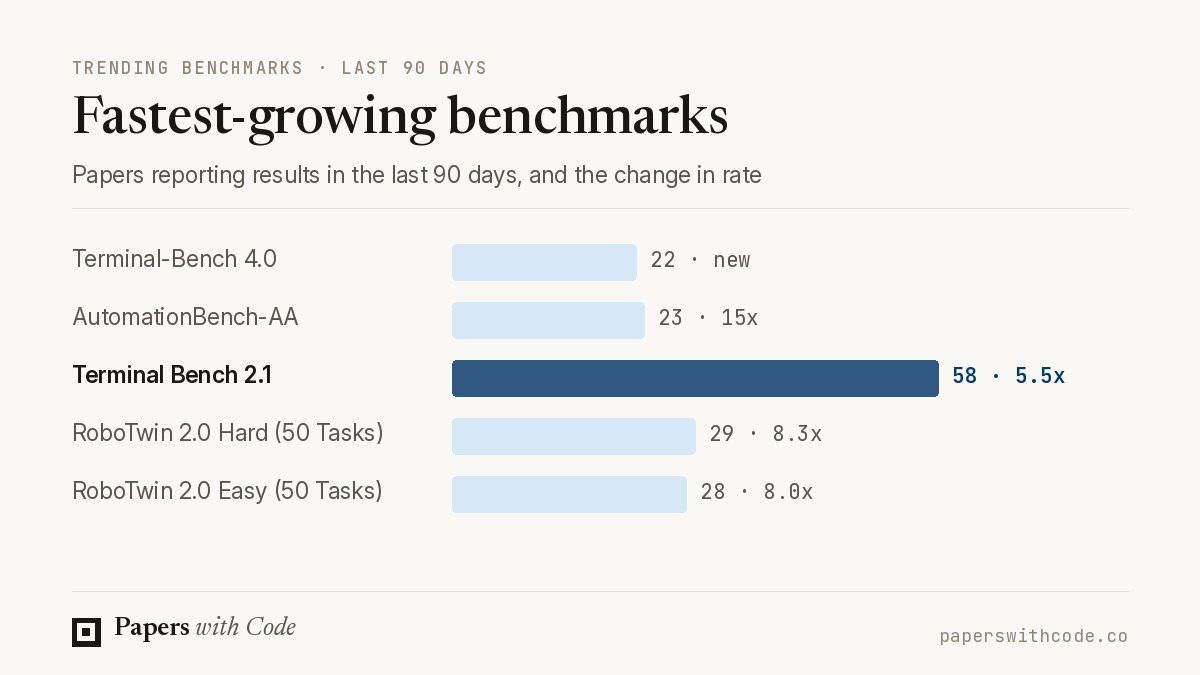
Terminal Bench 2.1 is the fastest-growing benchmark on Papers with Code.
58 papers reported results on it in the last 90 days, up from 21 in the 180 days before.
It updates 26 tasks for more reliable agent evaluation.
DecisionPivot: A Diagnostic Benchmark for Decision Models in LLM Systems
DecisionPivot tests whether decision models handle controlled variations, rank confidence correctly, and calibrate selective predictions—not just answer individual items.
Learning the 4D World through Point Trajectory Forecasting
VPM jointly forecasts multi-view videos and persistent 3D point trajectories, anchoring appearance changes across cameras to shared scene motion.
UltraBERT: Beyond the Limit of BERT Pre-Training
UltraBERT revisits encoder pretraining, finding that extra compute saturates after a few trillion tokens and that masking ratios should differ by task.
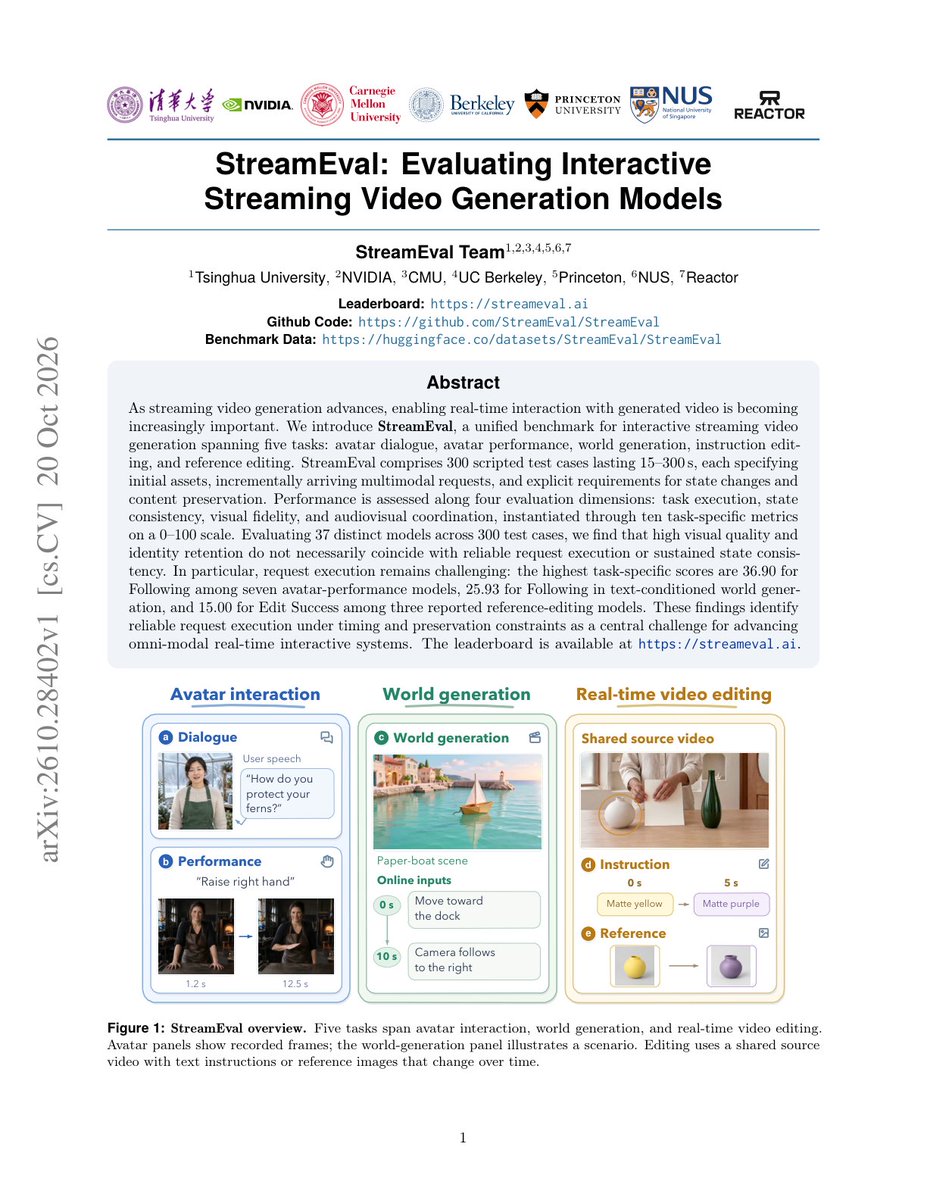
StreamEval: Evaluating Interactive Streaming Video Generation Models
StreamEval benchmarks interactive streaming video across five tasks, measuring execution, state consistency, visual fidelity, and audiovisual coordination.
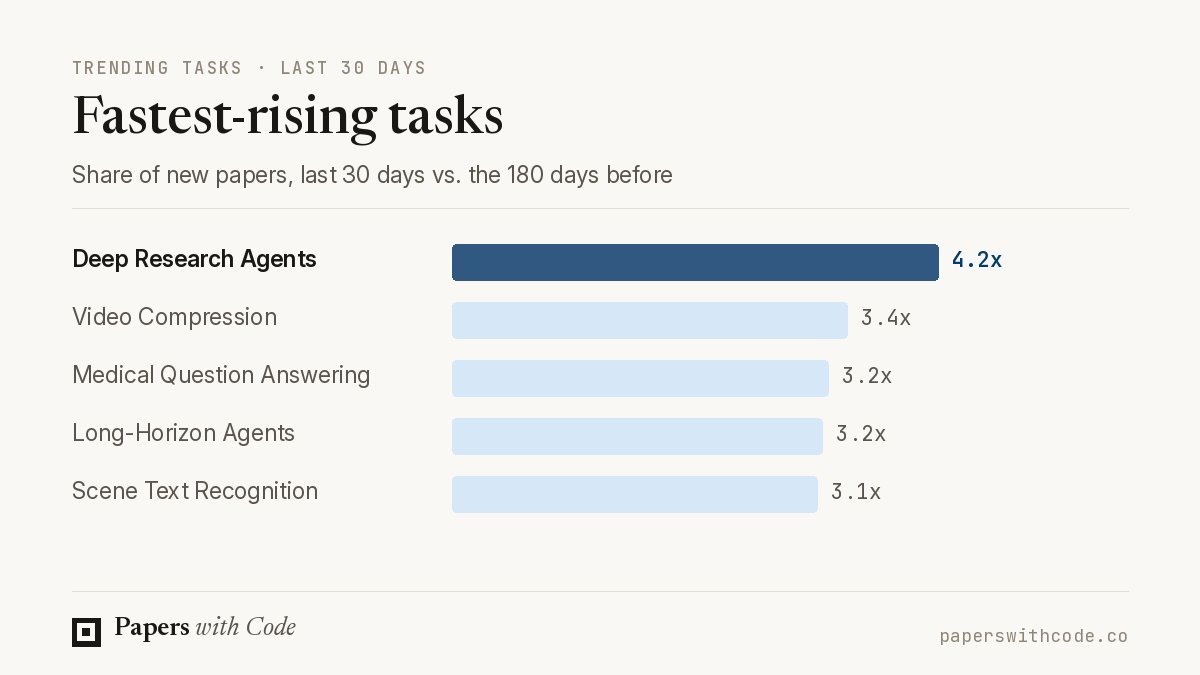
Deep Research Agents is the fastest-rising task on Papers with Code.
43 papers in the last 30 days, 4.2x its share of new papers in the 180 days before.