Just found a site archiving the full files of ChatGPT/Codex plugin submissions, downloadable by anyone 👀 https://t.co/bnzlnuQ6R0 @mxstbr@OpenAIDevs is that intended?
@manufact Wild to see my DNS Inspector on the top developer tools leaderboard. Built it to scratch my own itch, and now it's up there. Pretty cool 🙌
https://t.co/1nJHXnOhBC
Made the previously paid article "Becoming a better writer" free.
I see too many devs writing low quality slop with AI. Hopefully this helps those of you who want to share more of your own experiences, using your own words - we need more of these!
https://t.co/nk5OzsS93n
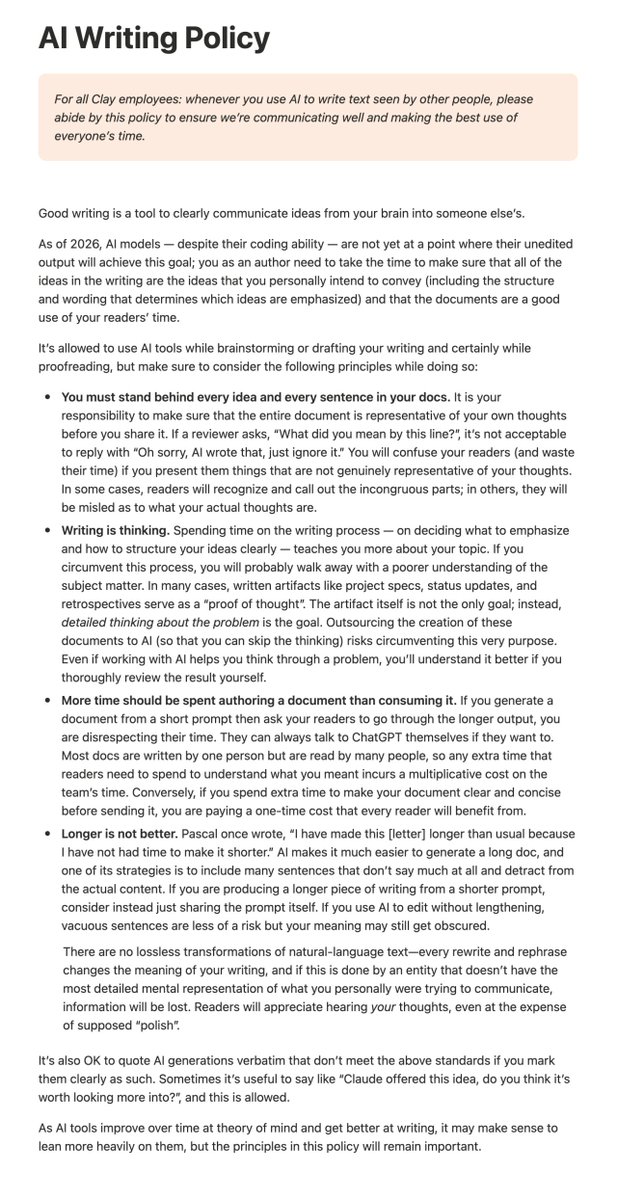
We instituted an official AI Writing Policy at @Clay.
Massive thanks to @sophiebits on our engineering team who wrote this.
Originally this was just for eng, but other teams found it so helpful we expanded it company-wide.
Here are the four guiding principles:
1. You must stand behind every idea and sentence
It is your responsibility to make sure that the entire document is representative of your own thoughts before you share it.
2. Writing is thinking
Spending time on the writing process teaches you more about your topic. If you circumvent this process, you will walk away with a poorer understanding of the subject matter.
3. More time should be spent writing a document than consuming it
If you generate a document from a short prompt then ask your readers to go through the longer output, you are disrespecting their time. They can talk to ChatGPT themselves if they want to.
4. Longer is not better
AI makes it easy to generate long docs, and it loves padding them with sentences that say nothing. If you're producing docs from a short prompt, consider just sharing the prompt.
You can read (and borrow) the full policy below. Hopefully we all communicate a bit more clearly now :)
The "whiteboard defense:" I should be able to pull you aside at any moment and ask you to explain any customer-facing system you've shipped. You should be able to clearly explain how it works and defend the decisions you made. This is my benchmark for responsible AI usage.
I don't expect line-level familiarity with the code. I don't care if you remember the exact function name or implementation detail. You may not even know it. I don't care.
But if I ask "why did you do X instead of Y?", "what happens if this actor behaves maliciously?", "what data structure did you use here and why?", or "where does this fail?" you should be able to answer confidently.
For PoCs, demos, experiments, whatever: I don't care. Generate 100% of it and understand none of it. Speed over quality every time in those specific scenarios.
But if you're shipping customer-facing work, you can't be shipping things you don't understand at a high level.
I’m excited to finally announce the newest edition my Stanford course 𝗧𝗵𝗲 𝗠𝗼𝗱𝗲𝗿𝗻 𝗦𝗼𝗳𝘁𝘄𝗮𝗿𝗲 𝗗𝗲𝘃𝗲𝗹𝗼𝗽𝗲𝗿. It has been 9 months in the making.
Last November, with the release of Claude Opus 4.5, coding agents experienced a step function improvement in capability. We all felt it. The LLMs were more powerful, could reason for longer, solve harder tasks.
This year’s iteration of my course reflects the 2026 metamorphosis of software engineering.
My core belief is simple: AI-native developers of the LLM era are going to become the most important members of any software organization. I have designed my course to train this next generation of engineers.
𝗪𝗵𝗮𝘁’𝘀 𝗱𝗶𝗳𝗳𝗲𝗿𝗲𝗻𝘁 𝘁𝗵𝗶𝘀 𝘁𝗶𝗺𝗲 𝗮𝗿𝗼𝘂𝗻𝗱
First, 85% of my Fall 2025 class material is being thrown out. The Fall 2026 syllabus reflects the core capabilities AI-native engineers must have: agent skills, advanced context engineering, MCP portals, agent-ready codebase principles, agentic code review, security, parallelizing background agents, software factories, and more.
Second, I am going to teach my students how to have software taste. Every student will be required to ship pull requests to production-grade, real-world codebases. The course is collaborating with the top open-source AI repos who will offer support and mentorship to students on how to meaningfully contribute to their projects.
This has never been done before in any university course so I am incredibly grateful to our OSS Partners: @browserbase, @HeyGen, @CopilotKit, @semgrep, @OpenHandsDev, @milvusio, @marimo_io, Pi, @crewAIInc, @warpdotdev, @vercel, @cmux, @arizeai, @UnslothAI, and @anyscalecompute.
𝗪𝗵𝗮𝘁’𝘀 𝘀𝘁𝗮𝘆𝗶𝗻𝗴 𝘁𝗵𝗲 𝘀𝗮𝗺𝗲
I’m fortunate to again have AI software engineering leaders and founders as guest speakers to share their learnings from building top coding agent products. Thank you to @leerob from @cursor_ai, @bcherny of @claudeai code, @EnoReyes of @FactoryAI, @silasalberti of @cognition, @0xine of @semgrep, Rajesh Bhatia of @Cloudflare , @amasad of @Replit, and @eladgil.
All resources will be available online. All classes will be available to the public.
9/22 on Stanford campus. See you in class.
https://t.co/wTokHyUMsz
@ITAAirways avete un problema sulle comunicazioni via e-mail. Ho ricevuto il 27 agosto alle 17:48, la notifica del gate d'imbarco del volo del 25 agosto alle 9:35
Spent my first 15 years as a dev ripping ids out of the DOM, locking down APIs, slapping on bot protection, captchas, rate limits per IP — you name it, all to keep crawlers out. Probably gonna spend the next 15 tearing all of it back down, starting with going all in on #WebMCP
"Monolith" is a deployment strategy, not an architecture. All it tells you is that you deploy the entire system in one go. It tells you nothing about the structure of that system.
"Microservice" is also a deployment strategy, not an architecture. Microservices allow you to deploy individual components (that's the architecture—autonomous components) without deploying the rest of the system at the same time.
My heuristic is that any diff an agent generates over ~1500 lines is too big and is indicative that the problem needs to be decomposed. This is my general pattern now for feature work:
1. Try to implement the whole feature, loosely guided. I call this the "draw the owl" prompt in reference to the meme. Expect garbage, you're going to get garbage.
2. If the diff is less than 1500 lines, review it and iterate normally. If the diff is more than 1500 lines, prompt the agent to decompose the problem into atomic, incremental, reviewable tasks. Simultaneously, do this yourself.
3. Agents will very often make these tasks way too specific to the shape they solved. You need to massage it into the right general shape. Do that.
4. Kick off new agents to work on those incremental things (as parallelized as possible). Apply the same rules.
5. At a certain, point, repeat the "draw the owl" prompt. At some point, you will get beneath your review-ability threshold.
This has been producing consistently high quality, maintainable, reviewable chunks of code that have a good handoff to either merge as-is or human refinement.
And with the latest frontier models at xhigh thinking, these are all slow enough that you can usually have multiple going concurrently while you are actively reviewing others or working on your own tasks.
HITL (human-in-the-loop) agents are still super important, especially for feature work. Features touch the human boundary in terms of UI, API, etc. And net new stuff can introduce pathologies in the architecture that violate desired invariants (these should be represented in specs or tests but we aren't perfect!).
I know a lot of the leading edge agentic discourse is about "loops" and agents driving agents continuously. I do some of that (will report on that later). But, in terms of raw daily get-shit-done type of work, this is my most rewarding pattern at the moment.