OPPO × Phala published a joint paper on Kubernetes Pod-level remote attestation for confidential AI.
Goal: prove the hardware, container image, and Pod identity before sensitive data enters the workload.
https://t.co/jQjC6DFsS0
Catch Phala co-founder & CTO @bgmshana at @sgl_project Summit 2026 this Friday in San Francisco.
“Production Private Inference Using SGLang and dstack”
Nov 13 · 1:45–2:00 PM PT
Decode Room · Fort Mason
https://t.co/d7EBybpMBO
Kimi K3.1 Pro from @Kimi_Moonshot is live on Phala with TEE-backed private inference.
Moonshot AI's first K3.1 model brings native multimodal reasoning to long-horizon coding, 3D creation, financial research, and agentic knowledge work.
https://t.co/Cq5yWBWUsS
Personal AI needs memory. That memory should stay private.
Proud to power @LighthouseWeb3’s Private Memory with Phala TEEs, so AI agents can work with private memories inside hardware-attested enclaves.
Now live on Robinhood Chain. 🌿
Private Memory is now live on Lighthouse, powered by @PhalaNetwork TEEs and live on @RobinhoodCrypto 🌿
Your AI should remember everything you want it to, without compromising your privacy.
Lighthouse Memory now supports encrypted, private memories.
Here’s how we protect your memories:
• Private by design: Memories remain encrypted, with decryption happening inside secure enclaves.
• Distributed key security: Encryption keys are split across independent key nodes, eliminating a single point of key compromise.
• Hardware-attested access: Key shares are only released to enclaves whose hardware attestation matches an approved build.
• User-controlled memory: Only authorized users can view decrypted memories, while AI agents can securely work with private data inside trusted environments.
• Live on Robinhood Chain, bringing private, verifiable memory infrastructure to the onchain AI ecosystem.
Your memories. Your privacy. Your control.
AI memory shouldn’t come at the cost of privacy.
The future of AI memory is persistent, verifiable, and private.
Private Memory is now live on Lighthouse, powered by @PhalaNetwork TEEs and live on @RobinhoodCrypto 🌿
Your AI should remember everything you want it to, without compromising your privacy.
Lighthouse Memory now supports encrypted, private memories.
Here’s how we protect your memories:
• Private by design: Memories remain encrypted, with decryption happening inside secure enclaves.
• Distributed key security: Encryption keys are split across independent key nodes, eliminating a single point of key compromise.
• Hardware-attested access: Key shares are only released to enclaves whose hardware attestation matches an approved build.
• User-controlled memory: Only authorized users can view decrypted memories, while AI agents can securely work with private data inside trusted environments.
• Live on Robinhood Chain, bringing private, verifiable memory infrastructure to the onchain AI ecosystem.
Your memories. Your privacy. Your control.
AI memory shouldn’t come at the cost of privacy.
The future of AI memory is persistent, verifiable, and private.
Live on Sirius today:
→ Sirius API: call your private model from your app or agent
→ Uploads up to 1 GB, encrypted in your browser
Every model trains in a Confidential VM on @PhalaNetwork Cloud. No one can open it. Not even us.
Built on @virtuals_io
https://t.co/pVOoJ5dOU7
Voxtral Small 24B is live on Phala—served inside a TDX-attested GPU TEE.
Private, verifiable inference for audio transcription.
https://t.co/mZNmlfzQMf
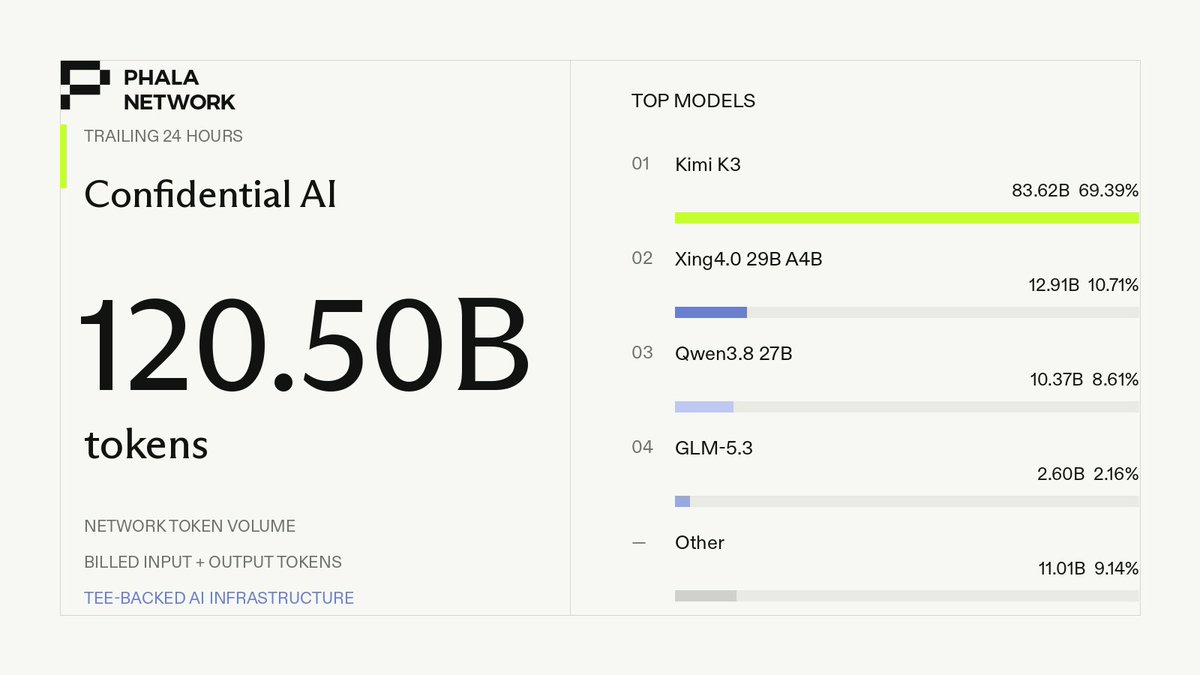
Phala Confidential AI: 120.50 billion tokens over the past 24 hours.
Top models:
Kimi K3 69.39%
Xing4.0 29B A4B 10.71%
Qwen3.8 27B 8.61%
https://t.co/eHSPzOFiwk
TEE-backed AI infrastructure.
Congrats on the launch, @proofableme! 👏 Agents need verifiable identity, ownership, and authority as they act across apps. Proud to be part of what you’re building.
Billions of agents are coming online.
Nobody can tell what's real.
Introducing Proofable.
It lets people and AI agents carry identity, ownership, and authority anywhere.
Proof is the missing layer.
Make it Proofable.
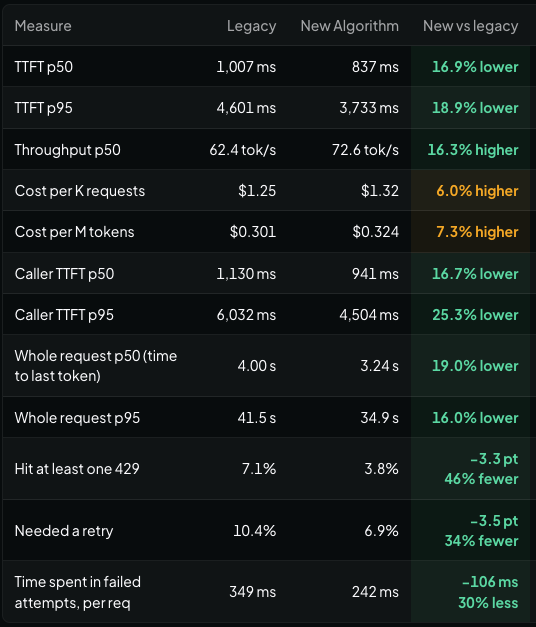
As inference providers multiply, price matters. Model service quality still comes first.
OpenRouter is raising the bar by rewarding inference that is fast, reliable, and cost-efficient. Salute 🫡
We just shipped our biggest improvement to our provider router since the founding of OpenRouter.
Before, we prioritized mostly based on price. The new router now rewards the best quality inference for the actual cost of a request, so requests stay cheap but are also fast and reliable.
Providers that deliver more value automatically win more traffic, so every provider has a reason to keep improving. And every time a provider gets better, so does your inference on OpenRouter.
Private AI should be as easy to use as any other API. Together with @foundry_fi, we're bringing Phala's confidential GPU compute to builders and agents through an OpenAI-compatible API, with payments in USDF.
Phala Confidential AI: 186.42 billion tokens over the past 24 hours.
Top models:
GLM-5.3 Flash 69.41%
deepseek-v4.1-flash-1017 7.61%
xing4.0-29b-a4b 5.50%
https://t.co/e1fj3fVSlJ
TEE-backed AI infrastructure.
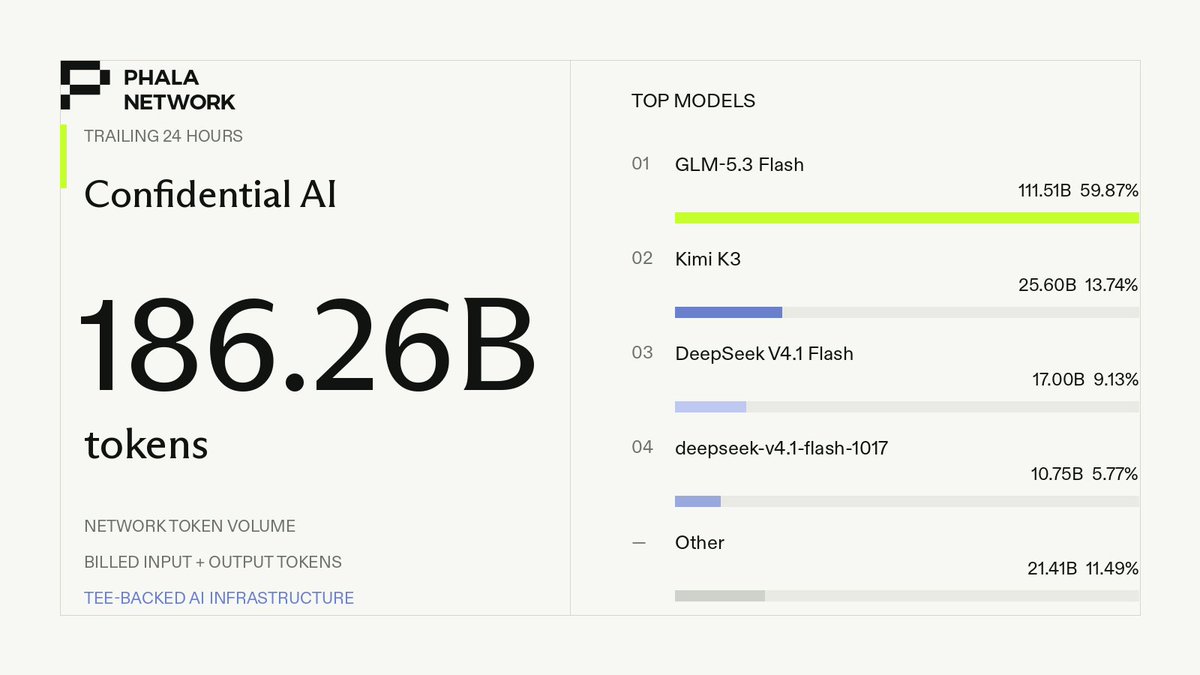
Phala Confidential AI: 186.26 billion tokens over the past 24 hours.
Top models:
GLM-5.3 Flash 59.87%
Kimi K3 13.74%
DeepSeek V4.1 Flash 9.13%
https://t.co/e1fj3fVSlJ
TEE-backed AI infrastructure.
DeepSeek V4.1 Flash 1017 is live on Phala—served inside a TDX-attested GPU TEE.
Private, verifiable inference for long-horizon agents, visual understanding, reasoning.
https://t.co/w66K7vwq0h
Phala Confidential AI: 81.33 billion tokens over the past 24 hours.
Top models:
DeepSeek V4.1 Flash 56.30%
xing4.0-29b-a4b 12.22%
qwen3.8-27b 9.39%
https://t.co/sV8F6voMwO
TEE-backed AI infrastructure.