We are shipping today our desktop app with special capabilities on finding and fixing vulnerabilities. This is super useful and super exciting. Le chonk is amazing in cyber defense and you should use it
Vibe is AWESOME on chonky codebases and fixing vulnerabilities with precision.
Vibe with Le Chonk score highest among open models on FrontierCode and Terminal-Bench, and take on security work other agents refuse.
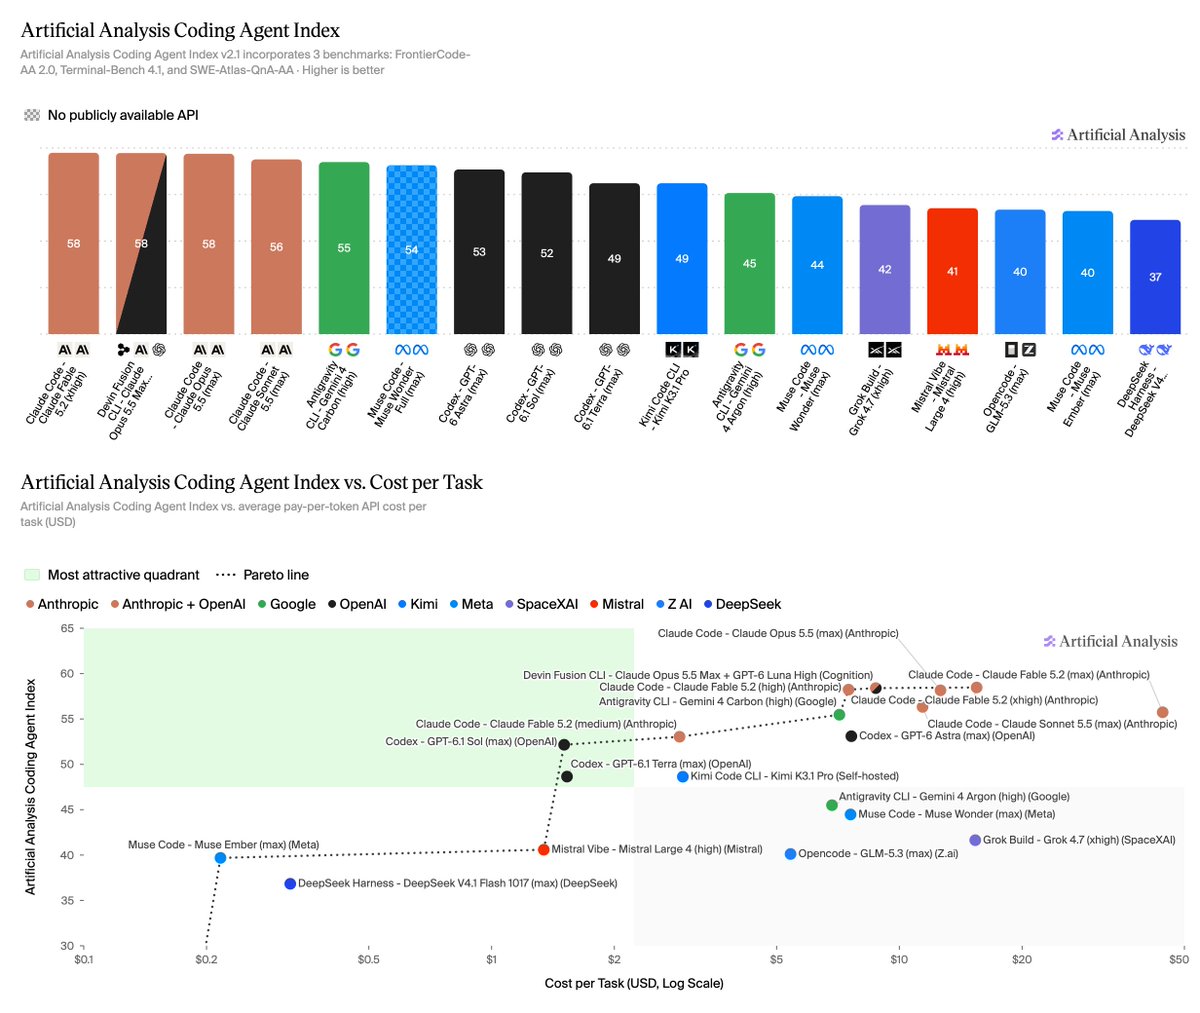
ML4 and vibe with strong performance on AA new coding agents index. Great OSS combo with a very attractive cost per task profile. We are at work and things are going to get even more interesting 👀
Announcing Artificial Analysis Coding Agent Index v2.1, upgrading FrontierCode and Terminal-Bench. Claude Fable 5.2 and Claude Opus 5.5 share the lead at 58
The Coding Agent Index measures models in agent harnesses; v2.1 of the Index upgrades FrontierCode from 1.1 to 2.0 and Terminal-Bench from 4.0 to 4.1.
Upgraded:
➤ FrontierCode-AA 2.0 (replacing FrontierCode v1.1): our implementation of Cognition's FrontierCode 2.0, comprising 132 real-world coding tasks graded on whether a repository maintainer would merge the agent's change
➤ Terminal-Bench 4.1 (replacing Terminal-Bench 4.0): the same 66 tasks, scored with updated verifiers that improve reliability and resistance to reward hacking
Staying in the Index: SWE-Atlas-QnA-AA
Key results:
➤ Claude Fable 5.2 and Claude Opus 5.5 share the lead at 58: Claude Fable 5.2 scores 58 at both xhigh and high in Claude Code. Claude Opus 5.5 (max) scores 58 in Claude Code and, paired with GPT-6 Luna High, in Cognition's multi-model harness Devin Fusion CLI. Claude Fable 5.2 (max) scores 56 as more of its attempts hit task time limits. Claude Sonnet 5.5 (max, 56) in Claude Code and Gemini 4 Carbon (high, 55) in Antigravity CLI follow
➤ Index scores are lower in v2.1, driven by the upgrade to FrontierCode-AA 2.0: models score lower by 5 points on average. Codex with GPT-6.1 Terra (max) is the only configuration which didn’t fall between versions, sitting within 1 point of its prior score
➤ Cost per task varies ~30x among configurations scoring 48+: from $1.51 for Codex with GPT-6.1 Sol (max, 52) to $44.22 for Claude Code with Claude Fable 5.2 (max, 56)
Watching @SpaceX , seeing the progress in AI. It’s the first time in human history someone can say- I will probably die at the age of 300 and it won’t be on plant earth.
MISTRAL AI 🔥: Vibe is being prepared to get a new Code section, likely mirroring functionality of Vibe CLI, and a new Apps section.
> It is still unclear whether we will get a desktop app as well, but it would be really cool. Purely referencing the UI that mirrors the Claude app (Which is about to change soon, btw)
> A new Apps section is marked as "Work in progress" and is likely to be a version of AI-powered artifacts that can be deployed and shared.
Only Le Chaton Fat is remaining 👀