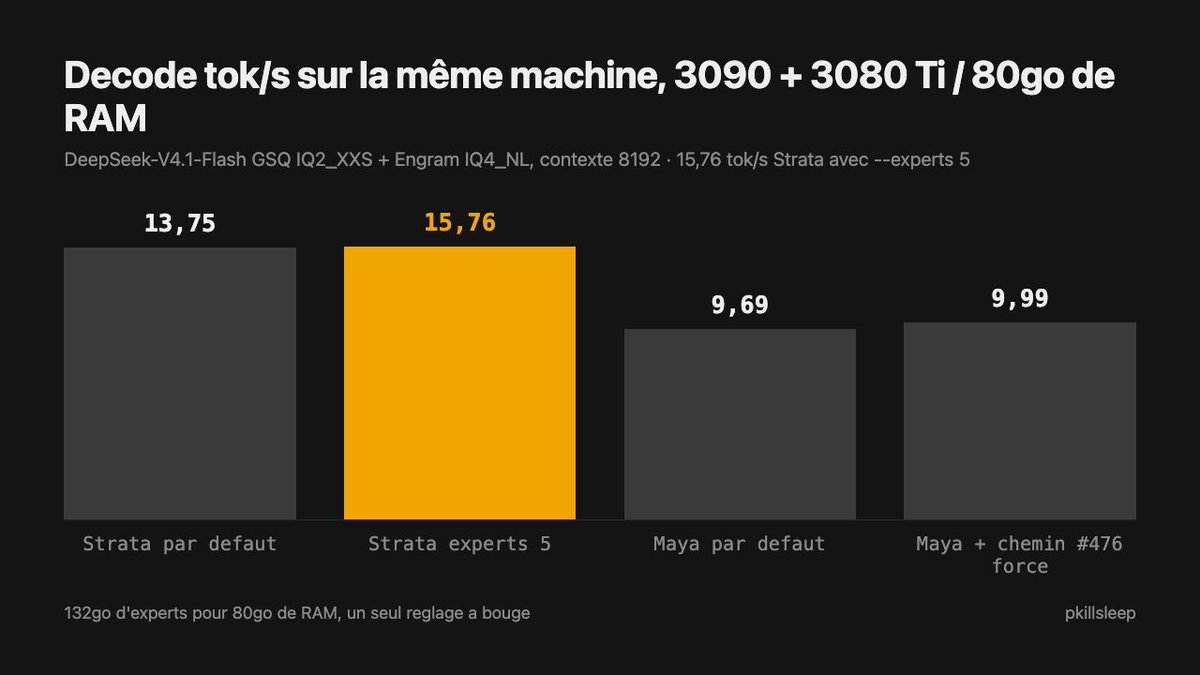
je viens de tester deepseek v4.1 flash IQ2_XXS chez moi, sur une 3090 et une 3080 12gb + 80gb de ram avec Strata
les experts du modèle pèsent 132go, sur mes 80gb de ram ça rentre pas
un seul réglage a permit d'améliorer le decode : passer de 6 à 5 experts 13,75 -> 15,76 tok/s (+14,6%)
j'ai tenté d'autres trucs, genre dspark etc, mais ça n'a rien donné ou fait perdre en perf
j'ai 64gb de ram qui arrivent dans la semaine pour passer à 128gb de ram, ça devrait aider
face au moteur Maya, il semblerait que Strata soit plus performant pour Deepseek v4.1 flash
mon setup du moment : qwen 3.8 flash next IQ3_S, un 125B quantifié qui tourne sur ma 3090 et ma 3080 12gb, grâce au moteur Strata en local
mes deux agents se relaient sur des conversations de 139K tokens, et à chaque relais le moteur relisait tout : 77 s
le coupable : le plancher de RAM que le service se réserve, baissé d'un cran et le retour tombe à 0,4 s
sur 34 h de logs, 37% de mon temps de prefill partait à relire des conversations déjà lues
toujours 100+ tok/s en decode et 1700 tok/s prefill
@Alex_Car12 ça doit être possible de run le IQ2 ou IQ3 dans strata avec moins de VRAM et 64gb vram
j'ai essayé brièvement le abliterated GSQ-RCO de SC117 et il tourne bien
Available now: NVIDIA Nemotron 3.5 Bolt E4B 4GB ⚡️
Our newest small open model is built for local assistants, interactive characters and robots that can carry on a conversation and use tools to get things done.
Watch Reachy Mini chat and move, with Bolt handling conversation and NVIDIA Cosmos handling vision. Both models run locally on Jetson Orin Nano 8GB.
Learn more: https://t.co/B8ODaWMn0O
je viens de tenter ça sur ma 3090 et ma 3080 et j'ai environ 2 à 3% d'amélioration sur le prefill
à noter que les cartes sont underclock et underwatt, ce qui doit très probablement rogner le gain
quoi qu'il en soit, un gain reste un gain, d'autant plus qu'il augmente avec le contexte
NVIDIA sold millions of 3090s with 50% of the tensor speed switched off. Not missing. Switched off.
1 kernel module flips it to full, and my BF16 tensor pipe went from 82 to 155 TFLOPS. Nothing else changed on the cards, and the outputs match the stock run byte for byte.
All so the gaming card wouldnt eat into workstation sales. Every 3090 owner ran at 50% for 6 years, so a pro card could look worth the price. Fine, its their business model.
And LLMs are the least interesting place for this. Decode waits on memory, and my engine runs its experts in int8. Still +10% on prefill.
The models that live on BF16 tensor math are everything else. Qwen Image 2.1 and FLUX 3 Klein, where every diffusion step is big matmuls. MiniMax H3, which takes 4 to 7 minutes on my cards. Music and speech models. And training, every LoRA anyone ever trained on a 3090 went through exactly the path that was cut.
Thats what I measure next. This is only the start.