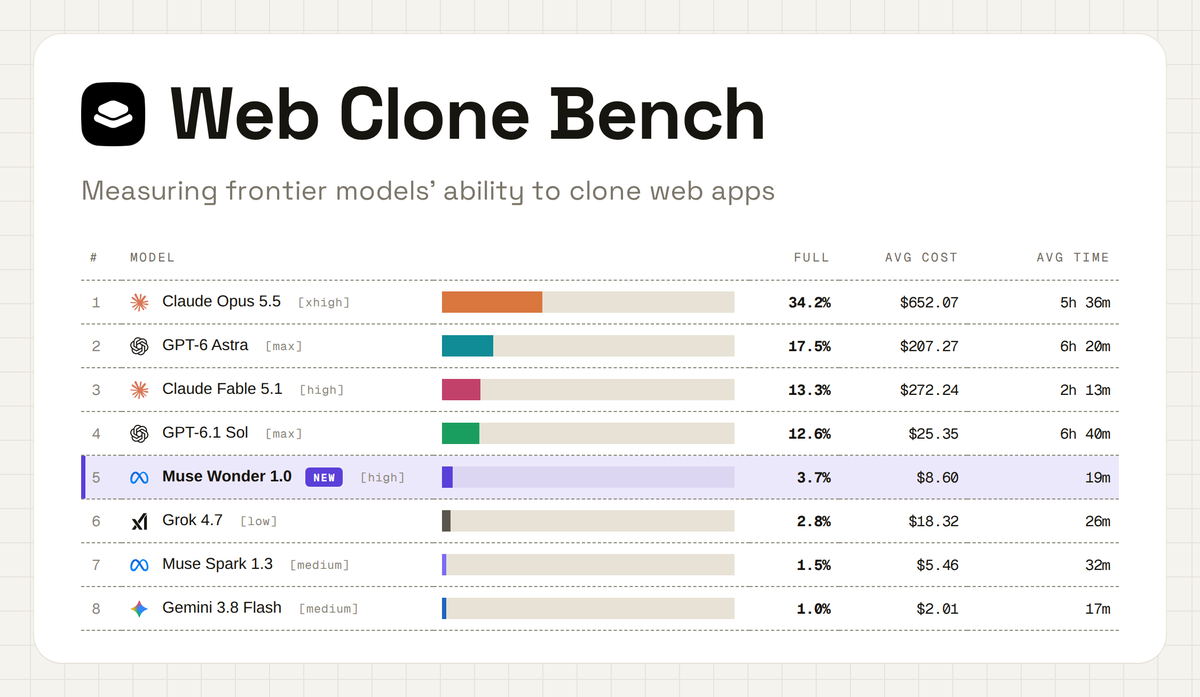
Muse Wonder scores 3.7% on Web Clone Bench
A big jump from Spark 1.3 but still unable to make significant progress on long horizon coding/computer-use tasks.
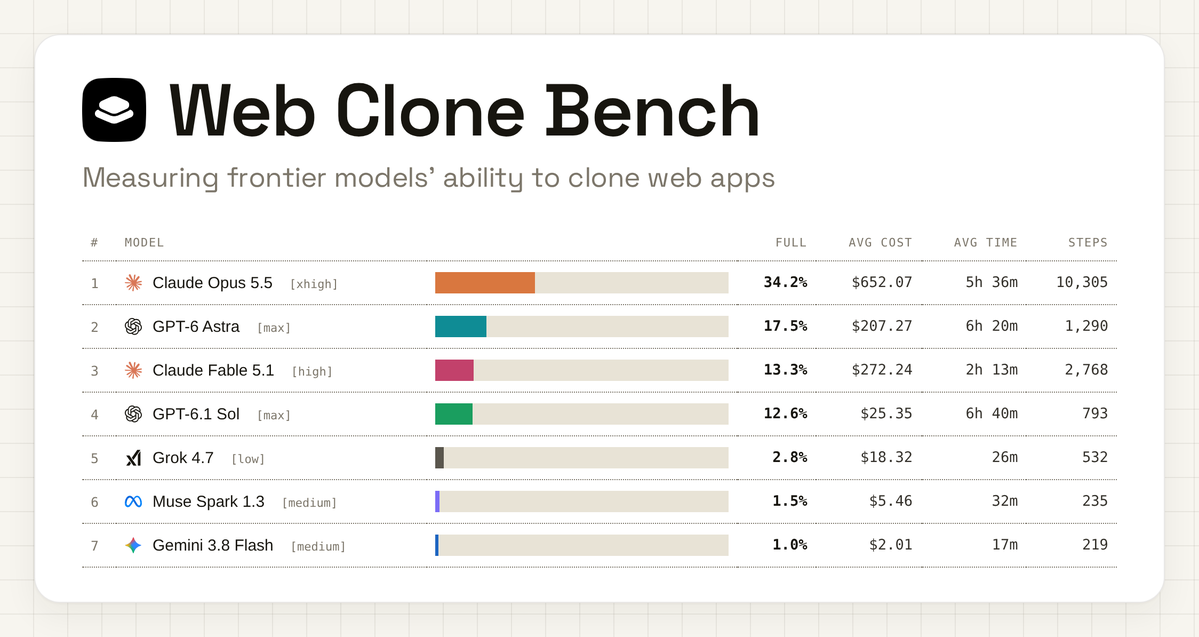
Today we're launching WebCloneBench: a benchmark which measures a model's ability to explore, copy, build and test various web apps.
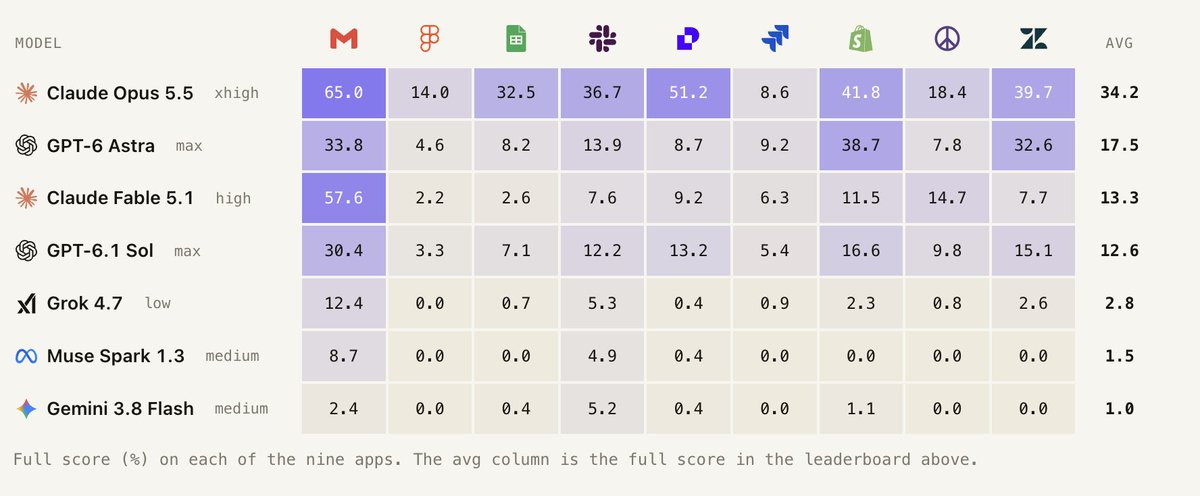
For each task, we give the model a reference site from one of Gmail, Google Sheets, Jira, DocuSign, Shopify Admin, Craigslist, Figma, Slack and Zendesk. It is instructed to build a fully feature-complete clone of every part of the application with an 8 hour time limit.
Today's LLMs are approaching superhuman performance on well-defined coding problems, but still struggle at efficient exploration and experimentation. Left to themselves, models struggle with exploring and iterating and end up making shallow judgment calls.
This benchmark not only measures a model's long horizon coding abilities, but more importantly, the ability for models to use their intuition to efficiently test and explore the reference web app.