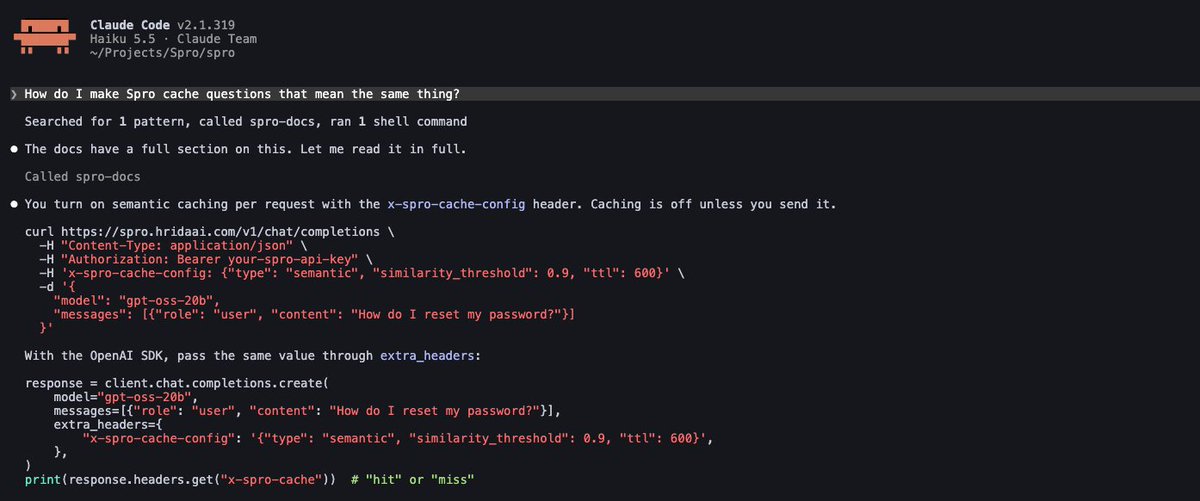
Asked Claude Code: "How do I make Spro cache questions that mean the same thing?"
It didn't guess. It called the Spro docs MCP, read the caching page in full and came back with the exact header, the 0.9 default threshold and a working curl.
Same question, no tab-hopping.
https://t.co/usIyCXDQX3
We just launched the 𝗦𝗽𝗿𝗼 𝗱𝗼𝗰𝘀 𝗠𝗖𝗣 𝘀𝗲𝗿𝘃𝗲𝗿. 🚀
Documentation has a problem. You open the docs for one answer. Then you click a link, then another, then another. Ten tabs later you've forgotten what you came for. And when you ask your AI agent instead, it answers confidently from training data, with a detail that's slightly off or something that changed last month.
The Spro docs MCP server fixes that.
Connect it once, and your agent can search and read the current Spro docs directly, inside Claude Code, Cursor, Codex CLI, VS Code, Claude Desktop and any client that supports remote MCP.
What you get:
> Current answers. It reads the same docs the website publishes, so details track the latest features, tiers and limits.
> Exact details. The agent reads the full page, so answers come from the source, not a guess.
> No context switching. Ask while you write code.
> Safe by design. It's read-only, needs no API key and can't change your account or data.
A few things you can ask your agent once it's connected:
> "How do I make Spro cache semantically similar questions?"
> "What does Zero Data Retention store, and what doesn't it?"
> "Show me how to send a fallback chain of models through Spro."
> "Which alerts should I turn on for a new workspace?"
Setup instructions for every client are in the docs:
https://t.co/usIyCXDj7v
Spro is an AI gateway and security platform: one OpenAI-compatible API for 350+ models, with routing, guardrails, caching and observability built in. Making the docs agent-readable is one more step toward making it easy to build with.
#MCP #AIGateway #DeveloperTools #AIEngineering
One leaked LLM API key. $82,000 in 48 hours. 😬
Stolen AI keys are now their own attack category, and a key with no spend cap has no ceiling.
On SPRO you can set request, token and cost limits at the gateway, including on your own provider keys (BYOK), so a leak hits a cap and not your card.
Cap first. Monitor second.
spro[dot]hridaai[dot]com
Your AI stack grows. So do your blind spots.
Multiple providers. Hundreds of models. Scattered usage data. Unpredictable costs. No clear picture of what's failing or why.
You shouldn't need five dashboards to understand your AI infrastructure.
SPRO brings model routing, usage analytics, latency, error tracking, cost visibility, and guardrails into one place.
One API. Hundreds of models. Full visibility.
spro[dot]hridaai[dot]com
🚀 Claude Haiku 5.5 is now live on SPRO.
Anthropic’s latest Haiku is built for fast, high-volume, cost-sensitive AI workloads, while bringing stronger capabilities for coding, computer use, and agentic applications.
→ 1M context
→ Stronger coding & computer use
→ Multimodal capabilities
→ $0.10/M input · $0.50/M output
Access it through the same OpenAI-compatible API.
One API. 350+ models. One secure gateway.
Try it on SPRO: claude-haiku-5.5
#Claude #ClaudeHaiku #Anthropic #AI #LLM #GenAI #AIAgents #SPRO #HridaAI
@Google just shipped a frontier model and limited it to trusted testers first.
Everyone else still needs a control layer between the app and the model.
That's SPRO: one API, Multi model routing and Guardrails enabled by default. Not just another chat app. https://t.co/AJ5ZY0VTpW
Powerful AI needs clear rules.
Guardrails are the rulebook for AI - protecting sensitive data, blocking prompt injection, enforcing policies, and stopping unsafe actions before they happen.
Here’s why enterprises need them. 👇 https://t.co/Wwi7w4DEHO
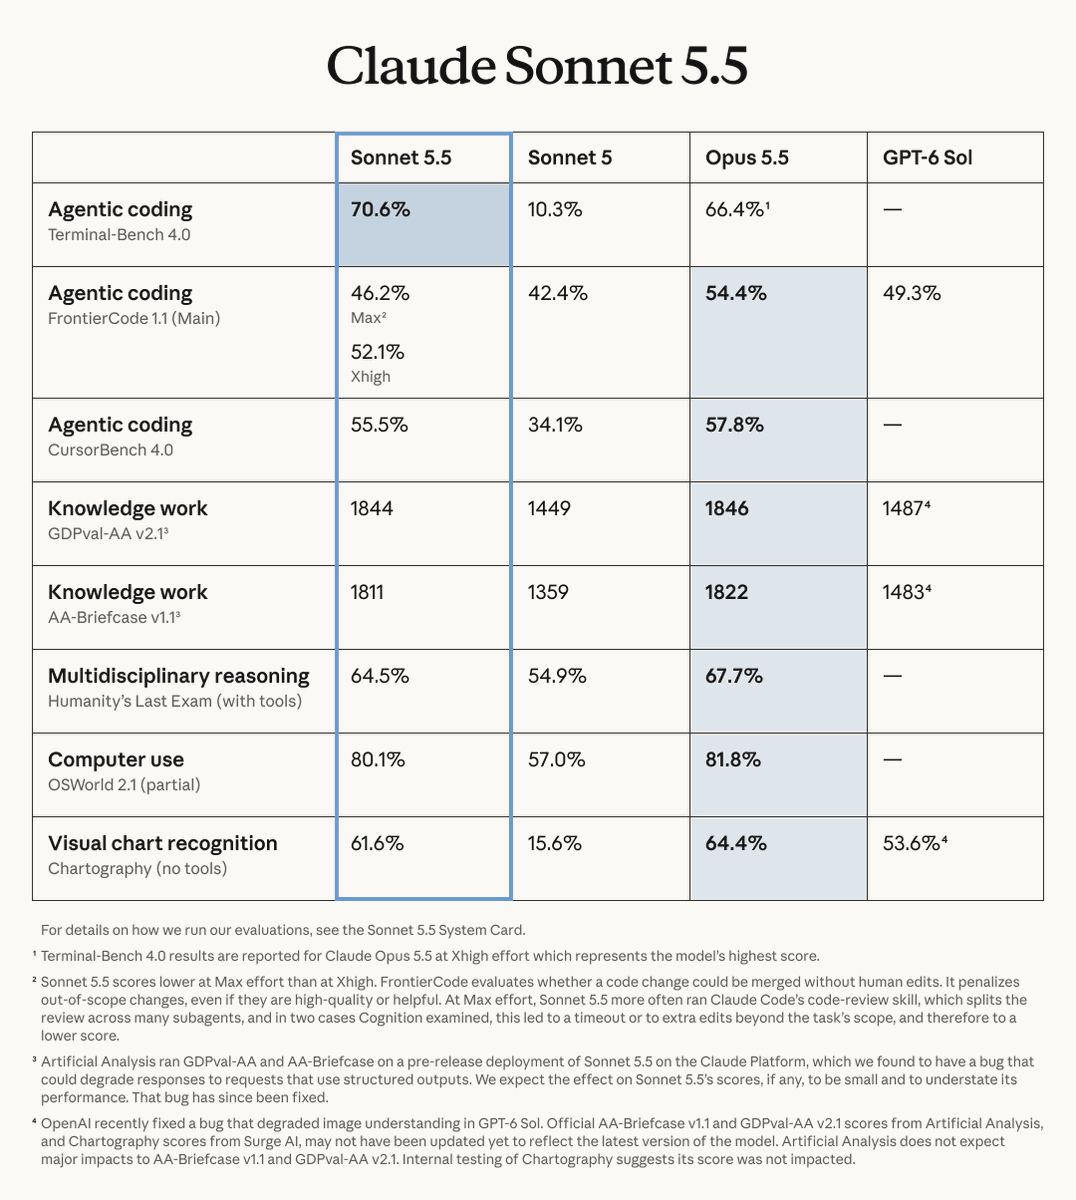
𝗦𝗼𝗻𝗻𝗲𝘁 5.5 𝗹𝗼𝗼𝗸𝘀 𝗰𝗵𝗲𝗮𝗽𝗲𝗿. 𝗨𝗻𝘁𝗶𝗹 𝘆𝗼𝘂 𝗮𝗰𝘁𝘂𝗮𝗹𝗹𝘆 𝗺𝗮𝗸𝗲 𝗶𝘁 𝘄𝗼𝗿𝗸.
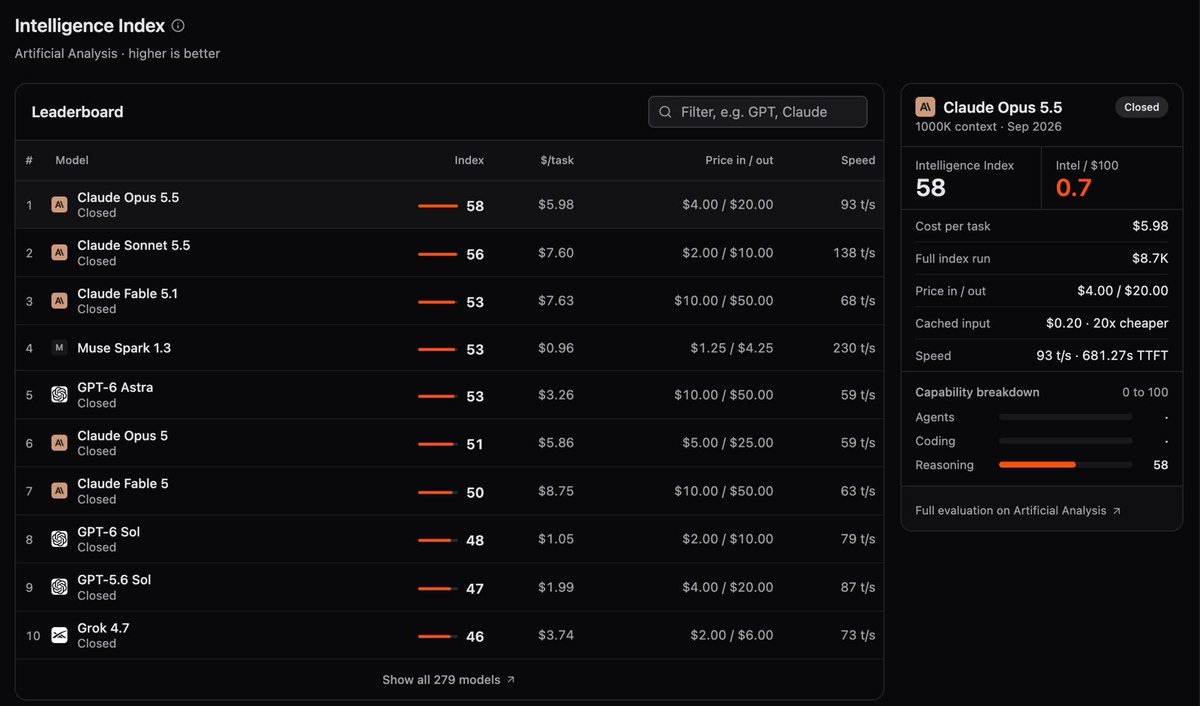
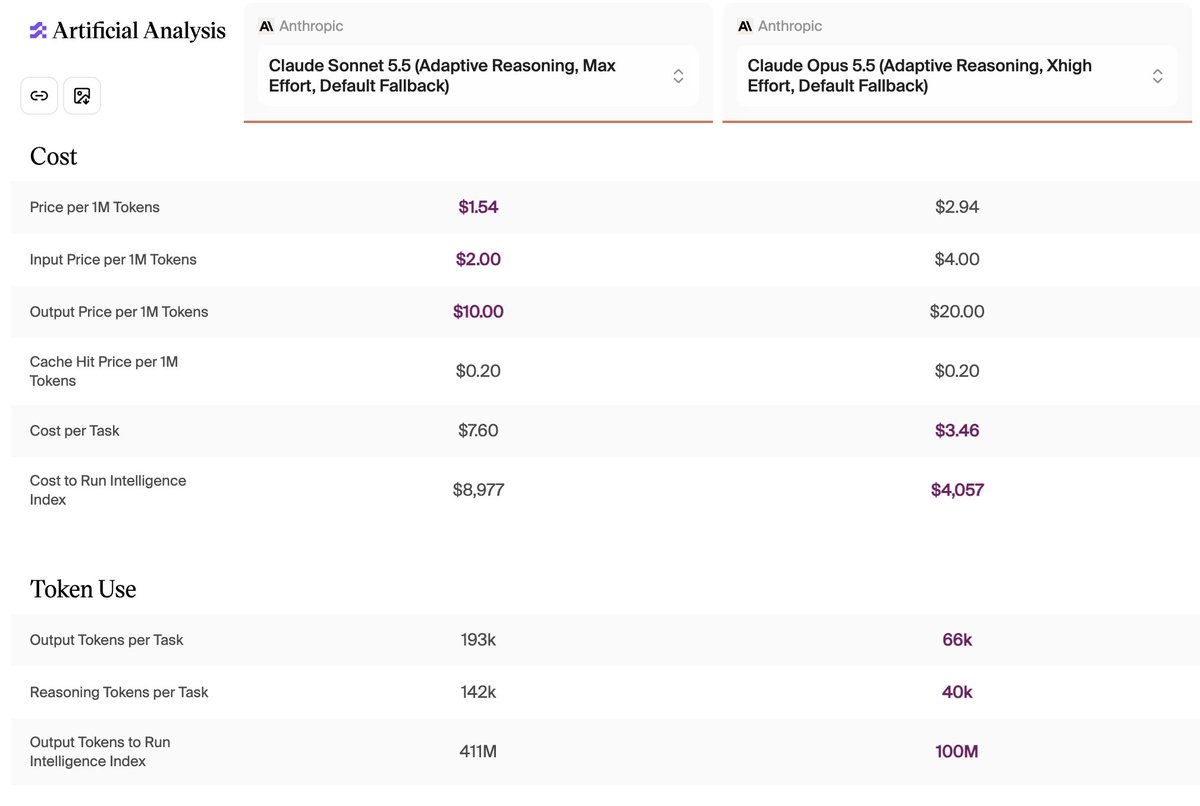
This is the part of AI pricing nobody talks about. Sonnet 5.5 and Opus 5.5 both score 56.0 on the Artificial Analysis Intelligence Index.
But at that same performance level:
→ Opus 5.5 (xhigh): $3.46/𝘁𝗮𝘀𝗸
→ Sonnet 5.5 (max): $7.60/𝘁𝗮𝘀𝗸
Sonnet is ~50% cheaper per token. Yet it can cost 2.2× more to finish the same benchmark task.
The reason is fascinating. Sonnet 5.5 is extremely capable but at max effort it can use ~193𝗞 𝗼𝘂𝘁𝗽𝘂𝘁 𝘁𝗼𝗸𝗲𝗻𝘀 𝗽𝗲𝗿 𝘁𝗮𝘀𝗸 and the model isn't just “thinking��� more.
It's spending more time in the loop:
𝗿𝗲𝗮𝗱 𝗰𝗼𝗻𝘁𝗲𝘅𝘁 → 𝗮𝗰𝘁 → 𝗿𝗲𝗮𝗱 𝗰𝗼𝗻𝘁𝗲𝘅𝘁 𝗮𝗴𝗮𝗶𝗻 → 𝗮𝗰𝘁 → 𝗿𝗲𝗽𝗲𝗮𝘁.
Artificial Analysis measured roughly 22M cached input tokens per task for Sonnet at this level around 3× Opus. So the model that looks cheaper on the pricing page can become more expensive once you put it behind an agent and this changes how we should think about model pricing.
$/1M tokens is not your AI cost.
Your AI cost is actually:
tokens × turns × context × retries × time → successful task
That's why with SPRO, we're increasingly interested in cost per outcome, not just cost per token because if one model costs $2/M but needs 3× the work to get the answer…it isn't actually the cheaper model :-( .
𝗧𝗵𝗲 𝗰𝗵𝗲𝗮𝗽𝗲𝘀𝘁 𝘁𝗼𝗸𝗲𝗻 𝗶𝘀 𝗶𝗿𝗿𝗲𝗹𝗲𝘃𝗮𝗻𝘁 𝗶𝗳 𝘆𝗼𝘂 𝗻𝗲𝗲���� 𝗺𝗶𝗹𝗹𝗶𝗼𝗻𝘀 𝗼𝗳 𝘁𝗵𝗲𝗺 𝘁𝗼 𝗳𝗶𝗻𝗶𝘀𝗵 𝘁𝗵𝗲 𝗷𝗼𝗯.
𝗚𝗣𝗧-𝟲.𝟭 𝗦𝗼𝗹 is now live on 𝗦𝗣𝗥𝗢.⚡️
@OpenAI's s latest reasoning model delivers near-Astra performance at roughly 1/5 the cost, now available on SPRO at 0% gateway fees.
→ Matches GPT-6 Astra on DeepSWE 1.1 at ~1/5 the cost
→ Reasoning controls from low → max
→ Text + image input
→ $2/M input · $0.10/M cached · $10/M output
Get GPT-6.1 Sol through the same unified SPRO API alongside the models you already use.
One gateway. Any model.
We’re giving AI agents access to our most sensitive resources faster than we’re building the security boundaries around them.Files. Credentials. Browsers. Tools.
One security flaw can turn that access into a serious data breach.
𝗦𝗮𝗻𝗱𝗯𝗼𝘅 𝗳𝗶𝗿𝘀𝘁. 𝗧𝗿𝘂𝘀𝘁 𝗹𝗮𝘁𝗲𝗿
𝗫𝗶𝗮𝗼𝗺𝗶 MiMo V2.6 is now available on 𝗦𝗣𝗥𝗢. 🚀
@XiaomiMiMo's new open-source model series:
• Frontier multimodal intelligence
• Stronger coding & agentic capabilities
• 1M context
• Open weights & RL resources
Explore MiMo V2.6 on SPRO 👇
https://t.co/EEwG5o3OKR
𝗚𝗿𝗼𝗸 4.7 is now available on 𝗦𝗣𝗥𝗢. 🚀
Built for:
• Coding & agentic tasks
• Long-running workflows
• Stronger self-verification
• 500K context
• $2/M input · $6/M output
Access Grok 4.7 through one unified API alongside 350+ models.
https://t.co/TzqkW6z0bP
GLM-5.3-FlashX is live on SPRO.
- 1M-token context
- 320B total parameters, 18B active
- Native text + image understanding
- Tool calling + structured outputs
- Up to 200 tokens/s inference speed
Route GLM-5.3-FlashX + 195+ models through SPRO:
https://t.co/qHxQ0wczhO
Dexis by Priyadharshini P https://t.co/A62rNkA48c
An AI tool that turns rough thoughts into structured, presentation-ready slides and diagrams in minutes.
Today we’ve launched Dexis on Peerlist 🚀
Would love to hear what the community thinks!
#AI#SaaS#BuildInPublic
Tired of dragging boxes forever just to make a diagram?
Explaining an app idea, process, or software project takes time and often looks messy.
We built Dexis so you can just type a sentence and get a clear diagram in seconds.
No drawing needed.
Quick 30-sec demo 👇