@deanwball We just published our empirical research into this question: https://t.co/8I47UHV5pc
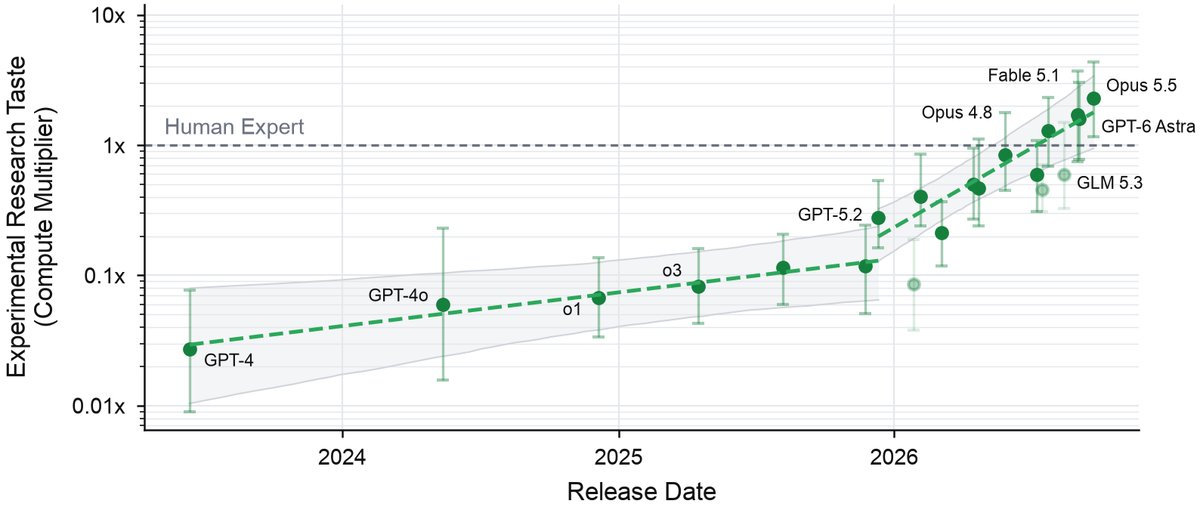
In the context of AI R&D, we operationalise experimental taste by how effectively a given amount of compute can be utilised.
How fast is AI's research taste improving?
We find that the experimental research taste of frontier models has doubled every ~3 months since December 2025. The best model, Opus 5.5, now exceeds our expert human baseline. Our human experts are experienced researchers, but most haven’t worked at a frontier lab.
Why measure research taste? In the AI Futures Model, it largely determines how quickly artificial superintelligence is reached once coding is fully automated.
TasteVal's tasks could help labs hill-climb on research taste if released, so we're publishing the results and methodology but keeping the tasks private. Here's our reasoning, and what would change our minds.
https://t.co/fvtUOtwQEL