Infrastructure for the next generation of AI developers. Making coding agents faster, smarter, and more efficient
CA: 0x534a1b32c34febb6d3d9b22d3c4090cbc6315aa5
$QUOTIENT IS NOW LIVE ON @Ponsdotfamily
CA: 0x534a1b32c34febb6d3d9b22d3c4090cbc6315aa5
Introducing $QUOTIENT — a project built on the vision of innovation, intelligent systems, and the pursuit of meaningful progress. More than just a name, QUOTIENT represents a mindset focused on efficiency, precision, and the ability to turn complex ideas into something valuable. In a world where countless projects compete for attention, we believe that a strong vision, consistent execution, and a clear sense of direction are what truly make a difference.
Today marks the beginning of the QUOTIENT journey. With a commitment to building a recognizable identity, strengthening our foundation, and growing alongside a community that believes in the vision, this launch is only the first step toward what we aim to accomplish. Every milestone starts with a decision to build, every achievement requires consistency, and every meaningful project needs time to establish its place.
We are here to build with purpose, move forward with conviction, and develop the vision one step at a time. No unnecessary promises — just a commitment to the process, the progress, and the possibilities ahead. This is where the journey begins, and there is much more to come.
$QUOTIENT is officially live. The foundation is set, the vision is clear, and the next chapter starts now.
You shouldn't be paying Fable prices for 88% bash tool I/O ... but you are. (data: 4,852 Claude Code session traces, SALT-NLP/SWE-chat on Huggingface)
Cut your Claude Code bill by 35-51% today. 2-week free trial, then $20/mo flat (backed by YC). https://t.co/7bu82dv54j
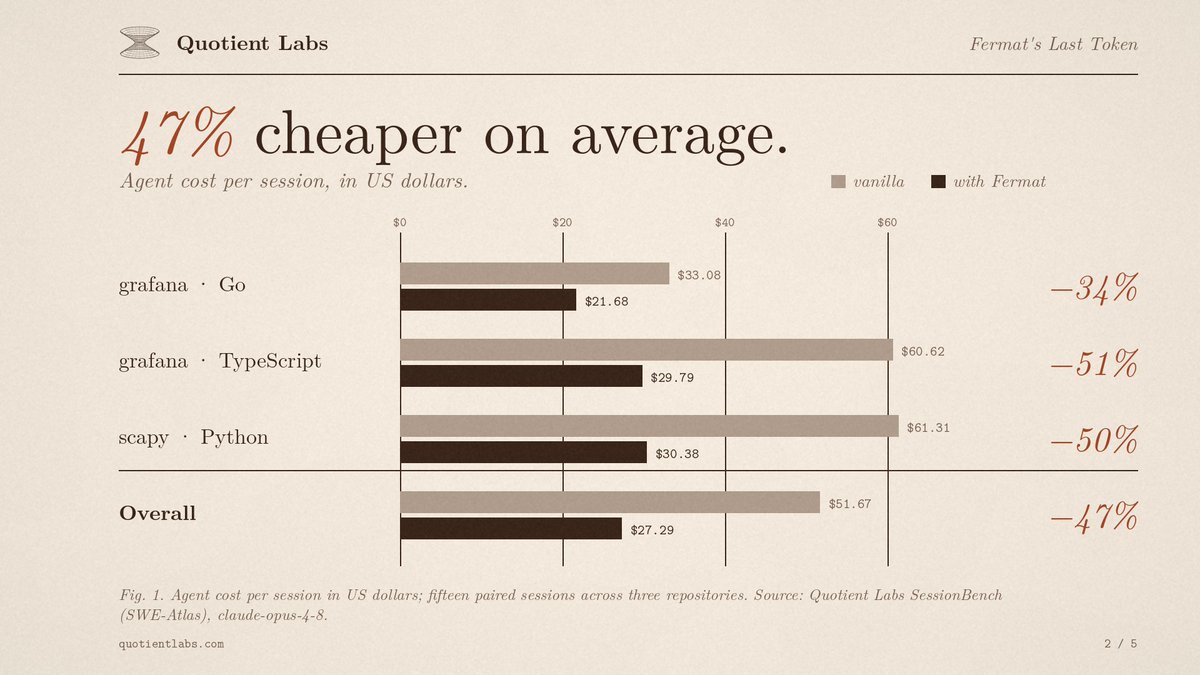
47% cheaper on average is not just a number — it shows what optimization can mean for AI-powered development.
Across benchmarked sessions, Fermat’s Last Token demonstrates how much unnecessary token spend can be reduced without changing the underlying model or the developer’s workflow.
The goal is straightforward: make every interaction count.
As AI coding agents become a bigger part of software development, efficiency becomes infrastructure. Quotient Labs is building toward that future.
Cheaper, not worse.
One of the more interesting parts of Quotient Labs is the idea that reducing token usage doesn’t have to mean sacrificing quality.
The goal is simple: make AI coding workflows more efficient, cut unnecessary costs, and keep the output where it matters.
47% lower cost, with quality held or improved.
It’s a small-looking improvement that could become increasingly important as AI-assisted development becomes part of everyday work.
Sometimes efficiency isn’t about doing less.
It’s about wasting less.
AI CODING IS GETTING MORE EFFICIENT.
Fermat’s Last Token takes a simple approach:
don’t make Claude process what it doesn’t need.
By optimizing context and tool calls, Fermat helps reduce unnecessary token usage while keeping the models and workflow developers already rely on.
Real benchmarks.
Real development sessions.
Measured cost reductions.
The future of AI coding isn’t only about better models.
It’s about using them more intelligently.
The launch was only the beginning.
Fermat’s Last Token is built around a simple idea: AI development should not require paying for context, tool calls, and tokens that never needed to be there in the first place.
Quotient Labs is working on the efficiency layer behind modern AI-powered development — optimizing how coding agents use context and resources without forcing developers to change the models or workflows they already rely on.
Less waste.
More efficiency.
Better use of every token.
The infrastructure is live. Now the real work begins.
Fermat sits quietly between the tools developers already use and the models doing the actual work.
Your workflow stays familiar. Claude Code sends the request, Fermat works in the middle to prune unnecessary context, optimize tool usage, and compress output, then passes a leaner request to the underlying API.
No new model. No complicated workflow.
Just a smarter layer between the code and the model — designed to make every request more efficient.
150 ticket runs. 15 paired sessions. 3 repositories.
And across every run, Fermat was cheaper.
That consistency is what matters.
Instead of relying on a single benchmark, Quotient Labs tested Fermat across repeated coding sessions to measure how much unnecessary token usage could actually be removed.
The result: lower costs across the entire set of runs, while keeping the development workflow intact.
Real sessions. Repeated testing. Less wasted spend.
That’s the efficiency layer Fermat is building for AI-powered development.
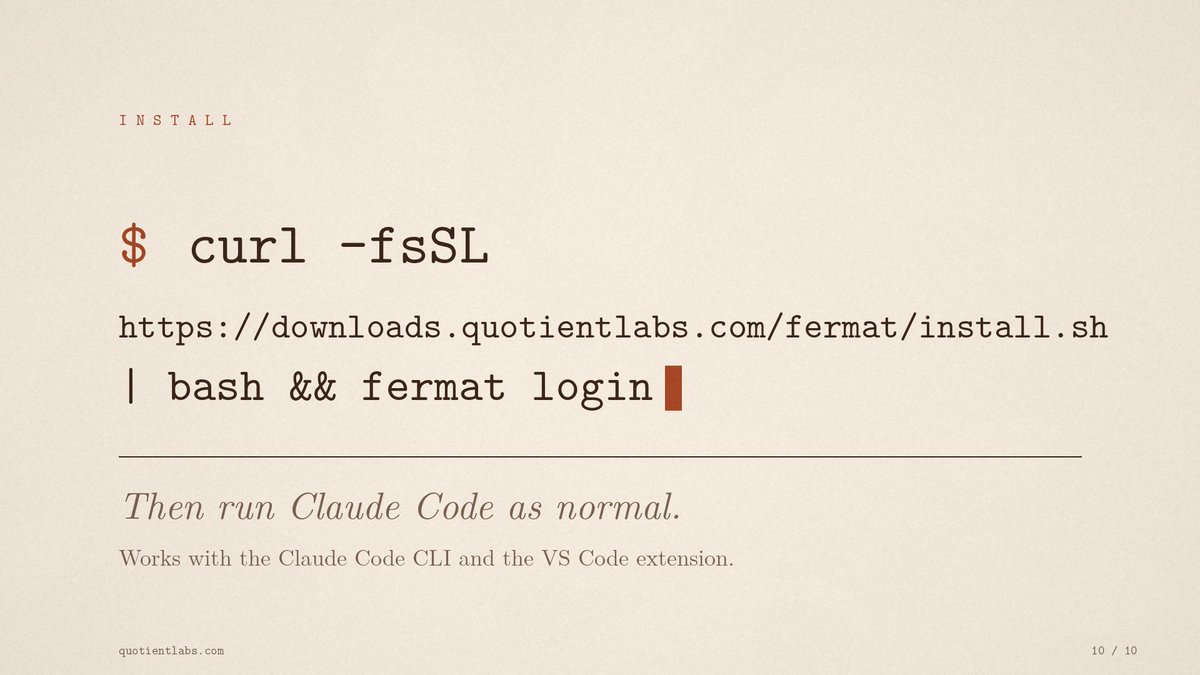
Getting started with Fermat is intentionally simple.
One command installs the layer, one login connects your environment, and then you continue using Claude Code as you normally would.
No complicated workflow changes. No new development environment to learn.
Just a lightweight efficiency layer working behind the scenes to reduce unnecessary token usage and make every AI coding session count.
Install once. Build more efficiently.
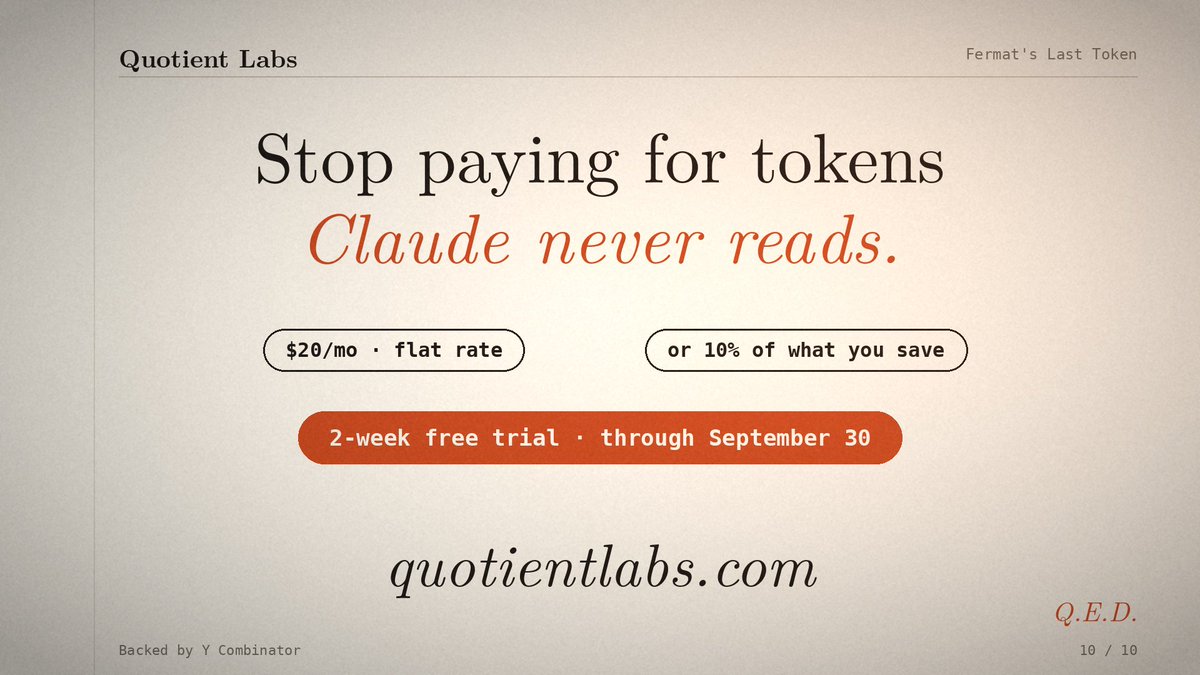
Stop paying for tokens Claude never needs to read.
Fermat’s Last Token is built around a simple idea: eliminate unnecessary context and work without forcing developers to change the models or workflows they already use.
With a simple pricing model — $20/month or 10% of what you save — the focus stays where it belongs: making AI-powered development more efficient.
Two weeks free.
Less wasted context.
More value from every session.
Quotient Labs is building a smarter efficiency layer for AI development.
One session. A very different outcome.
With Fermat, this TypeScript session went from $60.62 to $29.79 — a 51% reduction in agent cost.
But the interesting part isn’t only the savings.
Agent turns dropped from 21 to 15, while the quality score increased from 0.849 to 0.931.
That’s the idea behind Quotient Labs:
Spend less. Do less unnecessary work. Preserve — and potentially improve — the result.
AI development is getting more powerful. The next step is making that power more efficient.
This is what efficient AI development looks like.
Quotient Labs is building Fermat’s Last Token to reduce unnecessary token usage, optimize agent workflows, and cut the cost of AI-powered development without changing the way developers work.
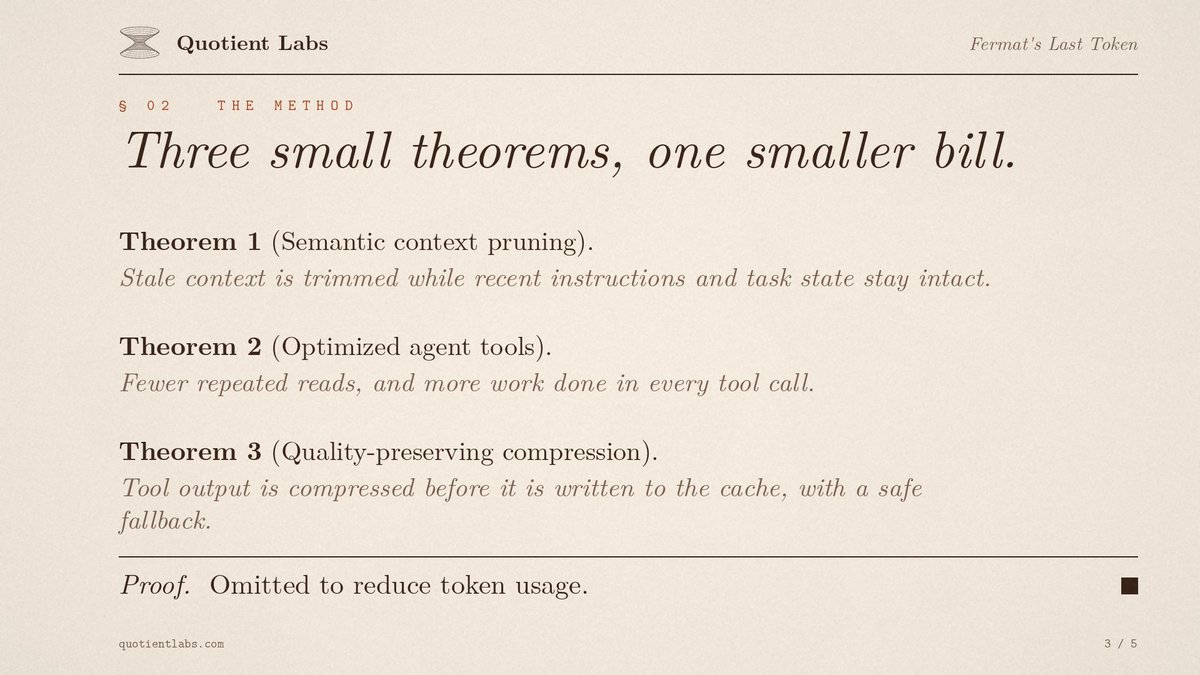
From context pruning to optimized tool calls and quality-preserving compression, every layer is designed around one principle:
Make every token count.
Less waste.
Lower cost.
More efficient AI development.
Quotient Labs — building the efficiency layer for AI-powered software.
Three small theorems. One big idea: make every token count.
Fermat’s Last Token is built around a simple principle — AI agents shouldn’t spend resources processing information they don’t need.
By pruning stale context, optimizing agent tool usage, and compressing tool output while preserving quality, Quotient Labs turns efficiency into a core part of the development workflow.
Less repetition.
Less waste.
More useful work from every interaction.
The future of AI development isn’t just about smarter models. It’s about smarter systems around them.
You shouldn't be paying Fable prices for 88% bash tool I/O ... but you are. (data: 4,852 Claude Code session traces, SALT-NLP/SWE-chat on Huggingface)
Cut your Claude Code bill by 35-51% today. 2-week free trial, then $20/mo flat (backed by YC). https://t.co/7bu82dv54j