Built an outage investigation agent with Jev: ~5 s per incident, vs 32 and 119 s for general-purpose LLMs.
Right service 57/60 times, but often without checking what failed.
How do you check that an AI agent actually did the work, not just got lucky? https://t.co/iu0tPbwoaV
came to X to share serious engineering stuff.
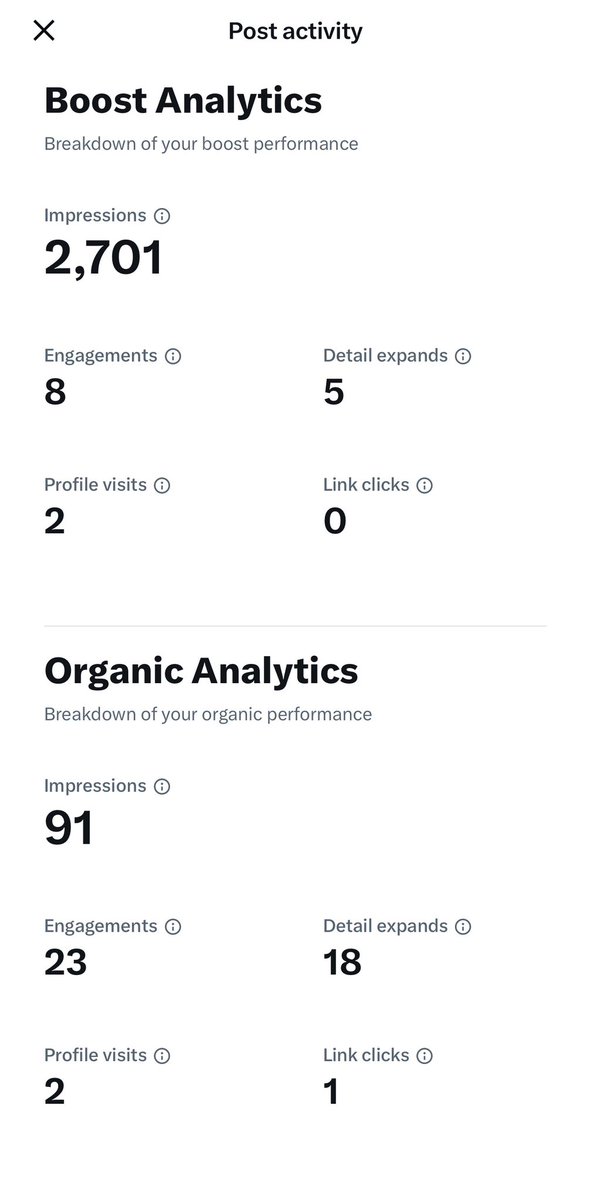
40+ posts, 8 followers. thought maybe reach was the problem, so i boosted a post 😅
paid: 2,701 impressions, 2 profile visits
organic: 91 impressions, 2 profile visits
same destination, took the toll road 🥲
@TypeLLM this is interesting. i’m building TypeRCA around incident investigation using decision models and currently it supports Jev, and I think it could be a good real-world place to test TypeLLM too. happy to try it
i’m Minglei. staff engineer at Uber, dad of two girls.
i’ve spent years building and debugging production systems, and now AI agents. happy to share what i’ve learned, give feedback on what you’re building, and learn from you too.
let’s connect and follow each other 👋