I’ve spent 24 years perfecting my investing process for family and clients.
I’m sharing that blueprint—for FREE.
Download my new 52-page eBook today: https://t.co/GRV29TFbQ2
It's called, “Master the Market: A Hedge Fund Manager's Guide to Process and Profit."
Whether you’re new to investing or a seasoned pro, this guide will help sharpen your skills and elevate your game.
You have nothing to lose and everything to gain.
Andrej Karpathy spent 8 years at OpenAI and Tesla
Last week, he compressed everything he knows into one free 2-hour lecture
Agents → Loops → Harness → Self-Improving Systems
People spend $15K on bootcamps that teach less than this
This lecture beats most paid AI engineering courses
You probably don't have 2 hours right now
Don't let this vanish from your feed
Watch it
Then read the article below
These 94 lines of code are everything that is needed to train a neural network. Everything else is just efficiency.
This is my earlier project Micrograd. It implements a scalar-valued auto-grad engine. You start with some numbers at the leafs (usually the input data and the neural network parameters), build up a computational graph with operations like + and * that mix them, and the graph ends with a single value at the very end (the loss). You then go backwards through the graph applying chain rule at each node to calculate the gradients. The gradients tell you how to nudge your parameters to decrease the loss (and hence improve your network).
Sometimes when things get too complicated, I come back to this code and just breathe a little. But ok ok you also do have to know what the computational graph should be (e.g. MLP -> Transformer), what the loss function should be (e.g. autoregressive/diffusion), how to best use the gradients for a parameter update (e.g. SGD -> AdamW) etc etc. But it is the core of what is mostly happening.
The 1986 paper from Rumelhart, Hinton, Williams that popularized and used this algorithm (backpropagation) for training neural nets:
https://t.co/f52IcDNitR
micrograd on Github: https://t.co/GaTd16jRnB
and my (now somewhat old) YouTube video where I very slowly build and explain:
https://t.co/EPGG6kd5Yz
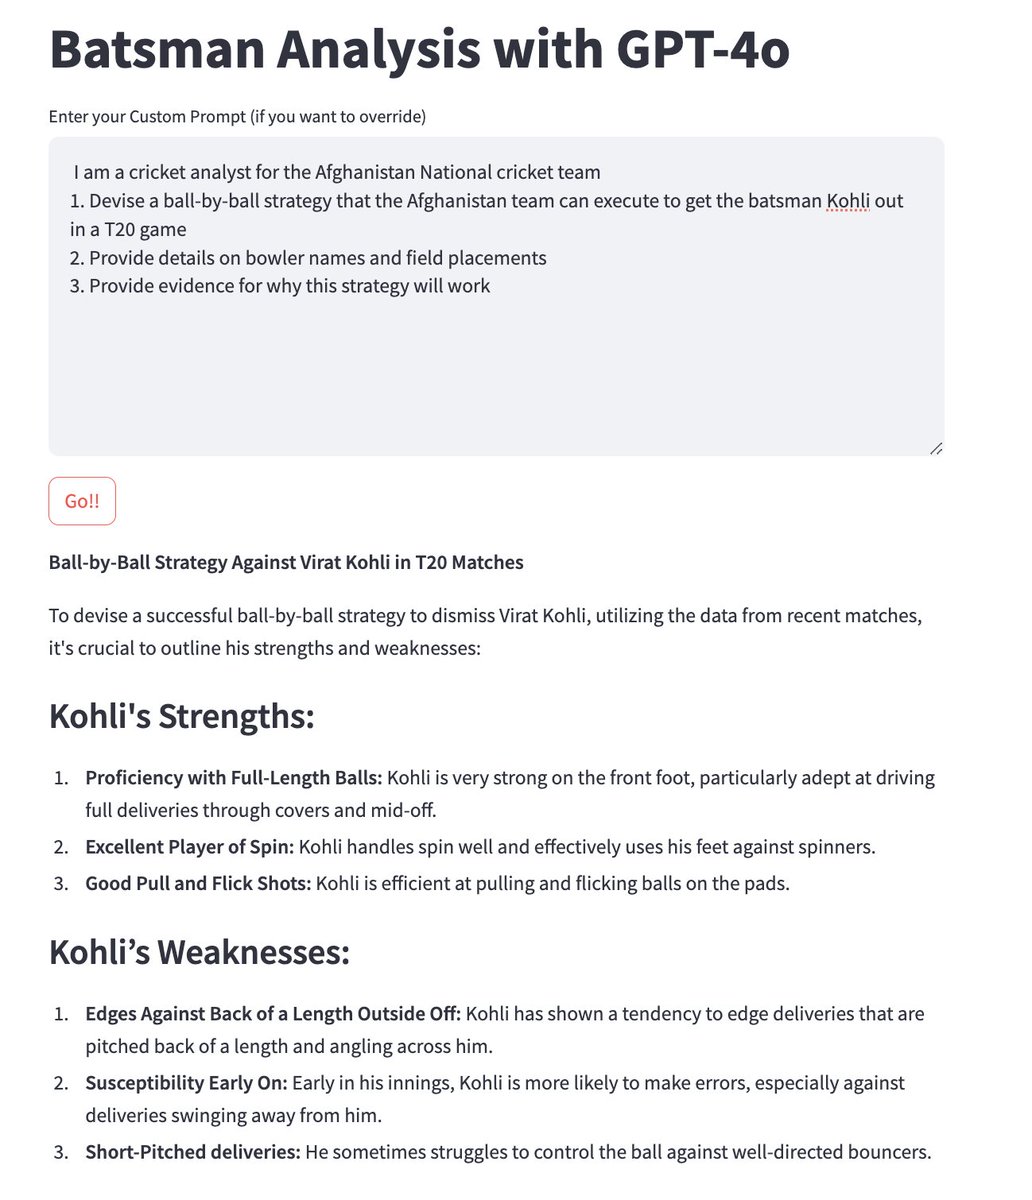
especially it recommended to bowl googly at leg stump , hoping he would sweep and get out.
Something similar happened, its a regular leg spin and he tried to reverse sweep
https://t.co/mqMauqIYmT I was analyzing the ongoing T20 World Cup and thought, why not develop a GPT-40-powered RAG? So, I built this hacky toy app. It's not polished and can make embarrassing mistakes and hallucinate. However, I can see legitimate responses for strategies against @imVkohli
for AFG cricket team and against @rashidkhan_19
for IND cricket team.
@ESPNcricinfo
@ESPNLiveCric@ICC
i would love to get feedback
@ashwinravi99
and PDOGG 🙏
@srinathkrishna It's interesting to play with the tool. I asked Rishabh has hit Nabi for 3 consecutive fours, how should AFG team get him out. Tool recommended to bring in Rashid Khan and he is OUT!
If this were a science paper, you would expect a country that picks its science workforce at random as a “weak baseline” and a leading nation like the US to actively experiment towards state-of-the-art, or at least beat the baseline.
Not providing a guaranteed path for accomplished scientists like @rdesh26, who graduated from one of the top labs in the country, @jhuclsp, to contribute to our progress and security directly is an avoidable tragedy.
I implore the @WhiteHouse / @USAGov OSTP, @StateDept, and @STASatState to look into the ways we are leaching out the best talent in the country, starting with this lottery system for the nation’s most talented.
Many have made this request before to past administrations to no avail, but acting on this now would leave a legacy that will be the envy of future administrations. I hope you do. If you have doubts, ask other best scientists nationwide, including @theNASciences.
@jeffzwang I would love an invite, working on LLM powered applications at LinkedIn
Tip:
For my pet projects
1. Precompute results for follow up suggestions
2. Semantic cache
3. LLM inference for non English is 2X slower. Simple google translate API usage before and after improves
@srinathkrishna 1. I made a mistake. I am sorry. Public: Wow. Very brave. What a leader! Demonstrating vulnerability.
2. I made a mistake. I am sorry. Let me fix the bug. Committee: This is an area of improvement. Try again next year!
Techlead put sympathy videos mentioning that his wife left him with their kids, earned views on YouTube, made millions, used it to buy toilet paper to wipe his hole.
And people still take him too seriously when he shit posts and quote tweet!
Stop amplifying!
I strongly believe that all managers in a technical area must be technically excellent.
Managers in software must write great software or it’s like being a cavalry captain who can’t ride a horse!