Our new paper in npj Antimicrobials and Resistance introduces resLens, genomic language models for detecting antibiotic resistance genes, including divergent sequences missed by traditional alignment methods.
https://t.co/i5OuRI9NVj
Congrats, Matthew Mollerus!
#Genomics#AI#AMR
AIntibody Challenge results published in Nature Biotechnology https://t.co/VZAiIm9GOV! Our classical ML + antibody design approach placed 6th in Challenge 1, which focused on optimizing antibody affinity against SARS-CoV-2 RBD.
#AI antibody design, thanks @NSF for supporting.
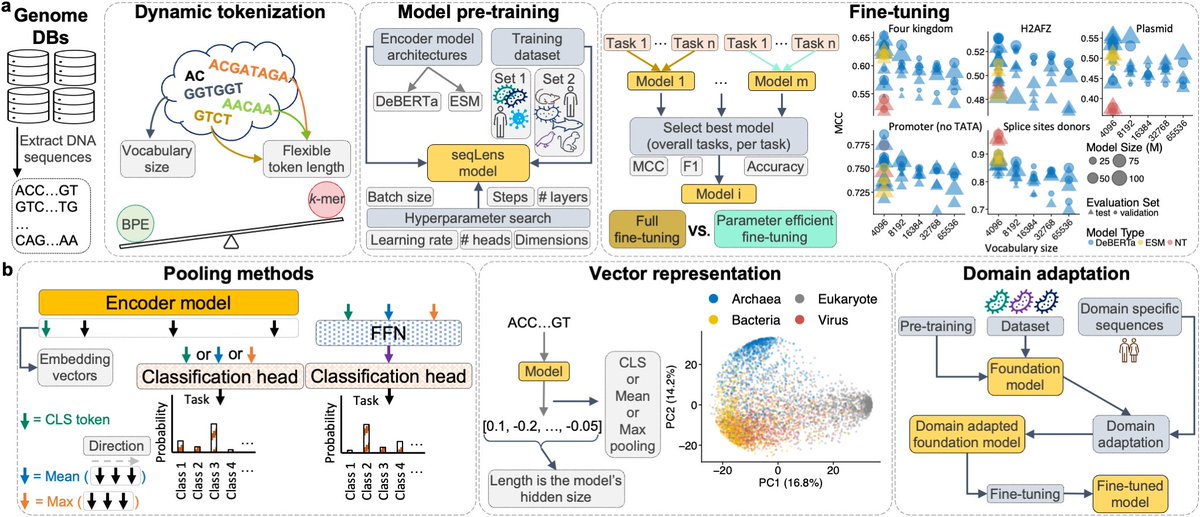
Which design choices matter most for genomic language models? Our new Molecular Biology and Evolution paper benchmarks tokenization, model architecture, pretraining data, pooling, domain adaptation, and fine-tuning to provide a roadmap for gLMs https://t.co/yxUFTPWEX1
Antibiotic resistance is outpacing traditional detection methods. Led by Matthew Mollerus, we introduce resLens, a family of genomic language models that learn latent DNA representations to detect and analyze ARGs without rigid reference databases.
🧪🦠 𝐓𝐡𝐞 𝐜𝐚𝐧𝐜𝐞𝐫 𝐦𝐢𝐜𝐫𝐨𝐛𝐢𝐨𝐦𝐞 𝐜𝐨𝐧𝐭𝐫𝐨𝐯𝐞𝐫𝐬𝐲 𝐢𝐬 𝐟𝐢𝐧𝐚𝐥𝐥𝐲 𝐛𝐞𝐡𝐢𝐧𝐝 𝐮𝐬 🧠🧬
What began as a side project at @Merck evolved into a full-scale discovery effort — a nearly two-year meta-analysis led by Xinyang Zhang and the @RahnavardLab Lab, culminating in a #preprint and dissertation chapter.
📊 678 melanoma patients
📚 7 independent studies
🧬 Faecalibacterium SGB15346 consistently linked to immune checkpoint inhibitor (ICI) response
🔬 RiPP gene clusters and SCFA pathways reveal new mechanistic insights into treatment efficacy
🛠️ Fully reproducible pipeline built using the latest bioinformatics tools
🔍 A first-of-its-kind integration of microbial species, biosynthetic gene clusters, and functional pathways in the context of ICI — a major step toward microbiome-guided precision immunotherapy.
🎉 Huge congratulations to Xinyang, and sincere thanks to the @RahnavardLab for their collaborative partnership throughout this work!
Link: https://t.co/VpNOHvauUt
#CancerImmunotherapy #Microbiome #Omics #DataScience #Statistics #Biostatistics
seqLens: Optimizing Language Models for Genomic Predictions
1. The paper introduces seqLens, a family of DNA language models designed for genomic predictions, leveraging disentangled attention with relative positional encoding to enhance performance across multiple genomic tasks.
2. Unlike conventional DNA language models that rely on fixed k-mer tokenization, seqLens employs byte-pair encoding (BPE), allowing dynamic token lengths that improve convergence and reduce computational overhead.
3. The study systematically compares seqLens models to existing state-of-the-art DNA models, demonstrating superior performance in 13 of 19 benchmarking tasks, including phenotype prediction and genome annotation.
4. Two large-scale pretraining datasets were used: one containing 19,551 reference genomes (predominantly bacterial) and another with a broader taxonomic balance, including eukaryotic and archaeal genomes, covering 180 billion nucleotides.
5. seqLens models integrate multiple architectural improvements, including the DeBERTa-inspired disentangled attention mechanism, which separately encodes content and positional information, leading to more efficient DNA sequence modeling.
6. The study explores various fine-tuning strategies, including full fine-tuning and parameter-efficient adaptation methods like LoRA, revealing trade-offs between computational efficiency and predictive accuracy.
7. Domain adaptation through continual pretraining significantly enhances performance on specialized genomic tasks, enabling seqLens models to effectively transfer learned representations across different genomic datasets.
8. Benchmarking results indicate that seqLens models with smaller vocabularies tend to generalize better than those with larger tokenizers, highlighting the importance of balancing vocabulary size and training efficiency.
9. Alternative pooling strategies, including mean and max pooling, are evaluated for classification tasks, with mean pooling outperforming the commonly used CLS token representation in multiple genomic benchmarks.
10. Future work aims to refine seqLens by incorporating multimodal genomic data, exploring reinforcement learning-based optimization, and expanding applications in metagenomics and regulatory sequence modeling.
📜Paper: https://t.co/vIbqtrLgKe
#GenomicAI #LanguageModels #Bioinformatics #ComputationalBiology #MachineLearning
On our way to #cshldata24 at @CSHL! Make sure to catch @chiraaggohel's talk on tools for metabolomics based epidemiology, and his poster on software for the integration of large scale metabolomics experiments! #metabolomics#bioinformatics
Time to culture some great connections at the @CSHL's Microbiome meeting! Our lab's gut instinct told us this was the perfect place to share our findings :) 🦠🧬
Excited about our lab's contribution to #JSM2024, presenting our progress on omics AI: a talk on the dynamics of longitudinal omics using #waveome and a panel on the future of LLMs (omics LLMs for health), organized by @Mallick_Himel and @fraukolos, and moderated by Siyuan Ma 🙏
Interested in pursuing a PhD in Health Data Science? Join The George Washington University- Milken Institute School of Public Health for an info session on July 23rd, 12-1pm on Zoom. RSVP today! https://t.co/fC9TNLD1iC