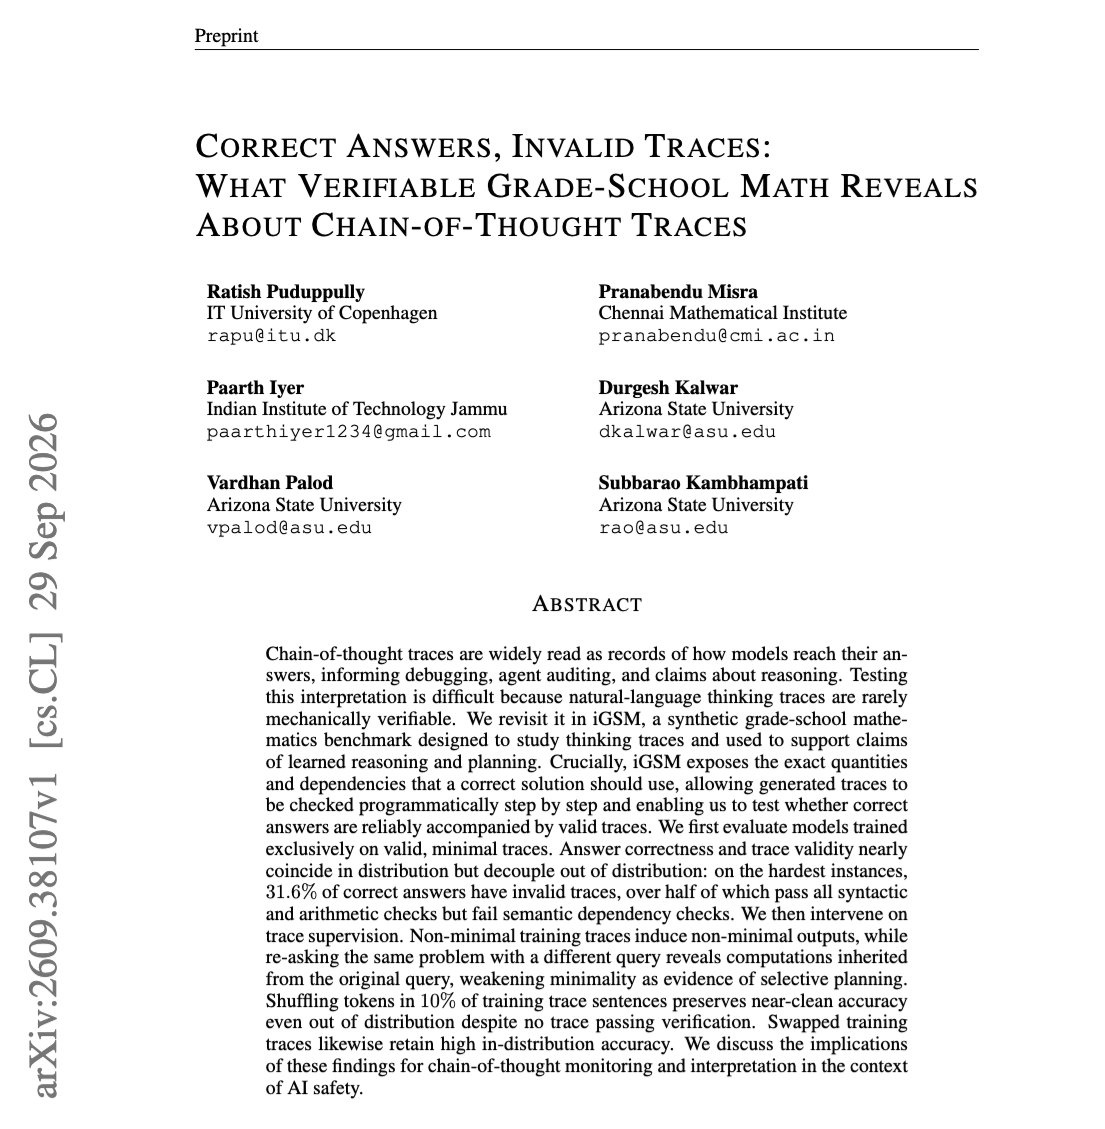
Happy to share our paper, "Correct Answers, Invalid Traces: What Verifiable Grade-School Math Reveals About Chain-of-Thought Traces".
When a model gets the right answer, is the reasoning it produces also right? We test this on synthetic grade-school math where every step of a trace can be checked by a program.
Thread below.
Thanks Joël for tagging me! Really appreciate the spirit of opensourcing all the data and models.
I also extended the study to math split and format compliance was low there too, similar to the table split. FAQ and Tutorial are relatively better. Sharing the link here in case anybody wants to have a look: https://t.co/vpEmBQf1EZ
Releasing:
- 200K annotated documents: https://t.co/oAXyMwyU3U
- Binary + multiclass ModernBERT classifiers (F1=0.86/0.80): https://t.co/HND7a95APX
- All code for the audit pipeline, annotation, and training
- On known problematic domains (https://t.co/ugMx76M08U, https://t.co/CmocXxk8kl, https://t.co/JAAcI9e9cD, etc.), 39% of documents contain misinformation, nearly 10x the overall rate
- Extrapolating to the full 1.53B document dataset: ~63M pages may contain misinformation
Getting scooped on my own paper drop by @DamienTeney 😂
But he's spot on - tabular language models have been overblown
Reported performance gains often don’t come from emergent generalization at all.
https://t.co/kZcXJ5DTAS
Happy to share our new paper! We study Tabular Language Models (TLMs): LLMs fine-tuned on serialized tabular data, converting rows into text sequences.
Do TLMs actually learn tabular reasoning? Our re-evaluation suggests maybe not. 🧵
Paper: https://t.co/cBJdYMhsuZ
(3) Instruction-tuning alone with Alpaca (no tabular data) bridges most of the performance gap
This suggests reported gains come from instruction-following and memorization rather than genuine tabular reasoning.
Excited to share our latest work on initializing expanded vocabulary for language models! Kudos to Nandini and Aditya for their excellent contributions!
🚨🚨 New preprint 🚨🚨
Presenting: An Empirical Comparison of Vocabulary Expansion
and Initialization Approaches for Language Models
Paper: https://t.co/zP06xk1MTP
Code: https://t.co/9u6NArG6wM
@anoopk@ratishsp@nandi_mundra
📣 📣 📣 New instruction-tuned LLM! 📣 📣 📣
Today, we announce an initial release of "Airavata", an instruction-tuned LLM for Hindi.
Blog: https://t.co/JtmVZIpVS9
Model: https://t.co/MVpTA0UWEZ
Datasets: https://t.co/avtGcvYT2v
(1/N)