Our new name reflects our promise to all customers: no matter how much data you’re looking for, how much bandwidth you require, or how many IPs you need, we can provide all that and more.
Read Rayobyte's full story here: https://t.co/T8avaLlkrx.
The cheapest request isn't always the cheapest result.
Retries, failed sessions, incomplete data, recollection, and engineering time all add to the real cost of web data.
At scale, cost per usable result can tell you far more than the headline price per GB.
Before building another data collection pipeline, there's a useful question to ask:
Should we actually scrape this?
Freshness, control, coverage, maintenance, and cost can all change the answer.
Web data teams: what makes you choose scraping over an existing API or dataset?
A new product range. A pricing shift. Hiring in a new country. A pattern emerging in customer reviews.
Individually, they're small signals.
At scale, public web data can reveal how companies and markets are changing long before the full story becomes obvious.
The website looks the same.
Your code hasn't changed.
Your scraper suddenly stopped working.
😅
Browser behavior, network signals, fingerprints, sessions, and anti-bot logic can all be hiding underneath.
What's the weirdest cause you've ever found behind a scraping failure?
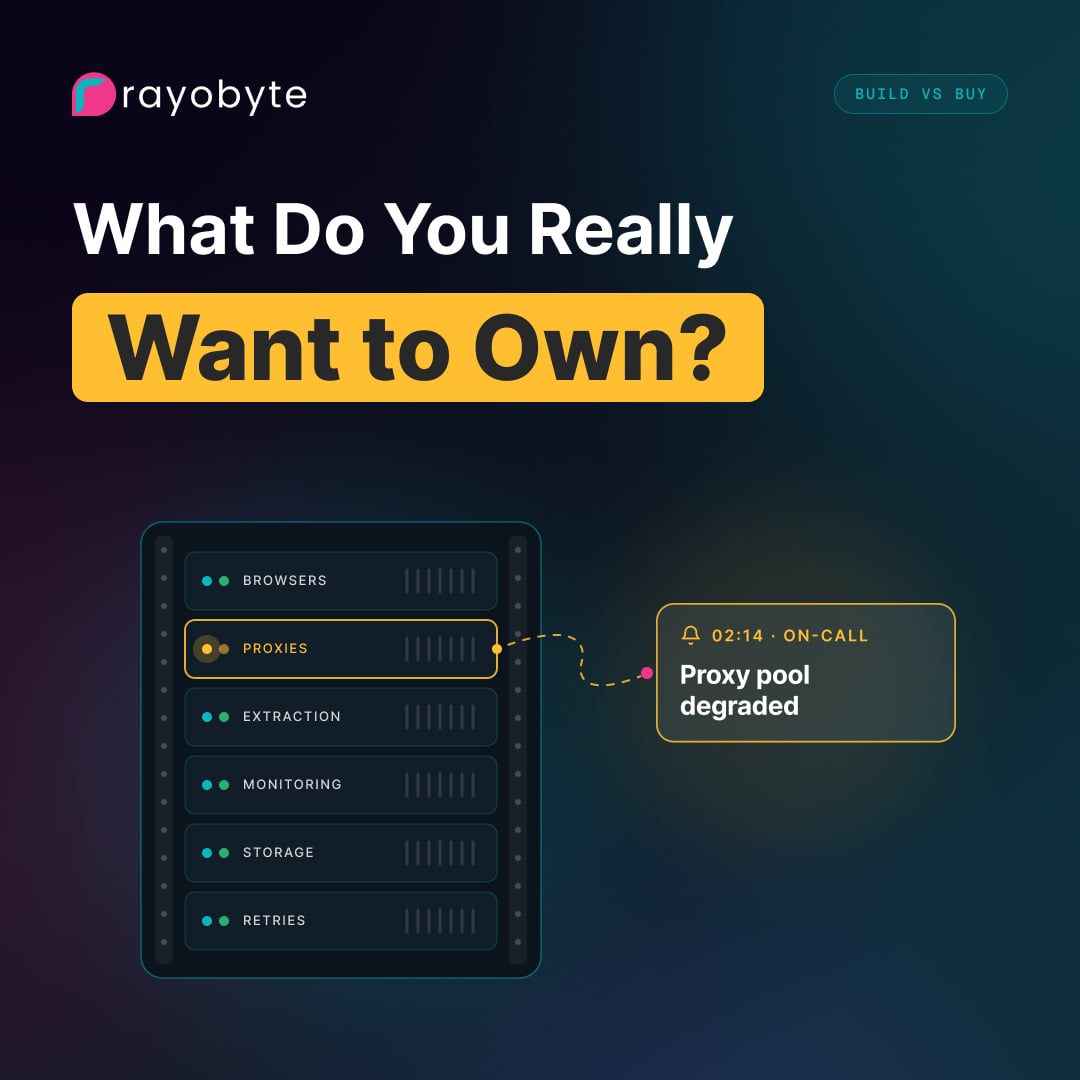
Every piece of infrastructure you build becomes something you own at 2am.
Browsers. Proxies. Extraction. Monitoring. Storage. Retry logic.
The question for engineering teams is which parts are worth owning.
What's one part of your stack you'd happily never maintain again?
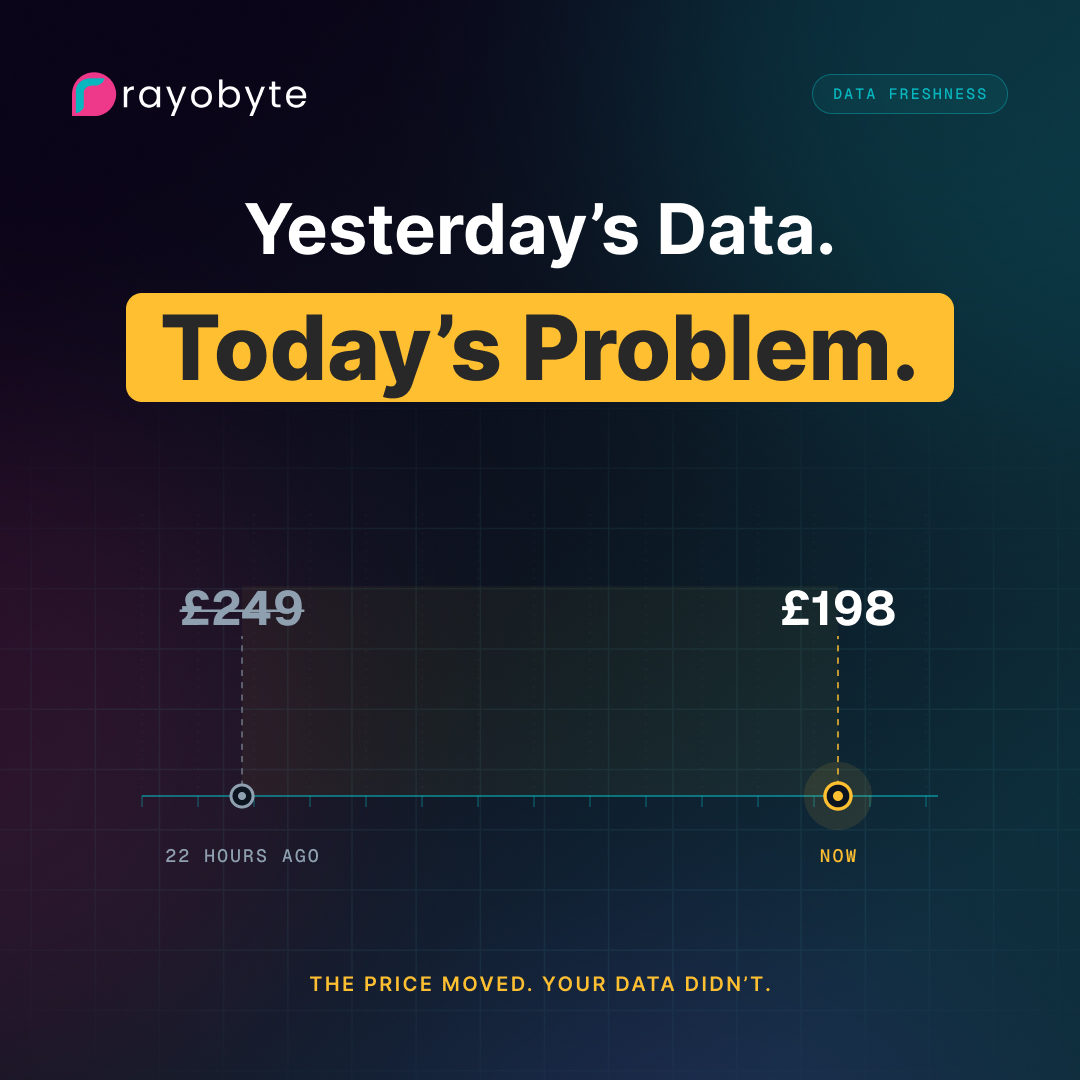
Nobody compliments a comparison site for having yesterday's price.
They definitely notice when it's wrong.
"Fresh" means something different for every dataset. Yesterday might be fine for one. Twenty minutes ago might be too old for another.
When does your data lose value?
The web has spent years getting better at identifying automated traffic.
Now we're building an internet full of AI agents designed to browse it.
Those two trends are heading directly toward each other.
What happens when automated browsing becomes normal web traffic?
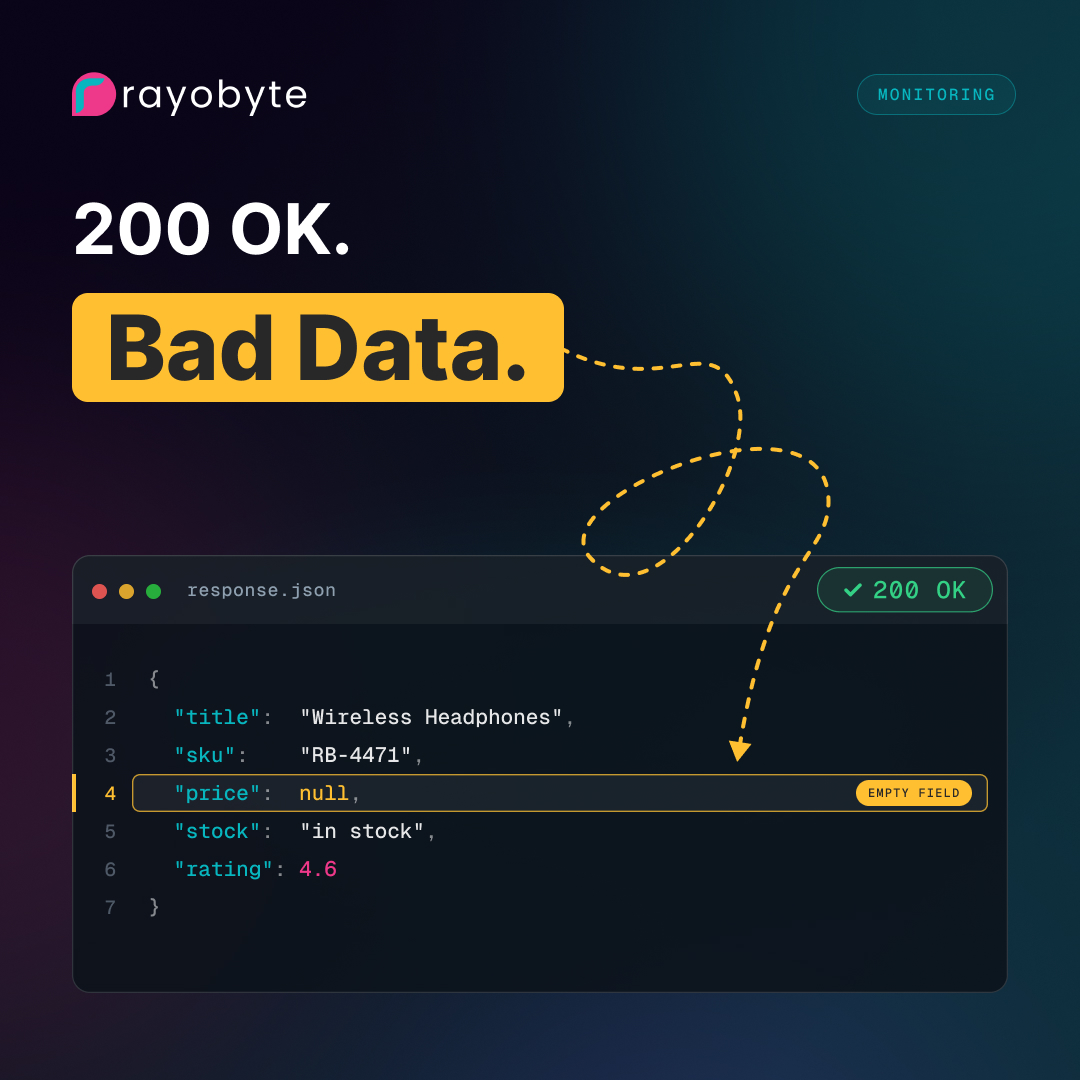
Your scraper returned 200 OK.
Great.
Except the price field is empty.
Request success doesn't always mean data collection success. At scale, field completion, record counts, and extraction patterns can reveal problems your request metrics completely miss.
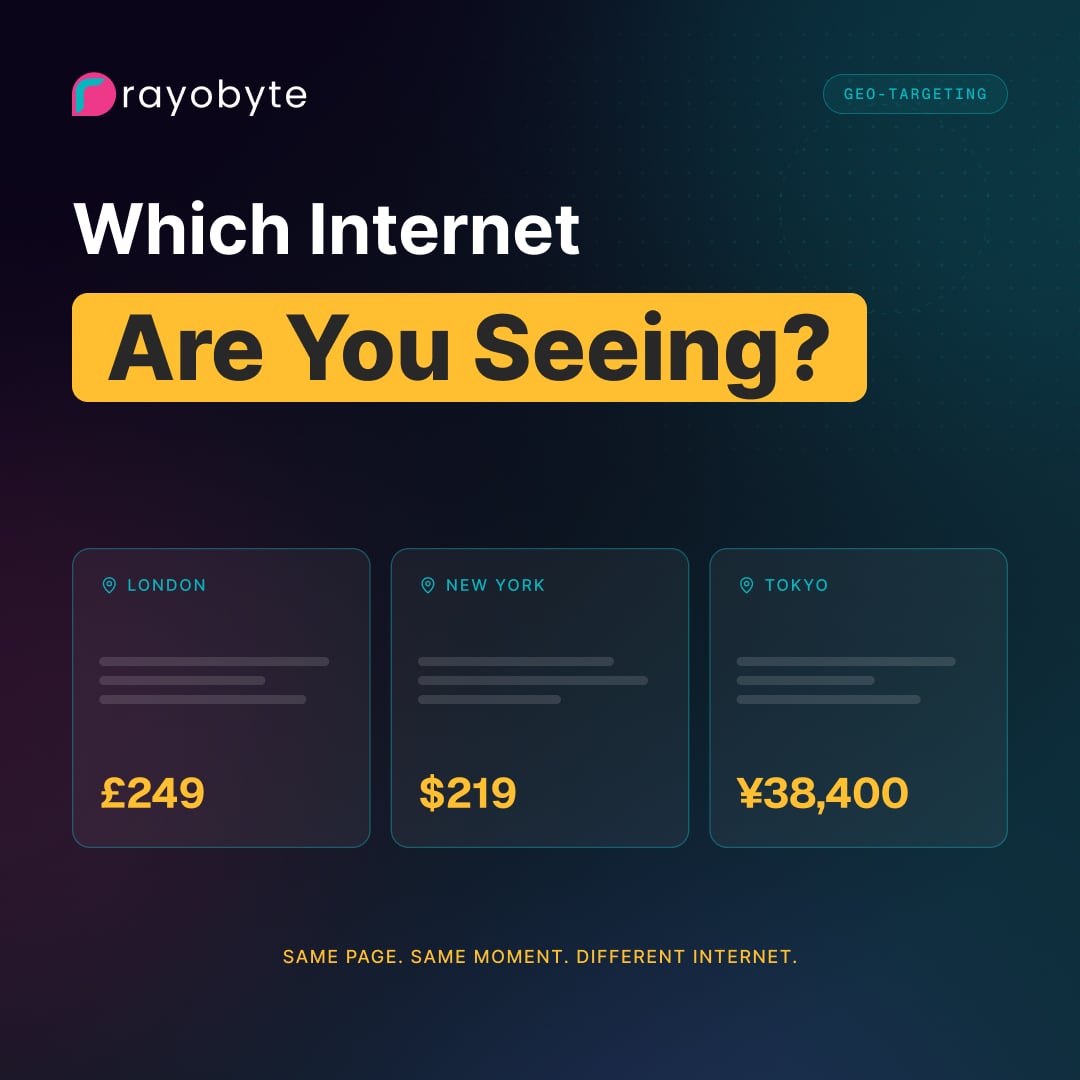
There isn't really one version of the internet.
Prices, products, search results, availability, and experiences can all change depending on where you're browsing from.
For web data teams, sometimes where you collect the data is part of the data itself.
One of our customers summed up collecting public web data at scale perfectly:
"We need to be everywhere and also be nowhere."
Different locations, high volumes, reliable research.
Sometimes the customer explains the use case better than we ever could.
Here's a question for teams scraping at scale:
If you cut your collection volume by 25% tomorrow, how much useful information would you actually lose?
More data means more infrastructure and cost. The clever part is knowing which data actually needs to be fresh.
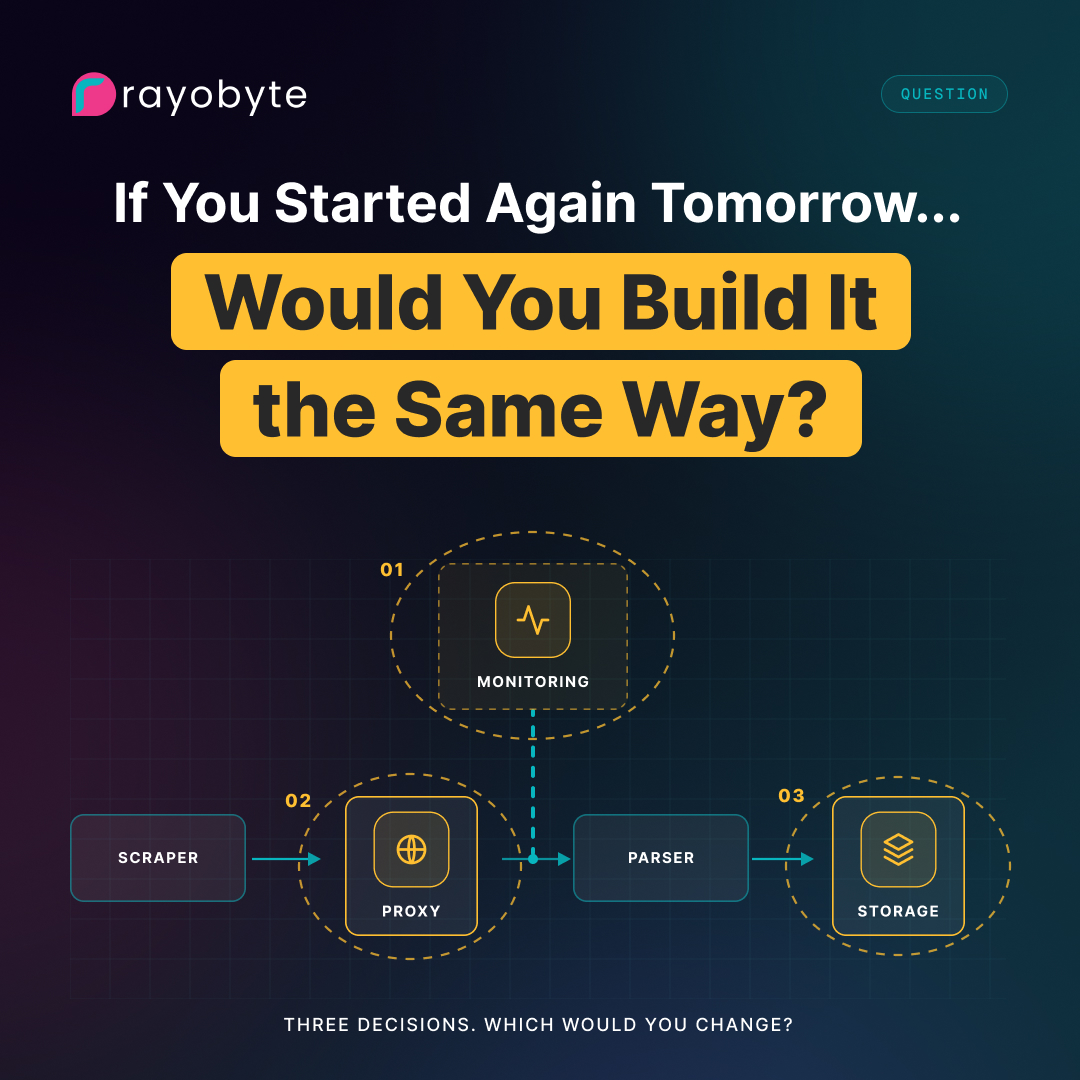
Engineers who've watched a small scraper turn into business-critical infrastructure:
What would you build differently if you started again today?
Monitoring earlier? Different proxies? Less DIY infrastructure?
Your competitors' reviews can reveal more than their websites.
Complaints, praise, feature requests and pricing concerns become valuable patterns at scale, showing you where opportunities might be hiding.
Learn more: https://t.co/6ePmAmJ5AE (https://t.co/6ePmAmJ5AE)
A trend is most useful before everyone else spots it.
Public social data can reveal shifts in sentiment, competitor reactions, and emerging conversations early enough to act on them.
See what you can learn: https://t.co/XttK17W8ag (https://t.co/XttK17W8ag)
The best product updates aren't always the most visible.
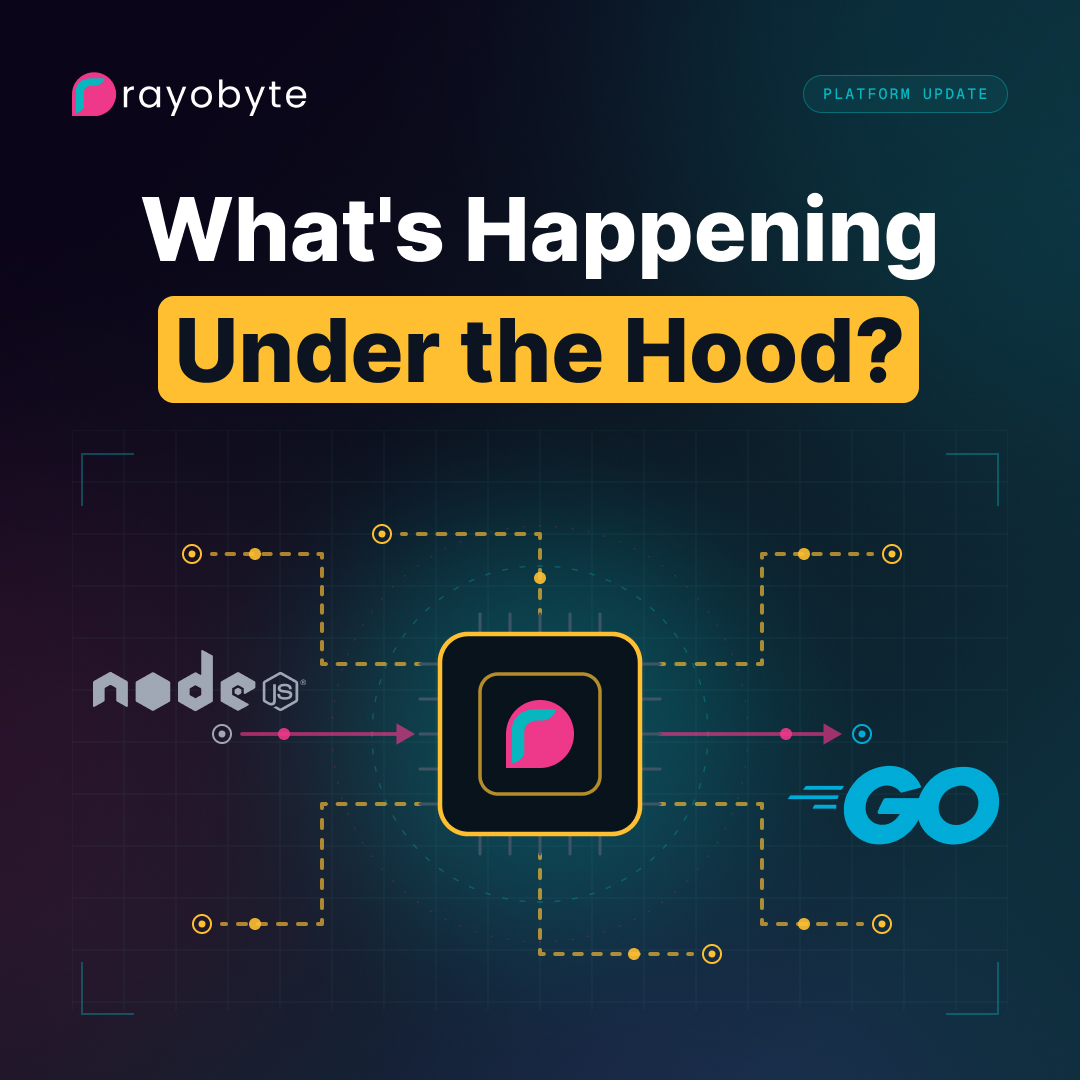
We've migrated our residential proxy platform from https://t.co/vtij1mimQa to Go, improving latency and overall performance across the network.
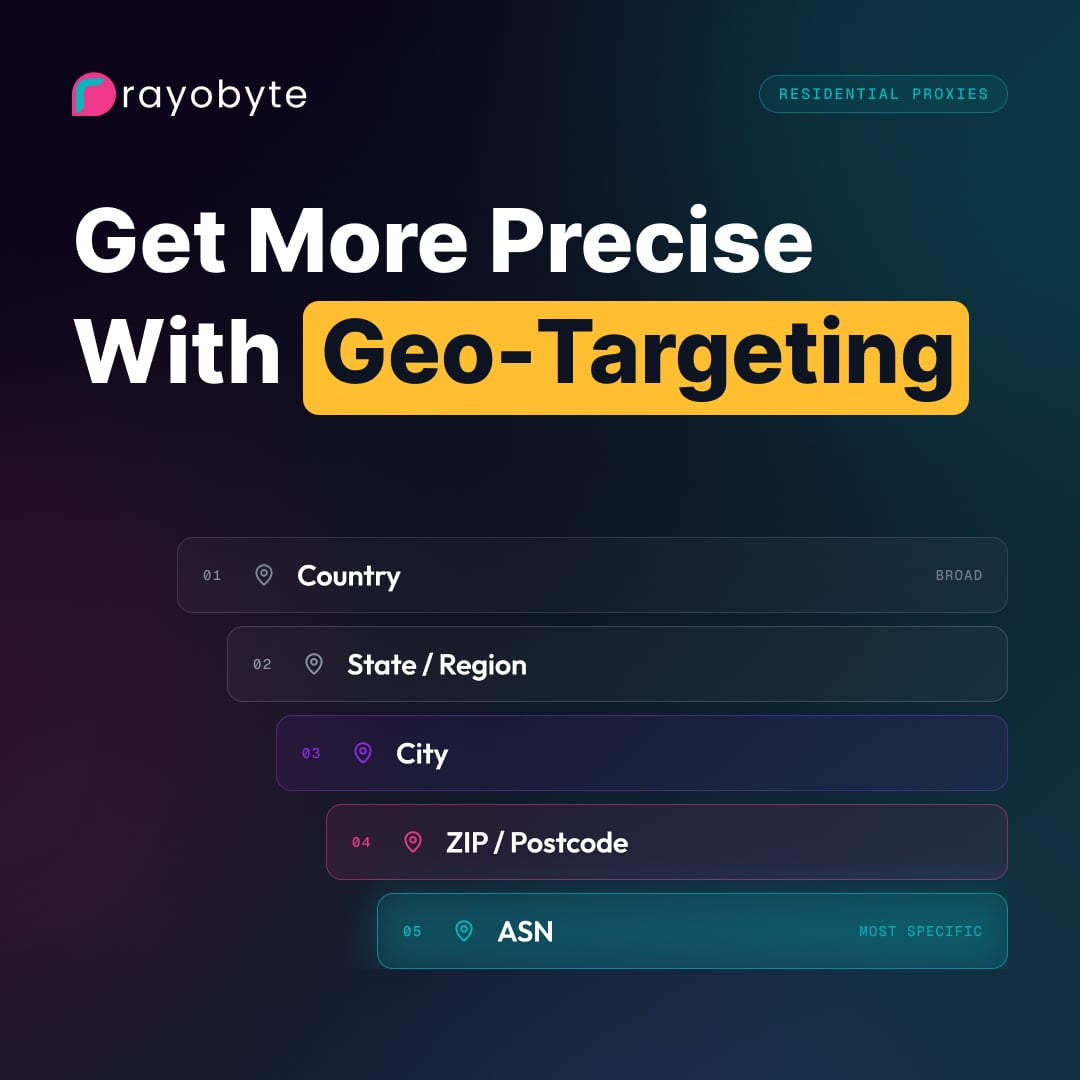
Country isn't always enough.
Our residential proxies now support targeting by:
📍 ASN
📍 City
📍 State
📍 ZIP
📍 Country
Use one or combine them to match your workload.
Some of our best product ideas haven't come from planning meetings.
They've come from customer conversations and engineers asking, "There has to be a better way."
We never want to stop listening.
The web isn't standing still.
Neither should your scraping stack.
Modern data collection is all about building systems that adapt.
Learn more:
https://t.co/E3lEe1O1Hp