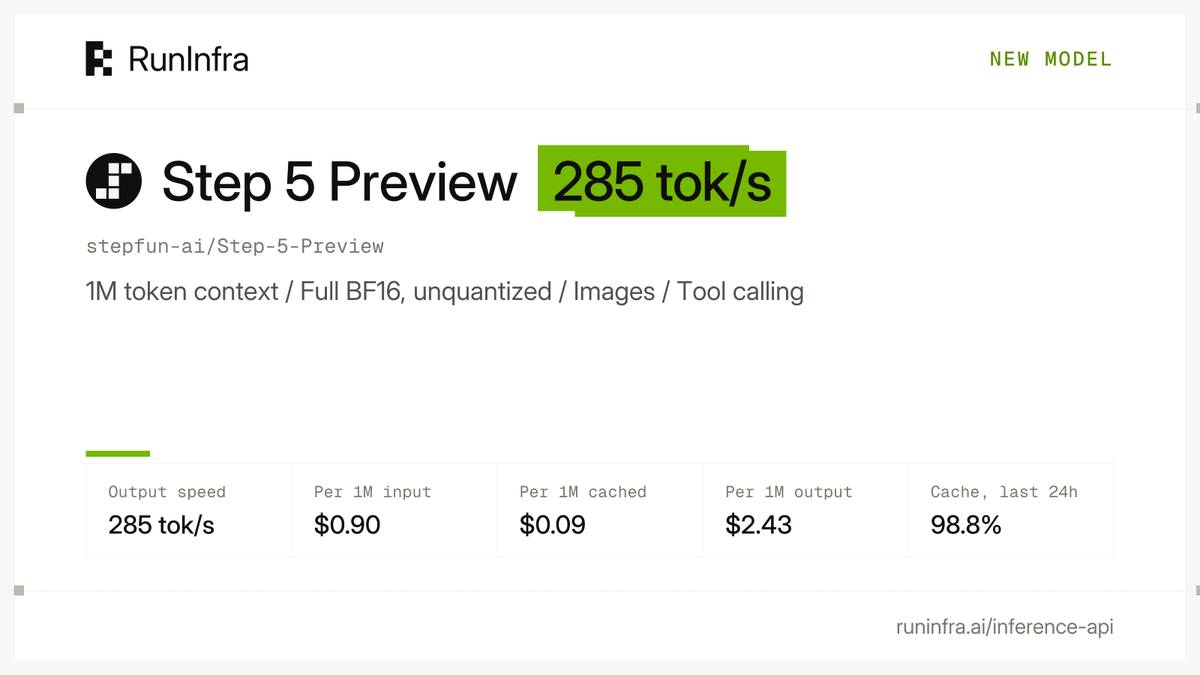
Step 5 Preview from StepFun is live on RunInfra today. served in BF16
285 tok/s output. 46 ms to first token
$0.90 per 1M input, $2.43 per 1M output, $0.09 per 1M cached. 1M token context, up to 1M output tokens
OpenAI-compatible chat completions and Anthropic-compatible /v1/messages. text and image input, tool calling, JSON mode, streaming
zero data retention. never used for training
https://t.co/kJdng3rKm6
last month i was begging gpu providers for b300s at $7.9/hr
now they're begging me to take them at $4.6/hr, no commitment
something big is happening soon. ai gave us all its dessert and now it's time for the veggies
a lot of decision models came out in the last two months. almost all of them work the same way. they read text, wait until the whole input has arrived, and then give you an answer
that works for a support ticket. it doesn’t work for a robot, a phone call, or a video feed, where the input never really ends and the decision has to happen while it is still coming in
so we spent half of our YC money training a model:) RightNow takes text, PDFs, images, voice, code, robot state and video, all in one model, and you can stream up to 1M tokens of context into it. it updates its decision as each piece arrives. on text it decides in 30 ms and we will make it less with our kernel optimization
we trained it with what we call Reflex Training. the current decision models read everything first and answer once. RightNow is trained to decide on whatever has arrived so far, to hold back until the evidence is there, and then commit. it serves on what we call Reflex Architecture which keeps a probability for every option and updates it as each part of the input comes in
we call this kind of model “System Zero”. system 1 is fast thinking and system 2 is slow reasoning. system zero is the step that comes before both, which is just deciding
we will publish a technical paper on Reflex Training and Reflex Architecture. the model itself will stay closed source and available via RightNow API
this is our first checkpoint and it’s still a little buggy. we launched it early because the fastest way to make it good is to have people use it:)
RightNow is out today. our first “System Zero” model
it streams in text, JSON, PDFs, images, voice, codebases, robot state and video, and returns a decision with a probability for every option while the input is still arriving
30 ms decisions on text. up to 1,024 questions in one call. output is free
system 1 is fast thinking. system 2 is slow reasoning. “System Zero” is the step before both -- the decision itself
this is our first checkpoint. there is a lot of work ahead, and we decided to ship early to get your feedback. more features and fixes are shipping this week, with more checkpoints after
https://t.co/U4OVHUMoW7
glm 5.3 flash just got 51% cheaper on runinfra
$0.05 per 1M input, down from $0.11. $0.01 per 1M cached input, down from $0.03. $0.22 per 1M output, down from $0.45
99.3% cache hit rate over the last 24h. most of your input tokens are billing at the cached rate
that puts a full 1M context prompt at around 1 cent on a cache hit
same speed: 254 tok/s, 703ms TTFT
discount runs until nov 4, then standard rates resume automatically
https://t.co/yQu86fPIS0
runinfra coding plan is live
the fastest open models in claude code, codex, opencode and 16 more agents. from $10 a month
more usage per dollar and faster tok/s than other providers. both, not one or the other
DeepSeek V4.1 Flash, GLM 5.3, Ornith 1.5 122B, Qwen3.8 27B and more. one sub
up to 378 tok/s. up to 99.3% cache hit. cached input from $0.01 / 1M, so the plan goes further
$10 → ~$12 of usage
$29 → ~$35
$99 → ~$119
limits reset every 5 hours and every week. hit one and you pick: credits, or free standby. never a dead stop mid-task
setup is one prompt -- paste it into your agent and it wires itself
https://t.co/MZWSyyWbVj
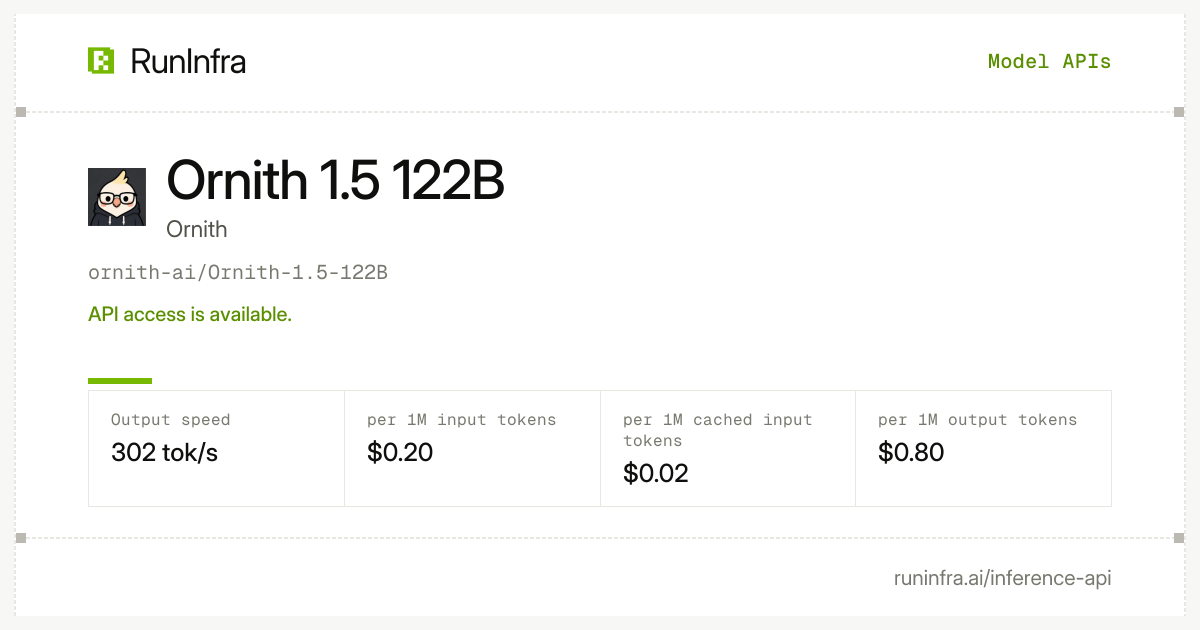
Ornith 1.5 122B is live on runinfra. launch partner with @ornith_ , live from hour 0
302 tok/s output. 72ms to first reasoning token
$0.20 / 1M input. $0.02 cached. $0.80 output
99.1% cache hit rate on agentic workloads
one of the best models we've served for its size. 10B active and it holds up on real agent work
OpenAI-compatible chat completions and Anthropic-compatible /v1/messages -- drop it into claude code as is
zero data retention by default
https://t.co/qoScb3k13i
DeepSeek V4.1 Flash 1017 is live on RunInfra
hour 0 support. day 0 is for slow teams
327 tok/s output. 30ms to first reasoning token
$0.15 per 1M input, $0.60 per 1M output, $0.01 per 1M cached. 1M token context
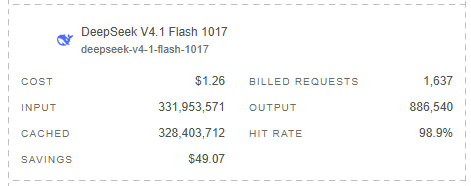
cache hit rate stays above 98% on agentic workloads. every hit and miss shows up in your dashboard, so you can check it yourself
OpenAI-compatible chat completions and Anthropic-compatible /v1/messages. text and image input
zero data retention. never used for training
https://t.co/NDnKRRW6FR
half of all input tokens on runinfra now come from agents running at 97%+ cache hit
over the last 48h, those agents averaged 98.7%. the best one hit 99.7%
same agents, by model:
DeepSeek V4.1 Flash: 98.8%
GLM 5.3 Flash: 98.4%
cached input is $0.03 / 1M. every hit and miss shows up in your dashboard
https://t.co/Tk7EMOI9UC
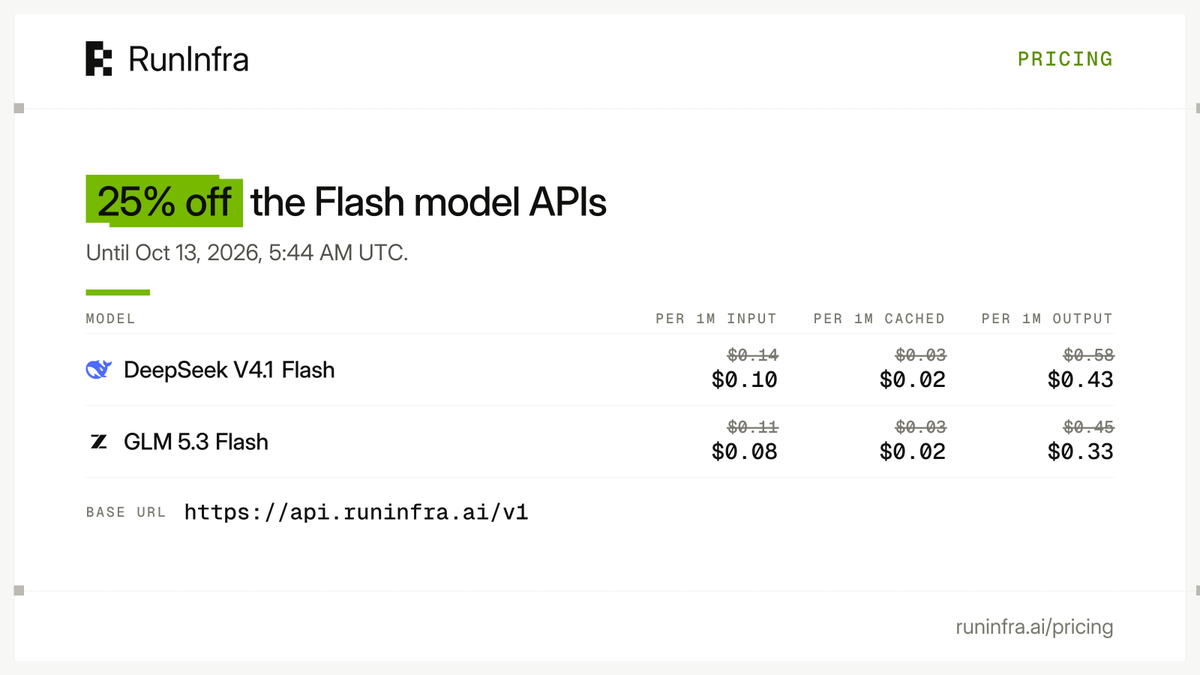
25% off DeepSeek V4.1 Flash and GLM 5.3 Flash on RunInfra. live now through oct 13
DeepSeek V4.1 Flash
- input $0.14 → $0.10/M
- cached $0.03 → $0.02/M
- output $0.58 → $0.43/M
GLM 5.3 Flash
- input $0.11 → $0.08/M
- cached $0.03 → $0.02/M
- output $0.45 → $0.33/M
rounded down in your favor -- up to 33% off per line. same API, same speed
https://t.co/SgeZpna8W6